Single API Abstraction Across LLM Providers
Eliminate vendor lock-in and manage multi-provider complexity at the infrastructure layer.
Picture a team that has been running everything through OpenAI for a year. Then a product decision calls for Claude on a specific workflow. Within a week, that complexity has bled into your application code, and it only gets worse as you add more providers. Nothing about this is a failure of engineering discipline. It is what happens, predictably, every time a second provider enters the picture, because each provider ships its own SDK, its own auth scheme, its own error taxonomy, and its own retry conventions, and none of these are built to talk to each other.
The pain appears first in credentials. Meanwhile, rate-limit handling, fallback logic, and usage logging get rebuilt from scratch in every application that touches a model, so the same infrastructure problem gets solved several times, inconsistently, instead of once. A gateway comparison from the DEV Community describes this exact pattern: teams managing different API keys, provider-specific SDKs, rate limits, retries, model fallbacks, and usage reports, each handled in isolation. The fix is not better documentation or a stricter code review process. It requires moving that complexity out of application code and into infrastructure built to carry it.
What an LLM gateway does architecturally
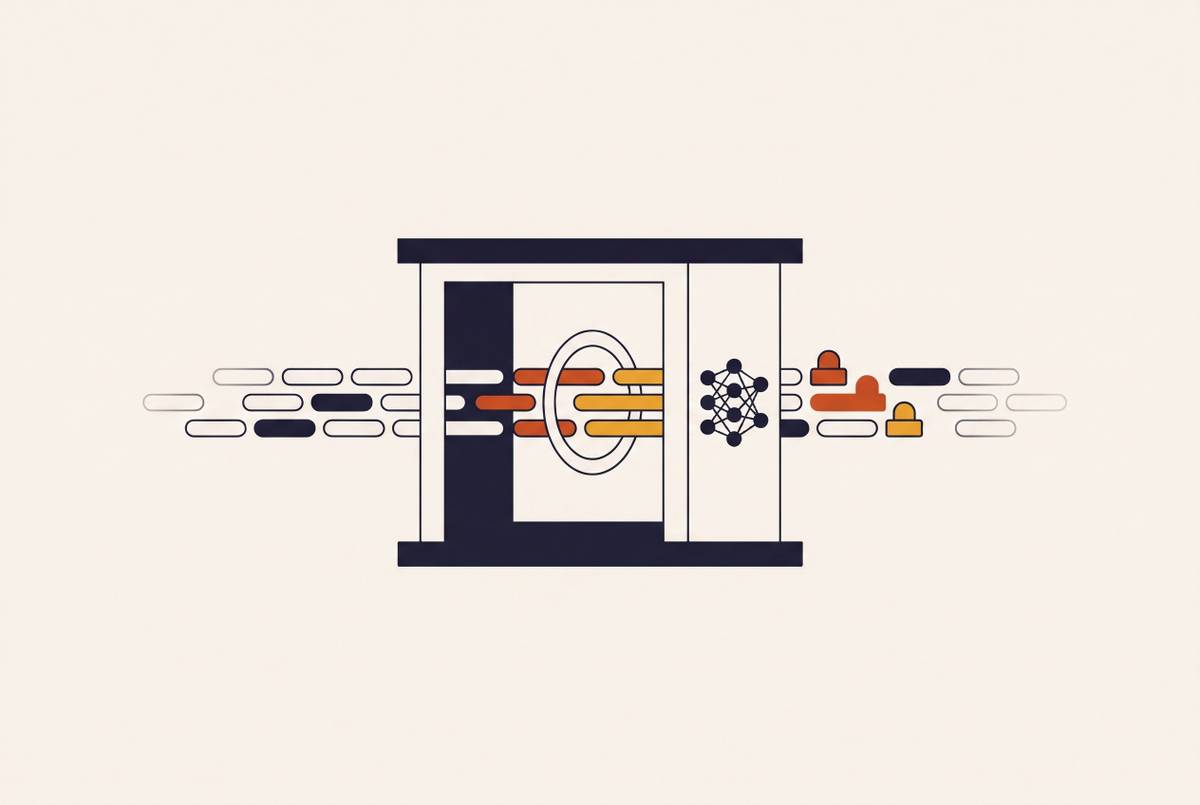
An LLM gateway is a reverse proxy. It sits between your application code and every model provider, so your code only talks to one stable endpoint, and the gateway owns everything behind it.
The flow is straightforward: application sends a request to the gateway, the gateway sends it on to a provider. Your code just sends requests to a single endpoint, usually one shaped like the OpenAI API. The gateway decides which provider and model should actually handle the request, authenticates using the real provider key it holds centrally, applies whatever policy the organization has set, executes the call, meters the tokens consumed, and logs the result. A 2026 explainer from Atlan frames this as a traffic controller for model API requests, handling routing, rate limiting, cost tracking, auth, caching, and guardrails inside one layer.
The OpenAI-compatible surface means you can swap which model or provider sits behind the gateway, and not one line of your application code has to change. That portability is the entire point of the abstraction.
A gateway built for production has to handle a defined set of responsibilities: token-based rate limiting, multi-provider model routing, semantic caching, prompt injection defense, support for agent protocols like MCP, cost attribution and budget controls, auth and key management, and structured logging. Zuplo's 2026 AI gateway guide says this is the first real line between a gateway built for AI workloads and a generic API gateway that got repurposed for the job. As agentic workflows have become a larger share of what gateways need to support, the scope of what this layer governs has grown well past simple request routing. This is why the economics of routing itself become worth examining closely.
How routing decisions translate into cost savings
The gateway decides which model handles each request, so routing strategy is the biggest lever you have over AI spend. Routing exists in the first place because no provider wins on every dimension that matters. Benchmarks from 2026 show that the fastest provider on raw time-to-first-token, the one with the highest throughput, the one with the lowest cost per token, and the one with the highest coding quality scores are four different providers, not one. A gateway that sends every request to a single model is leaving savings and performance on the table by construction.
Three routing strategies exist, increasing in complexity and in how much they return. The simplest approach routes by task type or by characteristics of the prompt itself: static rules that cost nothing to maintain and capture most of the available savings without any ongoing tuning. A step up from that, rule-based routing adds cost and latency thresholds on top of the static rules, and the research estimates this captures somewhere in the range of 60 to 70 percent of available savings. Beyond that sits learned routing, where a system like RouteLLM uses matrix factorization to predict which model should handle a given request: it squeezes out further savings, but it needs labeled data and continual retraining, so the research recommends this tier only once monthly LLM spend reaches a meaningful scale. For most teams, the static and rule-based tiers already do the heavy lifting, and the jump to a learned router is a decision worth making deliberately rather than by default.
A cascade model described in iternal.ai's LLM selection guide shows the economics behind this: the majority of enterprise requests route to a lightweight model, a smaller share route to a mid-tier model, and only a small share route to a frontier model, producing a blended cost that comes in far below what the organization would pay if every request hit frontier pricing. Routing decisions become visible and measurable only when a gateway tracks spend by model, provider, team, and project in real time. Concentrate AI's cost attribution architecture makes these routing decisions immediately transparent, so teams can quantify which strategy, static rules, cost-based thresholds, or learned routing, is actually delivering savings, and adjust their routing logic with confidence. None of this works, though, if routing lives in application code. The gateway has to enforce these decisions as policy, applied the same way across every team and every request, with no developer having to remember to implement it correctly each time.
Why provider outages make multi-provider routing load-bearing, not optional
Provider outages happen often, sometimes at the same time, so routing across multiple providers is no longer a nice-to-have but part of what keeps production systems running. Anthropic's 90-day rolling uptime in early 2026 runs around 98.95 percent, and that sounds close to perfect, but compound it over a full year and you get a meaningful number of hours where the service is not available.
Hard outages are the visible failures. Soft failures are the dangerous ones, because they do not trip the alarms anyone is watching. A gateway has to be built to catch that kind of failure, detecting degraded output quality and routing around it as well as watching for 5xx error codes.
A fallback chain built for production has to separate three distinct categories of failure, each needing its own list of backup providers: general fallbacks for timeouts and server errors, content-policy fallbacks for requests a provider refuses on policy grounds, and context-window fallbacks for requests too large for the primary model. Failing over costs something. Either way, you still come out ahead of the alternative, which is a failed request and zero revenue. The same routing and fallback machinery that keeps requests flowing during an outage also enforces security and compliance, because the gateway has to see and control every request before it reaches a provider.
How the gateway enforces data security and compliance
Every request already passes through the gateway on its way to a provider, which makes the gateway the only point in the system where data security policy can be enforced as requests happen, rather than documented afterward in a policy binder nobody checks against reality. Writing plain-text prompts containing PII, PHI, or PCI data into unencrypted logs, or sending that data to a provider that retains it, creates a fresh regulatory exposure every time it happens. The gateway resolves this by redacting sensitive fields before the request ever leaves the organization's control. Concentrate AI applies this directly: it enforces automatic PII and PHI redaction at the gateway layer itself, so redaction policy gets applied consistently across every request and stays reviewable, and no application team has to rebuild the same protection on its own.
Zero Data Retention is now a formal line item in enterprise procurement. A gateway can enforce ZDR contractually and technically at the infrastructure layer, closing the gap between what a provider offers and what actually happens by default.
The same structured log that tracks spend can also prove compliance, without building two separate systems. One set of structured inference logs, tied to identity, can do both jobs. That only works, though, if RBAC, SSO, and audit logs are actually available to the team that needs them. Gateway vendors often put those controls behind enterprise pricing tiers, so most teams get locked out, and they quietly work around the controls that were supposed to govern them. Governance ought to be available from day one, independent of how large the organization is. Identity needs to travel through the entire request path for any of this to hold together: human callers authenticate through team keys or SSO, service callers use managed identities, and agent callers carry both their own role and the identity of the user and tenant they are acting on behalf of, so a tool call inherits the correct scope and can never borrow authority that belongs to a different tenant.
What governs AI usage as teams and workloads grow
The same teams that started out juggling separate API keys per provider, per team, sometimes per engineer, eventually become the teams that need workspace isolation and budget enforcement at a much larger scale. The gateway's control plane holds that growth together. Enterprise deployments described in the research roll out hundreds of AI models to every team at once, with SSO, role-based access set across multiple layers, approved model lists, regional data residency rules, PII redaction, audit logs, and per-team budgets, all configured through one control plane rather than assembled piecemeal.
That control plane works through inheritance. Controls get set at the org level, the group level, the user level, or the individual key level, covering which models are approved, which region serves the request, whether ZDR applies, whether PII redaction runs, what the budget cap is, and whether audit logging stays always-on. Each layer inherits what the layer above it set, and can be narrowed further down the chain but never widened back out. Without that structure, the alternative is teams provisioning provider access on their own, which produces the exact fragmentation described at the start of this piece, just at a much larger scale: no shared visibility, policy that varies team to team, and spend that only becomes visible once the invoice arrives at the end of the month.
Fast-growing teams carry the most risk here, because AI usage tends to expand faster than internal governance can track it, and the gap between a team adopting a new model and finance finding out about it can run for weeks without a centralized gateway watching spend in real time. A sounder approach gives you those controls at any scale, regardless of whether your organization is large enough to negotiate an enterprise contract. Whether an organization can get that kind of governance without building it from scratch is exactly the question that decides whether a team should build its own gateway or buy one.
Evaluating gateway options: managed services versus self-hosted
The build-versus-buy decision resolves quickly once the actual requirements are laid out. A gateway has to do a lot: reverse-proxy every request, authenticate centrally, meter tokens, apply routing policy, detect soft failures, redact sensitive fields, enforce ZDR, and tie identity through every layer of an agent's tool calls. Building all of that from scratch is a serious infrastructure project, not a weekend script, and it comes with an ongoing maintenance burden that grows with every new provider and every new compliance requirement.
A managed gateway centralizes that provider-specific complexity into one infrastructure layer from the outset, so your application code stays stable no matter how many models or providers you add later. So when you check any option, managed or self-hosted, run it against this short list.
Confirm the gateway presents an OpenAI-compatible endpoint, because that is what lets you switch providers without touching your code. Check whether rate limiting runs on tokens instead of raw request counts, because request-count limits tell you nothing about what you actually spend on AI. Look for routing that supports static rules at minimum, with a clear path to cost-and-latency-based rules as usage grows, without forcing a team into a learned router before it has the volume to justify one. Ask whether the fallback logic distinguishes general failures, content-policy failures, and context-window failures, because most implementations cover only the first and leave the other two unhandled. Verify that PII and PHI redaction happens at the gateway layer itself, before any request reaches a provider, so no application team has to build that protection on its own. Confirm you can enforce ZDR contractually and technically, and don't leave it to each provider's own default setting. Check that structured logs tie spend and compliance data to identity in one place, so your finance and compliance teams can work from the same record instead of building duplicate systems. Finally, check where RBAC, SSO, and audit logging are placed in the pricing structure: controls locked behind an enterprise tier leave smaller or faster-growing teams without governance exactly when they need it most.
Weigh a self-hosted gateway against those criteria, and you get more control over infrastructure, but you have to own every one of those responsibilities indefinitely. A managed option built around them from the start gives you the same governance, routing, and compliance posture, and you never have to build or maintain it alone.