Thundering Herd Problem in LLM API Gateways
How API gateways prevent synchronized retries from overwhelming LLM providers.
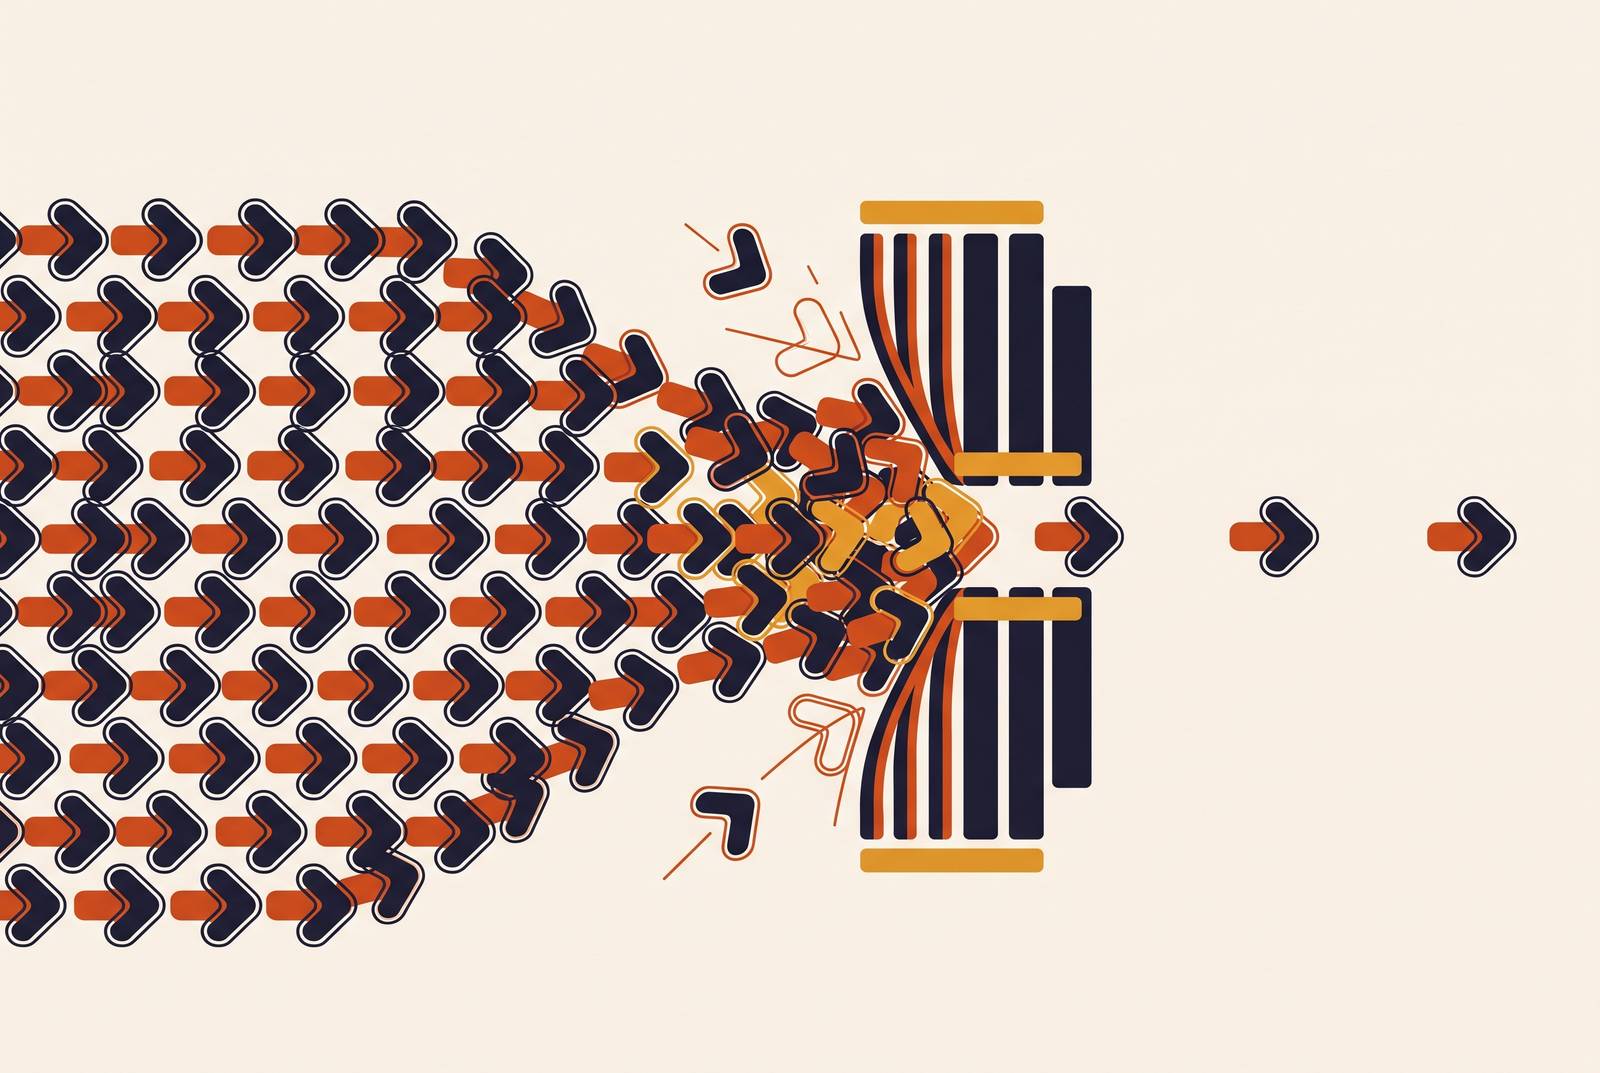
The thundering herd problem is the mathematically predictable outcome of naive retry behavior at scale, and multi-provider LLM deployments have made the conditions for it nearly universal. The mechanism is simple: when a popular resource goes unavailable, every client waiting on it unblocks at the same moment and hits the same downstream service simultaneously, multiplying load with request volume instead of smoothing it out. The textbook version of this is a set of processes waking from a sleep() call and hitting a database all at once. In an LLM stack, this pattern appears as a sudden cluster of rate-limit errors the instant a rate-limit window resets.
Pure exponential backoff without jitter is the proximate cause. Every client computes the identical wait time off the identical formula, so they all retry at the identical moment, recreating the herd on the very next attempt. The naive response to a 429, wait and then retry, is wrong twice over: the rate-limit window has likely not reset, and synchronized retries guarantee a second collision.
Three conditions in modern LLM stacks guarantee this herd will form without deliberate mitigation. If TTLs on shared cache keys are short, every client under high traffic hits a cache miss at the same instant, and a routine expiration turns into a synchronized stampede. Service restarts and deployments clear warm caches outright, so you get a brief but severe herd on hot keys like routing tables or feature flags. If circuit breakers retry immediately on failure, they stop acting as safety valves, and instead they behave like feedback-controlled load generators that amplify the exact failure they were built to contain.
Rate limits make the collision worse because providers enforce two independent axes at once: requests per minute and tokens per minute. A burst of traffic can trip either limit on its own, and both produce the same synchronized retry behavior once they fire. Industry-wide API uptime fell measurably between Q1 2024 and Q1 2025, a meaningful rise in downtime year over year, because demand growth outpaced infrastructure scaling, and rate-limit errors now make up a significant share of LLM errors seen in production telemetry. A single provider can absorb a synchronized retry storm like this without much drama. Three to thirty providers cannot.
The Multi-Provider Model Landscape Makes the Problem Structurally Worse
The LLM provider landscape has fragmented rather than consolidated, and plenty of teams that believe they run a single-provider stack are already routing to fallbacks without realizing it. Every provider that advertises "OpenAI-compatible" delivers compatibility only on the surface. Underneath the surface-level "OpenAI-compatible" label, the incompatibilities pile up and multiply the coordination burden any team has to carry.
Token counting is one source of drift: the same prompt produces different usage numbers across providers because each one counts special tokens differently, which throws off both billing and rate-limit tracking. Error formats are another: some providers return {"error": {"message":...}}, others return {"error": {"code":...}}, and some return an HTTP 200 status with the error buried in the response body, so every format needs its own handler written and maintained. Function calling schemas compound the problem further. A schema that works cleanly on one frontier model can silently fail on another because JSON Schema validation strictness differs between them, and the failure mode is quiet: the model still gets called, but it invents parameters instead of raising an error.
Picture what this looks like inside an application codebase with three providers wired in directly. There are three SDKs, three authentication schemes, three response parsers, and three separate retry-and-backoff implementations, each one written by whoever touched that integration last. Without a coordination layer, that retry and backoff logic is not just duplicated. It diverges, because nothing forces the three implementations to agree on timing, jitter, or thresholds. When one provider's rate limit fires, there is no shared state anywhere in the system to tell other in-flight requests to hold back, so the herd forms across provider boundaries and client boundaries at the same time.
Failover looks like the fix for this, but handled naively it makes the herd worse, not better. The fallback model often cannot support what the primary one did: a primary with 128K context might fail over to a model capping out at a fraction of that, a primary with vision support might fail over to one without it, a primary that handles function calling in streaming mode might fail over to one that cannot. There is a cost dimension too. A 429 on a cheap model that fails over to a frontier model can cost an order of magnitude more for the duration of the outage window. And failing over mid-conversation means resending the entire conversation history to the new provider, re-tokenizing it under a different counting scheme, and risking a context-limit breach that the original provider would never have hit. None of this is an argument against multiple providers. It is an argument against coordinating them by hand, one retry block at a time, inside application code.
How a Gateway Breaks the Synchronization That Causes the Herd
A gateway is the one place in the system where shared state can exist, which makes coordinated, non-synchronized behavior possible for the first time and eliminates the thundering herd. Without a gateway, every client carries its own private view of rate-limit state, its own backoff timer, and its own sense of provider health. Nothing lets one client's 429 inform another client's next request, so the herd is a structural guarantee rather than a risk to be managed.
With a gateway in place, every request has to pass through a single control plane before it reaches a provider. The gateway sees aggregate demand across the entire fleet of clients, can hold requests before they go out, and applies mitigations globally, so no client has to fend for itself. One mitigation is provider-level circuit breaking and fallback: the gateway monitors per-model health and routes around failures before they propagate, depending on that shared vantage point.
The first is full jitter on backoff. The correct formula is sleep = random_between(0, min(cap, base × 2^attempt)), which spreads retries across the entire interval instead of letting them cluster at the edge of it. Staggered, jittered backoff cuts the odds of a second-generation herd forming right after the first collision, because the retry attempts land spread out across a wider window rather than piling up together. Applied at the gateway, that jitter is consistent for every caller. Applied inside application code instead, it varies by SDK version and by whoever implemented it, so clusters still form even when jitter is nominally in place.
The second mitigation is distributed rate-limit awareness. The gateway tracks shared knowledge of both RPM and TPM headroom for each provider and enforces a request queue that respects both axes before anything gets forwarded. A client-side rate limiter can only see its own traffic. A gateway sees every client's traffic together and can enforce the real provider-level budget across the whole organization, not just one corner of it.
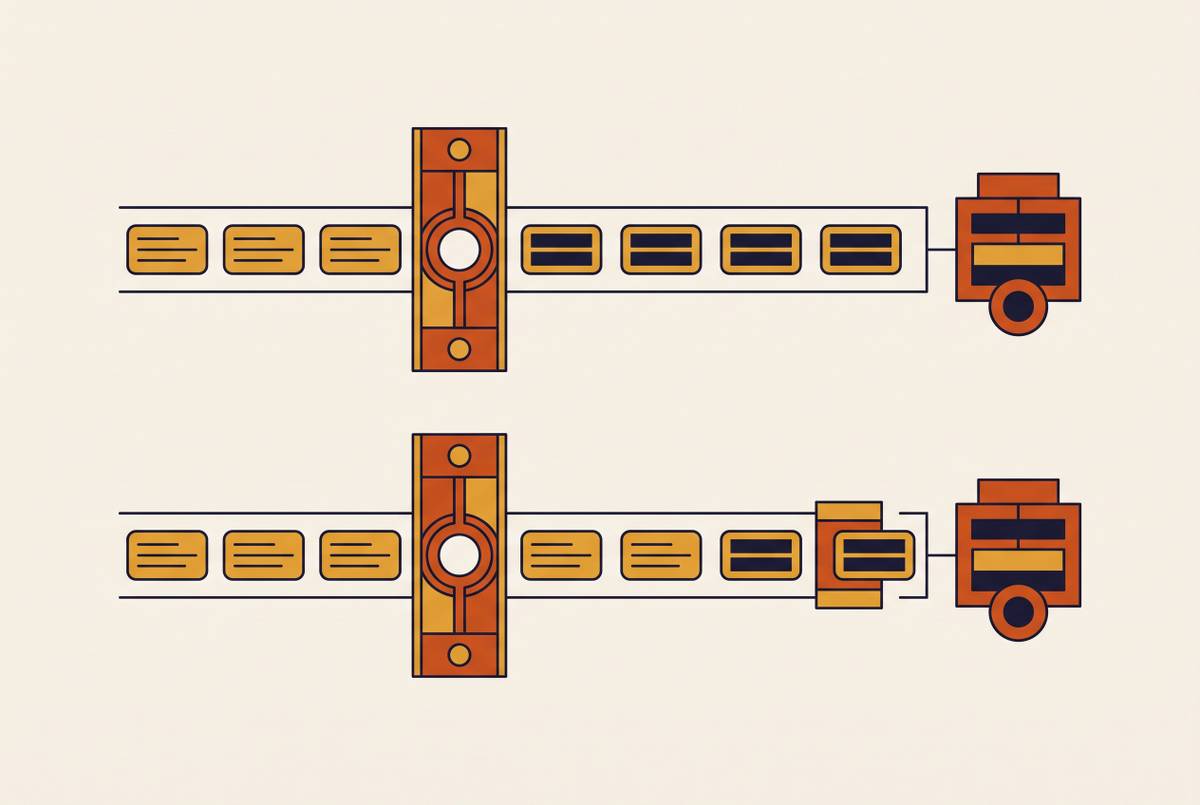
The third is request coalescing through distributed locks and caching. When several clients fire off the same or a near-identical prompt at the same moment, the gateway lets one request through and holds the rest until that first response comes back. The common implementation is a Redis SETNX lock: the first request acquires the lock, makes the expensive call to the LLM, populates the cache, and releases the lock, while the requests that were waiting poll and get served the cached response, so only one provider call happens for however many clients asked for it. A TTL on the lock prevents a deadlock if the request holding it crashes mid-flight. Exact-match caching covers identical repeated prompts, and semantic caching extends the same idea to near-duplicates, and both flatten spikes right at the provider boundary before they ever become a problem downstream.
The fourth is provider-level circuit breaking and fallback. The gateway tracks health per model, not just per provider, so it can route around a failure before it spreads. That per-model granularity matters because a single provider can have one model degraded while another model from the same provider is fully healthy. Rather than retrying aggressively into a failing model, a well-built gateway can return a stale cached value while the circuit is open, which avoids piling on more load exactly when the system can least afford it.
Put together, the full request lifecycle through a gateway runs: authenticate, check rate limits, check cache, select provider, format the request, send it, and on a 429 or 5XX response retry with backoff or fail over, then log and return. The calling application never has to see any of that complexity. A minimum viable resilience stack chains these: a request queue enforcing dual TPM and RPM limits, a circuit breaker with both error-rate and cost-threshold triggers, exponential backoff with full jitter, and secondary provider routing triggered by a 429, a 5XX, or a latency threshold breach.
Latency and throughput constraints that determine whether the gateway itself becomes the bottleneck
None of this works if the gateway cannot handle the aggregate load it is now responsible for. At high concurrency, the language a gateway is built in and the way it is deployed decide whether it holds steady or becomes the new failure point. This is the honest counterargument to everything above: centralizing coordination also centralizes risk, and that tradeoff has to be evaluated on real numbers rather than assumed away.
Memory and concurrency behavior under load is visible clearly at high concurrency. At high requests per second, LiteLLM's memory usage has been measured climbing past 8 GB, with third-party stress testing putting peak usage closer to 11.8 GB, and P99 latency rising sharply once traffic passes a single instance's comfortable throughput ceiling. The limiting factor here is Python's concurrency model, not the logic of the gateway itself.
Benchmark numbers can also mislead in a specific way. A time-to-first-token health check that sends a short probe prompt says very little about real-world latency on a long prompt, where the same model can run ten times slower than the health check suggested. If you evaluate a gateway on a quick synthetic benchmark, you are evaluating the wrong thing.
Geography adds a latency cost that is easy to overlook until it appears in production. If you route users in one region through providers hosted in another, you add 150 to 300 milliseconds of pure network latency on every request, and across a multi-turn conversation that compounds into several seconds of wasted time. Edge-deployed or region-aware gateways reduce this directly. A centrally hosted, self-managed instance does not, no matter how well-tuned its internal logic is.
All of this points to the same underlying fact: a gateway sits on every piece of traffic passing through the system, which makes it a single point of failure by definition. That means its own reliability, its deployment model, and its operational posture need to be selection criteria from the start, not details worked out after the fact. Whether you build this layer in-house or adopt a managed option, you have to evaluate memory behavior under sustained load, realistic latency on real prompt lengths, and geographic placement relative to where your users actually are. None of these are optional line items. They decide whether the gateway fixes the synchronized-retry collisions or simply moves them one layer up the stack.
Observability at the gateway level turns herd events from incidents into signals
Standard monitoring, request count, error rate, and P99 latency, is not enough once traffic routes across many models. Distinguishing a herd that is actually forming from ordinary traffic variation requires observability broken out per model, per provider, and per feature. A single aggregate error-rate graph can look calm even while one specific model, behind one specific provider, is about to fall over.
The signals that mark a herd forming have a distinct shape once they're broken out at that resolution. A sudden cluster of rate-limit errors appears right after a rate-limit window resets, and it arrives as a simultaneous spike across many clients rather than a gradual climb. If latency spikes persist for minutes rather than seconds, that points to queued clients all retrying inside the same window, not to one-off slow requests. When CPU and connection-count spikes line up with cache-miss events or deployment timestamps, they point to the expiration-storm and restart mechanisms described earlier, now visible in the telemetry rather than inferred after the fact.
Gateway-level logging also makes per-model observability possible in a way that application-level logging rarely does. Cost tracking broken down by model, by endpoint, and by feature, rather than one total spend figure, gives teams the data needed to evaluate whether a routing decision was sound and to catch an unexpected cost spike the moment a failover event sends traffic to a more expensive model. Quality metrics tracked per model, things like JSON validity rate and tool-call success rate, catch the kind of silent degradation that a function-calling schema mismatch produces, long before it shows up as a customer complaint.
This is where a dedicated gateway layer earns its place in the stack, not just as a router but as the point where rate-limit awareness, backoff coordination, and fallback logic all share one source of truth. Concentrate AI, for instance, centralizes that shared state so that when one client hits a 429, the signal reaches every other in-flight request immediately, letting jitter-based backoff and request coalescing work across the whole client fleet instead of inside isolated silos.