NER and ML-Based PII Detection Inside the LLM Gateway Layer
Protect LLM pipelines by layering regex, NER, and classifiers at the gateway.
Sensitive customer data should be detected and redacted at a mandatory LLM gateway before prompts reach a model provider. Production-ready enforcement combines regex, named entity recognition (NER), and context-aware classification across user input, retrieved context, tool traffic, and model responses. Blocking and structured audit records make that detection an enforceable control.
How to enforce sensitive data redaction at the LLM gateway
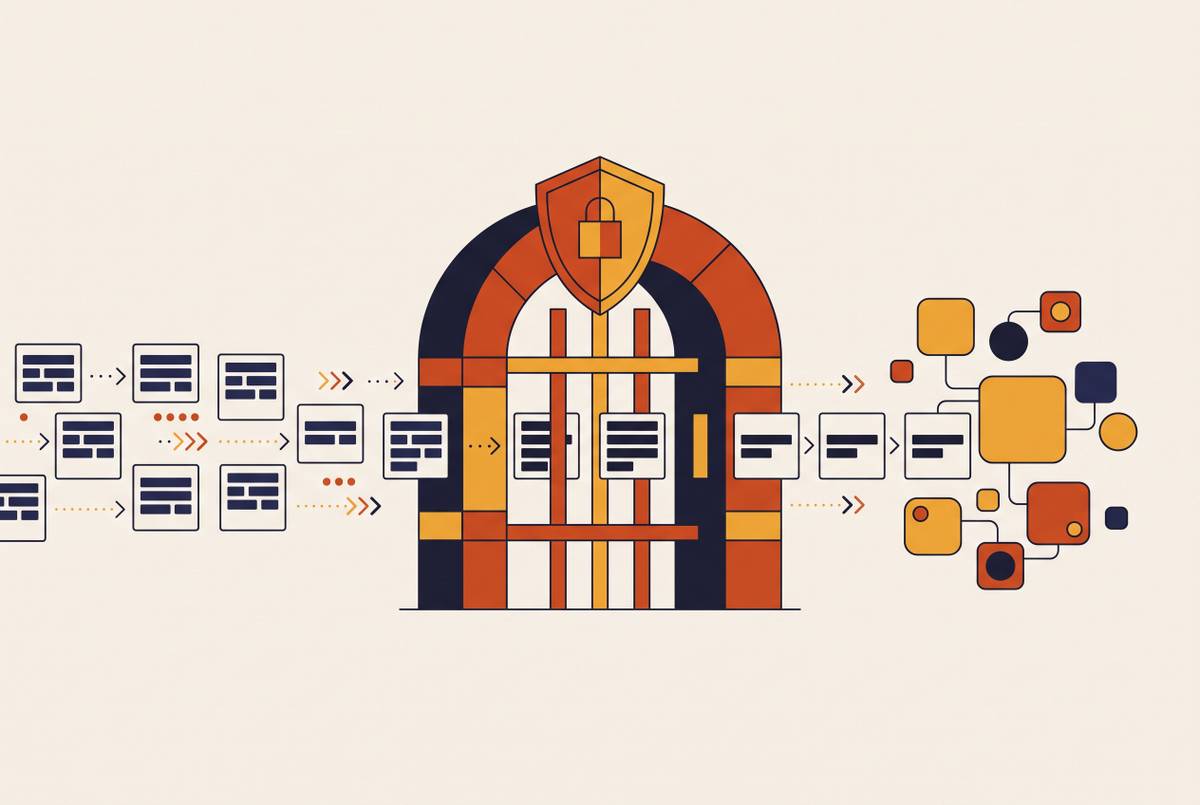
A gateway can apply a universal policy only when every request and response passes through it, regardless of the application team, provider, or pipeline involved. Mandatory passage is the structural advantage. Instead of relying on each developer to implement the same checks correctly, the organization has one enforcement point with a reviewable decision for each request. A route that bypasses it also bypasses its protection.
A model can reproduce memorized PII in response to an unrelated query, leaving no single application code path to patch. The gateway therefore needs filtering in both directions, with egress checks on prompts headed to providers and ingress checks on responses coming back. Clean inputs do not guarantee clean outputs.
The provider boundary makes timing decisive for healthcare, fintech, legal, and insurance workloads. Once an unredacted prompt crosses that boundary, its sensitive content has left the organization’s control and may enter provider logs or future training data, depending on the provider’s handling of it. Enforcement must precede delivery.
Where PII actually hides in an LLM pipeline
User input is the most visible entry point because it contains what a person types directly into the application. It is also the point many pipelines guard first and stop at. Yet the user usually knows what they sent, while other content may be added to the prompt without their knowledge. The visible text is only one input surface.
RAG-retrieved context brings in documents from internal tickets, wiki pages, and CRM notes. Those documents may not have been scrubbed during indexing, so their PII enters the context window before an output filter can intervene. Tool results are another source, with data from customer-lookup responses, database query results, and an MCP server. Here, personal data often arrives by design. Tool call arguments pose a similar risk because an agent can send sensitive data into an action as it runs, before an output guardrail sees it.
Model output is the fourth surface, including sensitive information recombined from context or, in rare cases, reproduced from memorized training data. The categories extend beyond obvious identifiers such as SSNs, passport numbers, and credit card numbers to contact details, health and biometric data, and financial records. Combinations create a less visible identification risk. Age, ZIP code, and occupation can act as quasi-identifiers even when each value seems harmless on its own. Covering all four surfaces therefore requires methods that work at different layers and speeds.
How the tiered detection stack works — regex, entropy analysis, NER, and external classifiers
Regex forms the first tier because structured identifiers often have recognizable patterns. It operates in sub-millisecond time, is deterministic, and is easy to audit. Checksums strengthen some recognizers, including Luhn validation for credit card numbers. WSO2’s built-in regex guardrail illustrates the boundary by detecting well-formed email addresses and phone numbers without catching the free-text statement “John Smith mentioned he lives on Maple Street.” Fixed patterns cannot interpret that sentence’s entities.
Entropy analysis supplies a second, narrower layer for semi-structured secrets such as API keys and tokens. These may lack a fixed format but exhibit high entropy or recognizable prefixes that distinguish them from ordinary prose. NER then addresses unstructured entities, including people, locations, and organizations, commonly through an ML model such as spaCy. This tier adds tens of milliseconds to each request. Its contribution is entity recognition where punctuation and digit patterns provide little help.
Microsoft Presidio combines regex, rules, checksums, and an NER model such as spaCy’s en_core_web_lg in a self-hosted framework. Its pre-configured recognizers include PERSON, EMAIL_ADDRESS, PHONE_NUMBER, CREDIT_CARD, and US_SSN. A representative extension uses a custom PatternRecognizer for a domain-specific identifier such as an MRN. Encryption-based reversible masking through AES is also supported. A vault map, however, must be built separately by the user.
An external PII API or LLM classifier forms the fourth tier for contextual ambiguity that the lower tiers cannot resolve, adding hundreds of milliseconds. The operating principle is to chain cheap checks first and reserve expensive classification for workloads whose compliance requirements justify it. Detection and action remain separate choices. Mutation mode rewrites sensitive content and allows the request to continue, while validation mode detects a violation and blocks it. Removal, masking, and deterministic non-reversible hashing offer different treatments, with different consequences for the meaning available to the model.
Where NER structurally breaks down in LLM workflows
Traditional NER expects cleaner text and language patterns that change less than those in an LLM pipeline. Real prompts contain typos, abbreviations, partial references, pasted chat logs, and broken sentences. The mismatch is structural. Protecto identifies messy inputs, multilingual prompts, cross-paragraph dependencies, and format drift among the major gaps that limit NER in these workflows.
A non-standard name such as “J. Smith-Rodriguez” may escape recognition, while “onboarding thread” may refer to a specific customer record without looking like an entity at all. Mixed-language prompts introduce another mismatch when a single-language model cannot recognize person-reference signals in the other language. This comes up often when customers send traffic from around the world. Long contracts, legal filings, and medical records also spread clues to a person’s identity across paragraphs, so labeling each entity on its own cannot resolve them.
Business terminology adds a moving target because “customer ID,” “client ref,” “user token,” and “membership code” can refer to the same underlying identifier. A trained model does not learn those changes on its own. Keeping pace through continuous retraining is difficult in real-time systems, and domain-specific identifiers such as policy IDs can remain unrecognized. Threshold changes cannot supply missing contextual knowledge.
Recognition can also be too broad, flagging organization or product names in ways that generate noise and weaken confidence in the control. That creates pressure to relax enforcement, even while paraphrased or obfuscated PII remains undetected. NER alone cannot provide the context-aware reasoning across paragraphs and conversation turns that a hybrid approach adds.
How the hybrid approach — regex, NER, and LLM classifier together — closes the remaining gaps
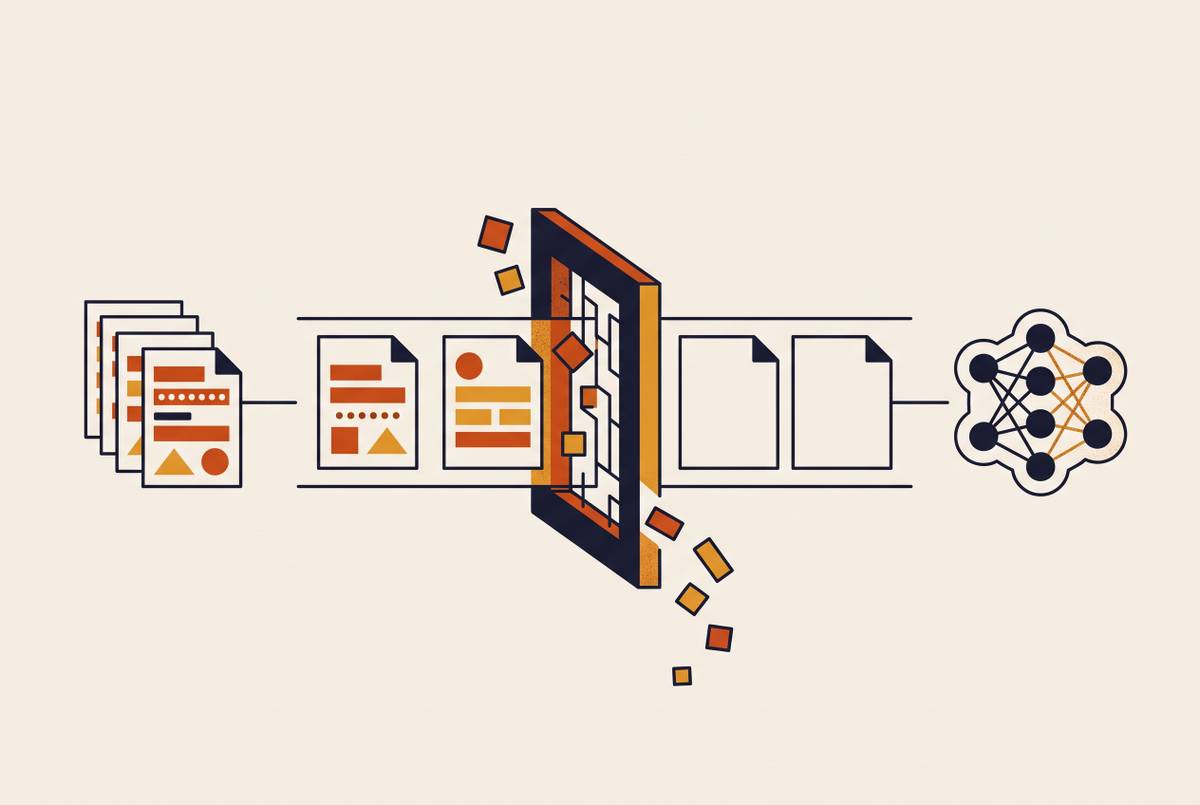
The hybrid architecture assigns different kinds of evidence to different detectors. Regex resolves structured cases without ML overhead, NER identifies freeform entities, and an LLM classifier evaluates surrounding context. The classifier can assess whether a paraphrase, a reference across turns, or a combination of quasi-identifiers discloses personal information that neither pattern matching nor entity labeling would flag.
IBM Research’s Adaptive PII Mitigation Framework for Large Language Models, published by Asthana et al., anchors this approach in context-aware analysis and policy-driven masking. In its benchmarks, it does better on specific entity types, including passport numbers, than tools that use a single detection method. That supports combining methods rather than treating NER as sufficient. Those results do not guarantee the same accuracy for all workloads or entity categories.
The classifier also creates a separate data-handling obligation because it sees the sensitive text it is meant to detect. A team using external classification must establish whether that step itself exposes PII. The gateway blocks violations found through a pattern match or a classifier score above the configured threshold, while the application handles unclear cases that need context before a human can clear them.
Application-layer handling can also support de-redaction for authorized users, while gateway enforcement supplies centralized policy and audit across services. In an agentic pipeline, the hybrid stack belongs at prompt ingress, retrieved context, tool call arguments, and response egress, with tool results included in the inspected context. This placement prevents an output-only control from becoming the first inspection point after a sensitive tool action has already executed.
The latency and accuracy tradeoffs that shape how a team configures detection in production
Mutation guardrails run synchronously before the model call, so their processing time adds directly to time-to-first-token. NER inference also grows with prompt length, while external classification introduces the largest delay in the tiered stack. The cost sits on the request path.
For production teams, the main NER mitigations are keeping the spaCy pipeline warm, detecting PII in user input concurrently with retrieval already underway, and caching results for identical inputs. Concurrent work reduces avoidable waiting but does not replace inspection of the retrieved material once it arrives. Performance tuning must preserve the inspection boundary.
Teams need to calibrate detection against their own traffic to get accurate results because benchmark results depend on the dataset. A threshold chosen elsewhere may lead to a different mix of false positives and false negatives in production. Both errors impose costs, but different ones. Fictional names and sample values such as user@example.com can inflate apparent leak rates, so an allowlist of known-safe samples helps maintain stability. Obfuscated PII requires coverage in the NER layer and adversarial test datasets, making dataset maintenance an ongoing responsibility.
Removing a token entirely offers the strongest removal but may erase meaning the model needs, while masking preserves structure. Protecto describes how unsuitable redaction can lead a model to invent a replacement or produce a shallow answer. Aggressive detection is not sufficient by itself. Even with managed infrastructure, threshold and mode choices belong to the team’s compliance policy because they determine both disclosure risk and the usefulness of the resulting response.
What the audit trail and enforcement record must capture for compliance to be real
A blocking decision without a structured record establishes a technical control but leaves its operation difficult to demonstrate. Under GDPR, HIPAA, or CCPA obligations, the record needs to connect what was detected and blocked to the policy version that governed the decision. Openlayer records pass/fail results, the threshold value, and the model version hash at evaluation time. The entity category belongs in that record too.
Access to those records requires its own controls because audit logs can become an attack surface. RBAC and SSO govern who can view logs and who can modify detection policy. Provider-level zero data retention supplies a complementary boundary control. Redaction limits sensitive content sent to the provider, while ZDR constrains what the provider retains under its applicable terms. Neither substitutes for an accurate, blocking inspection before submission.
Deployment choice determines who operates and demonstrates these controls. A self-hosted gateway keeps gateway processing within the organization’s network perimeter, but the organization remains responsible for its compliance and audit requirements. A managed gateway with independent certifications can reduce that infrastructure burden without deciding the customer’s policy for it. For a five-person AI-native healthcare startup, access to SOC 2 Type II, SSO, audit logs, and a BAA without enterprise procurement is therefore a practical selection criterion.
The complete control is detection, blocking, and audit operating at the same mandatory boundary. None can substitute for the other two. That completeness is what makes gateway-layer PII redaction defensible as an operational control rather than a collection of detectors.