Enforcing PII Redaction at the Gateway Before Payloads Hit Any LLM Provider
Catch all PII entry points—user input, retrieval, tool results, and model output—at the gateway.
Sensitive data doesn't leak into an LLM call through one door. It comes in through user messages, through documents a retrieval system pulls in, through the results tools hand back, and sometimes through the model's own output. Any redaction strategy that only watches one of those doors will eventually get walked around by the other three. This piece covers what a gateway has to intercept, how detection runs fast enough to sit inline on every request, and what the audit record needs to hold so a compliance team can actually trust the result.
Application-layer PII redaction's scaling limits across a multi-service AI platform
A company (the writeup calls it Northwind) builds an input-redaction guardrail that scans every user message for sensitive data before it reaches a model. The guardrail works fine. It catches what it's built to catch, every time a user types something sensitive into the chat box. What it was never built to see is a support ticket pulled in through retrieval. An SSN sitting inside that ticket rides straight into the prompt, the model reads it as context, and quotes it back in the response, in plain text. The guardrail never fires, because the guardrail was never watching that door.
Redaction logic built one team, one service, one guardrail at a time produces exactly this kind of failure, as Northwind's case shows. PII can enter a pipeline through four different points: what the user types, what retrieval pulls in, what a tool call returns, and what the model generates. A guardrail that only watches user input catches a fraction of the exposure surface and calls that fraction complete.
Detection, policy, and audit logging are the same problem at every one of those four points, and when each team builds its own guardrail, each team solves that problem on its own, in its own code, with its own blind spots. One team might catch structured data like SSNs and credit card numbers through regex but never check retrieved documents. Another might scrub user input well but have no idea what a connected tool is handing back to the model. These gaps stay unflagged until the specific request that triggers them finally surfaces them to an auditor or an incident. Recognizing that a problem this identical across every service calls for one shared layer that solves it once, for everyone, the same way every time is the fix, not better discipline inside each team.
Where PII enters an LLM pipeline
User input is the door almost every team guards first, and it's usually the least dangerous one. A user who types sensitive personal data into a chat box made that choice, for better or worse, and a basic input scanner can catch it cheaply.
Retrieved context is a quieter risk. Think of a retrieval pipeline that indexes internal support tickets, customer records, or wiki pages without ever scrubbing them first. Nobody made a decision at request time to include whatever PII sits inside those documents, as TrueFoundry's architecture post points out. That's exactly the mechanism behind the Northwind failure: an input guardrail watching the user's message has no visibility into what retrieval just pulled off a server and dropped into the prompt.
Tool results open a third door, and a more direct one. A customer-lookup API, a database query, an MCP server call, these all hand data straight into the model's context by design, not by accident. Truto's MCP security guide gives a concrete example: a helpdesk integration calling something like list_zendesk_tickets can return an entire ticket body to the model, including payment details a customer typed into a support note months earlier. The tool did its job. It just didn't know the ticket body contained something sensitive.
Model output is the fourth door, and arguably the strangest one, because even clean input and clean retrieval can produce a response that contains PII the model recombined from scattered pieces of context, or, in rare cases, surfaced from something memorized during training.
The agentic version of this problem goes further than most teams expect. Research on SlotGuard (Xia and Park, ICML 2026) found that shell debugging commands, process listings, and environment-variable fallbacks can embed credentials into an agent's transcript just through normal tool use, not through anything that looks like a leak. These values often sit inside shell parameter expansion rather than appearing as a clean standalone assignment. Scanners built to catch simple key-value pairs miss them. SlotGuard's 2026 evaluation found it cut credential leakage to 0.0% across planted test values where conventional scanners failed to catch them. And MCP raises the stakes on tool-result exposure generally: instead of a messy N×M web of custom integrations, one MCP server can now funnel raw payloads from Salesforce, Workday, Jira, and other systems straight into a model's context window, as Truto's guide describes. One connector, many sources, all flowing through the same unguarded pipe.
The gateway as the consistent enforcement point
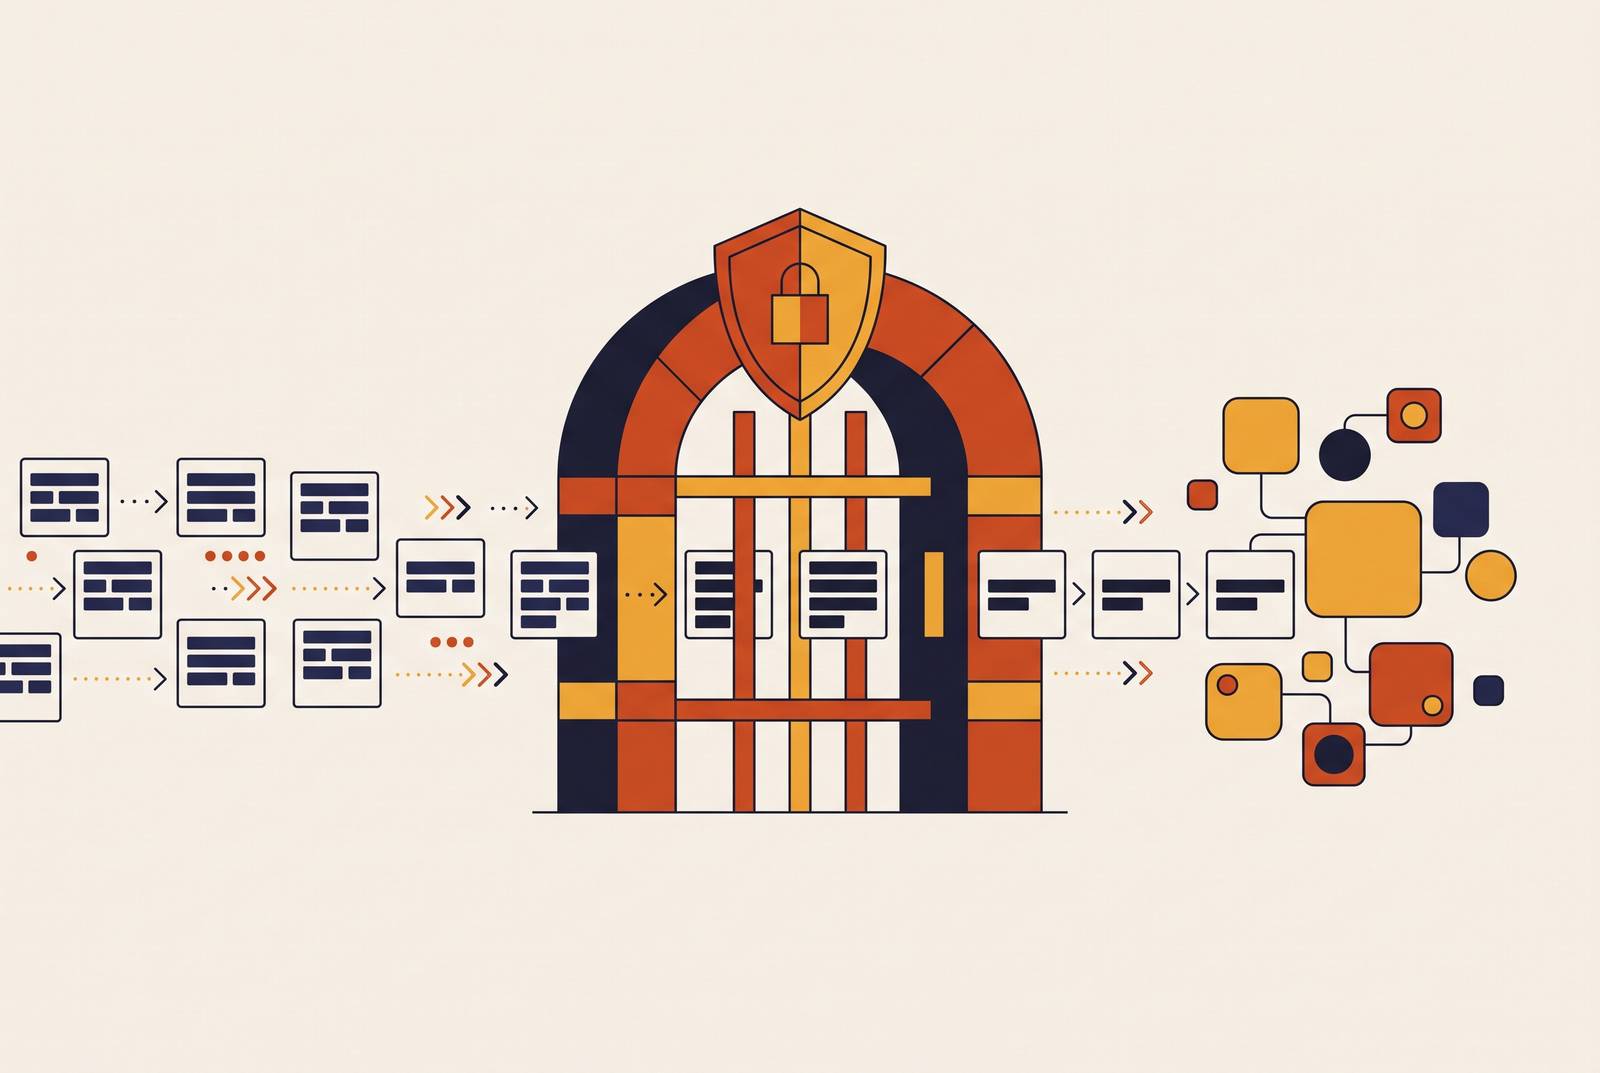
Every request bound for a model provider has to pass through the gateway. That's what makes it different from any guardrail built inside a single application: it's the one place positioned to catch all four insertion points, for every service, without asking each team to build and maintain its own detection code.
The gateway sits right at the boundary between the application and the provider. TrueFoundry's architecture post frames the job: inspect the prompt in real time, flag sensitive patterns, and enforce policy before anything gets sent to the model. That position matters because the gateway sees the entire assembled payload, not just the part the user typed. It sees the user's message, the retrieved context stitched in, any tool results added along the way, and the system prompt, all together, exactly as the model will see it.
Application-layer redaction still has a place. It makes sense when a decision genuinely depends on context only the application has, or when a response needs to be de-redacted for an authorized user on the other end. But those cases are the exception, not the rule, and they don't cover the structural gaps that appear when four different entry points each need their own detection logic rebuilt by four different teams. A unified AI gateway, as Gravitee describes in its writeup on AI gateways, gives an organization one place to govern how its applications talk to LLMs, AI agents, and MCP tool servers, without writing custom filtering logic into every application separately.
Concentrate AI is one example of this pattern in practice. It offers a single unified API across a wide range of model providers. A PII policy gets written once and enforced at that one boundary, no matter which provider a given request ends up routed to or which team sent it. The obvious objection is latency: running detection on every request before it reaches a model adds time to every call. That's a real cost, and the next section takes it on: the answer isn't to give up on gateway enforcement, but to build a detection stack cheap enough that the cost barely registers.
Building a detection stack fast enough to run inline
The guiding rule for inline PII detection is simple: run the cheapest checks first, and only pay for the expensive ones when the workload actually demands that level of accuracy. TrueFoundry's architecture post lays out a tiered stack built on exactly that logic, and the order matters as much as the methods themselves, so it's worth walking through tier by tier.
The first tier is regex with checksum validation. It runs in well under a millisecond and handles well-formatted, structured PII like account numbers, credit card numbers, and email addresses reliably. Because it's cheap and dependable on this kind of data, it belongs at the front of the chain, catching the easy, high-volume cases before anything slower even runs.
The second tier is entropy analysis, which looks for the statistical signature of secrets like API keys and tokens, even when those secrets don't follow a fixed, recognizable format. This matters because a lot of real-world credential leakage doesn't look like a labeled variable. It looks like a long, high-entropy string sitting inside a log line or a shell command, and regex alone won't catch that.
The third tier is a named-entity recognition model, which runs in the tens of milliseconds and exists to catch names, addresses, and other unstructured PII that regex simply cannot reach. There's no regex pattern for "is this a person's name," which is exactly the gap NER is built to close.
The fourth and most expensive tier is an external PII API, running in the hundreds of milliseconds. That cost is only worth paying for high-compliance workloads where accuracy has to be as close to certain as possible, and where the extra latency is a reasonable tradeoff against the cost of a miss.
This tiering lines up with how PII actually breaks down by type. TrueFoundry's post groups it into three classes: structured data like SSNs, credit cards, and emails, which regex with validation handles well; semi-structured data like API keys and tokens, which entropy analysis plus pattern matching catches; and unstructured data like names and addresses, which needs an NER model or an LLM to catch. No single method covers all three well. Regex is strong on structured, well-formatted PII and essentially blind to names. NER catches names but tends to over-flag company names and product names as if they were people. Any team deploying this stack needs to benchmark detection against its own real traffic before locking in thresholds, rather than trusting default settings out of the box.
Microsoft Presidio is a useful reference point for what a production-grade version of this looks like. As TrueFoundry describes it, Presidio combines regex-based recognizers with a pluggable NER backend, spaCy by default, with Stanza and Transformers also supported, and lets teams configure which entity types they care about through a plugin architecture. On the smaller-model side, a study by Acharya and Shrestha found that fine-tuned lightweight models, specifically one compact sequence-to-sequence model and one instruction-tuned open-weight model, can match frontier LLM performance on PII masking across 24 standardized categories. T5-small runs cheaper and produces more controllable structured output, though it loses some robustness on messy, informal text. Mistral scores higher on F1 and recall but takes noticeably longer to generate a response, which matters directly for anything running inline.
SlotGuard's results point at just how fast this can get at the agent-transcript level: its local rewriting step completes in a median of 14.424 microseconds per agent turn, removing structurally sensitive characters without dragging down task success, while generic placeholder redaction drops task success significantly by comparison. Two modes tend to run side by side in a mature pipeline: mutation, which rewrites the PII and lets the request continue, and validation, which detects PII and blocks the request. Mutation mode runs synchronously before the model call, so whatever it costs in latency adds directly to time-to-first-token. That's the clearest argument for keeping the cheap tiers, regex and entropy, doing as much of the work as possible before anything slower ever runs.
Redaction modes and their tradeoffs
Detecting PII only answers half the question. What happens to it once it's found matters just as much, and the three main approaches, placeholder substitution, surrogate replacement, and blocking, trade off privacy against how useful the model's response ends up being.
Placeholder substitution swaps a detected value for a generic tag, replacing a name with [PERSON], for instance. It's privacy-preserving by construction since no real value ever reaches the model, but research on SurrogateShield (Jathanna, Arizona State University) documents the cost clearly: the model receives a query it can no longer fully reason about. A user asking for help drafting a letter gets back a response addressed to [PERSON], technically correct and practically useless.
Surrogate replacement tries to fix that by swapping in type-consistent, synthetic values instead of a generic tag. A name gets replaced with another plausible name standing in for whatever name was actually there, and an account number gets replaced with a structurally valid but entirely fabricated one. SurrogateShield's evaluation measured the payoff: surrogate-substituted messages scored 13.26 percentage points higher on semantic utility than placeholder-redacted ones, using BERTScore with roberta-large. In a 100-query adversarial trial, a prompted LLM adversary trying to recover the original values from surrogate-substituted messages recovered none of them. SlotGuard takes a related approach for agent transcripts specifically: typed, suffix-aware slot rewriting with format-preserving synthetic values, cross-turn references linked through a lightweight session graph, and raw values restored only inside the trusted runtime that's actually authorized to see them.
Blocking is the third mode, and the blunt-instrument option: the request gets rejected the moment PII appears, with nothing passed through in any form. That fits output compliance workloads where even a transformed, synthetic version of the value shouldn't be allowed to proceed, and it's also the correct mode for a small set of entity types that should never, under any circumstance, reach a model.
A practical policy structure layers these three together rather than picking just one. TrueFoundry's post describes per-pattern defaults, where each PII type gets a default action of block, redact, or warn; per-tenant overrides, where, say, a legal team working case files gets permission to pass emails through unredacted because their workflow genuinely needs it; and global hardpins sitting above both of those, where credit card numbers, private keys, and cloud credentials always block, with no override available to any team at any level. For teams that need reversible tokenization, so an authorized user downstream can see the original value, per-tenant key management becomes a real requirement rather than a nice-to-have, since a single shared key across tenants undermines the isolation the whole tokenization scheme is supposed to provide.
What a complete audit trail must capture
A log that only records that redaction happened, without saying what triggered it, tells a compliance auditor almost nothing useful. An auditor doesn't want to know that something was redacted. They want to know what policy fired, what entity type the system found, what mode handled it, and what the actual outcome was, whether the request was mutated and allowed through or blocked.
Zero data retention guarantees rest on three technical pillars working together: dynamic PII masking applied before anything gets transmitted to a provider, a stateless gateway that never writes raw payloads to disk, and audit logging that captures events using metadata rather than the sensitive values themselves. That third pillar is where a lot of implementations quietly fall short. Metadata-only logging that records only "PII detected, action taken" leaves a security team unable to reconstruct what actually happened during an incident, and leaves a compliance team unable to demonstrate, with specifics, that a given policy was enforced the way it was supposed to be. The expansion of PII exposure through tool results and MCP integrations makes this harder to ignore, not easier. Data increasingly flows from external systems straight into a model's context without ever touching a form a user filled out, and a gateway sitting at the boundary is the one place positioned to log that flow the same way no matter where it originated, whether the source was a user message, a retrieved document, a tool result, or an MCP server response. An audit trail that treats every source the same way is the only kind that holds up when someone actually needs to ask what happened, and why.
Sources
- SlotGuard: Stop Oversharing Private Local Context in LLM Agent Transcri
- A Comparative Study of Light-weight Language Models for PII Masking and their Deployment for Real Conversational Texts
- SurrogateShield: Beyond Redaction for High-Utility, Privacy-Preserving LLM Interactions
- LLM Gateway for AI Teams | Concentrate.ai