Enterprise LLM Gateway Standardization Across OpenAI Anthropic and Beyond
A shared gateway layer standardizes costs, routing, and credentials across multiple LLM providers.
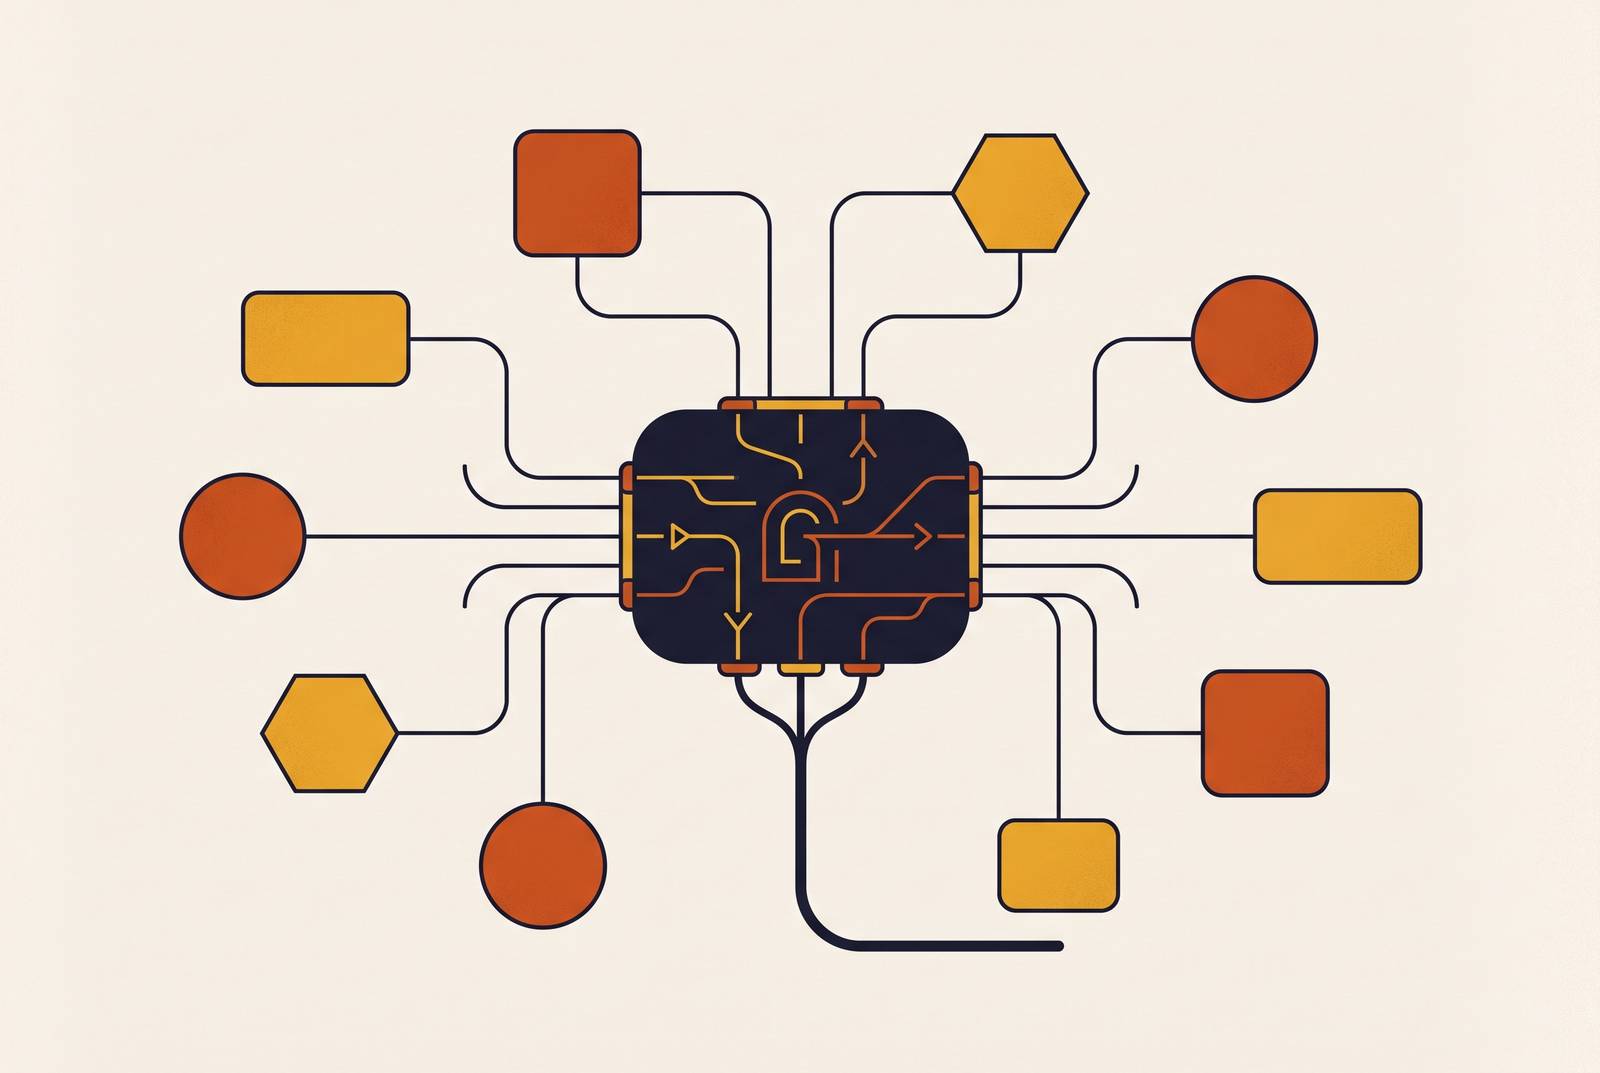
An operations team gets asked a simple question at the end of the month: what did we actually spend on AI last month, broken down by feature. Nobody can answer it. The bill arrives as a single number from each provider, with no reliable way to trace a dollar back to the feature, team, or user that generated it. That's the failure mode this article is about: enterprises running OpenAI, Anthropic, Google Gemini, AWS Bedrock, Mistral, and others at the same time, without a shared layer standing between application code and the providers themselves.
Running multiple LLM providers without a shared layer
Each provider speaks its own language. Error formats differ, even when two providers are handling the exact same kind of request. It becomes a problem the third or fourth time, when three or four services have each written their own version of the same plumbing: their own retry logic, their own fallback chain, their own cost tracking, their own handling of personal data in prompts. Those implementations don't stay identical. Over months, those small inconsistencies stack up into something nobody can reason about anymore.
The way this breaks rarely looks dramatic. The invoice arrives, and no one in the building can explain what changed. The failure isn't a crash but a bill nobody can trace back to a decision.
The six load-bearing functions a production-grade gateway must perform
A gateway that only forwards requests to a provider and passes the response back is not doing the job. A gateway built for production has to carry six distinct responsibilities, and skipping any one of them pushes that work back into application code, recreating the problem.
The first is unified provider abstraction. Application code calls one API, and the gateway handles translation to Anthropic, OpenAI, Google, Bedrock, Azure, or a self-hosted model behind the scenes. Swapping providers becomes a configuration change, not a rewrite.
The second is model routing. Rules can be static, dynamic, or a mix of both, but routing logic lives in configuration, not in code. A routing rule can be shipped, watched, and rolled back without a deploy.
The third is retries and fallback. Doing this once, centrally, instead of inside every service that happens to call a model, is what the LLM Gateway Design Guide 2026 calls a real leverage point for cutting down reliability incidents.
Without this layer, every conversation about cost becomes a forensic investigation.
The sixth is rate limits and virtual keys: quotas scoped to a team or feature, virtual API keys so an experiment can't eat into the production budget, hard limits that stop a runaway agent loop before it runs all night.
The OpenAI-compatible API format has become the default contract across the industry. Nearly every gateway in 2026 speaks it, nearly every framework expects it, and the providers themselves have converged toward it. Confirming that compatibility comes first, because it determines how much work it takes to plug existing tooling into the gateway.
Virtual key architecture and keeping provider credentials out of application code
Moving provider API keys out of application code and into the gateway looks like a small change on paper.
The pattern works like this. Real provider API keys live only in the gateway. The gateway issues virtual keys to each service or team that needs access. Application code authenticates using the virtual key, never the real one. At request time, the gateway swaps in the actual provider credential behind the scenes. The application never sees it, never stores it, never risks leaking it.
Skipping this pattern causes consequences that recur in practice. There's no way to tie spend back to the team that generated it, because every request looks the same from the provider's side.
Virtual keys double as the enforcement point for rate limits and budget caps. A runaway agent loop or a misconfigured batch job hits the limit on its own virtual key, not the organization's entire provider account. The blast radius of a mistake shrinks to the team that made it.
Argy LLM Gateway states the underlying problem directly: when every application carries its own credentials, policies, and costs, IT loses sight of where data goes. Virtual key architecture is what closes that gap. Revoking access, rotating a credential, or bringing a new team online means making a configuration change in one place instead of a code deployment across a dozen services. That's what turns the gateway from a routing convenience into the organization's actual control plane.
Routing strategy tiers: from static fallback chains to latency-aware and quality-aware decisions
Routing is a set of policies that differ in what they optimize for, what they assume about equivalence between models, and what they risk when those assumptions turn out to be wrong.
The first tier is the static fallback chain: try Anthropic, then OpenAI, then Google, in that fixed order. A fallback from a frontier model to a much weaker one can quietly produce worse answers while reporting as a successful request.
The second tier is tiered fallback: try Sonnet on Anthropic first, fall back to Sonnet through Bedrock, then fall back again to a comparable GPT model on OpenAI. Quality stays consistent even as the provider underneath changes.
The third tier is latency-based or dynamic routing, using rolling performance statistics to pick a provider in real time. Routing for speed without doing that check first can quietly degrade output quality while every dashboard still shows green.
Routing has a security dimension most teams haven't thought through. Preference-based routers, built to pick the cheapest model that looks good enough, can make category-driven decisions with consequences nobody intended. Research on this question found that these routers can end up sending jailbreaking attempts to weaker, less safe models, raising the safety risk exactly where it should be lowest. Routing policy is a security surface as much as a performance and cost decision, and it needs to be evaluated as one.
Conditional routing based on request metadata, things like user tier, region, query complexity, or custom fields, solves problems a static fallback chain simply can't. Gateways like Inworld Router implement this through CEL expressions, letting a SaaS product route enterprise users to a frontier model and free-tier users to a cheaper one, with the application itself never needing to know which model actually handled a given request. The gateway has to make all of this a configuration change, not a code change, so that a routing rule can go out, get watched, and come back if it doesn't work, without anyone touching a deploy pipeline.
AI spend governance and the gateway attribution layer
Most enterprises already have a cost policy for AI spend. The gap is visibility: infrastructure to know whether that policy is actually being followed, or quietly ignored, before the bill arrives.
Cost ownership tends to be split across engineering, FinOps, finance, and IT, and that split means no single group holds complete accountability or complete data. An organization can have a strict policy on paper while most of its actual spend stays opaque until the reconciliation happens at the end of the month.
if nobody can say which team spent the AI budget, no FinOps platform is going to tell them. One virtual key per team, issued through the gateway, is the minimum setup that makes attribution possible.
The gateway is the only piece of the stack positioned to stop a cost overrun while it's happening, before it can be reported afterward. Hard budget caps enforced at the virtual key level catch a runaway agent loop before it turns into a five-figure line item on next month's invoice. Structured logging through the gateway turns raw request traces into data that can actually be queried: a cost team can check token consumption by department on demand, and finance can trace a cost spike back to the workflow that caused it within minutes, instead of waiting for the end of the month to find out.
Enforcing data security and compliance at the gateway without creating a sensitive-data store
The audit log meant to prove a company is handling data responsibly can become the exact thing that gets it in trouble, if it's built the wrong way. Writing plain-text prompts containing personal data or protected health information into an unencrypted log store doesn't demonstrate compliance. It creates a brand new regulatory violation sitting right next to the one the logging was supposed to catch. The audit record needs to capture the event, the data category detected, the action taken, which model handled it, which team made the request, the trace ID, never the raw prompt itself.
That distinction is the actual engineering problem here. A company must be able to prove that redaction happened, show who was involved, and keep that proof from becoming a copy of the thing that was redacted.
Real-time guardrails running at the gateway catch this before a request ever leaves the building, redacting or blocking sensitive fields before they reach any provider. The gateway is the one point in the entire stack where this interception can happen once and cover every service behind it. For teams that need to reconstruct what happened without keeping plaintext personal data around, cryptographic hashes of prompts paired with an off-box, access-controlled archive solve the problem: enough to verify and investigate, without a second copy of the sensitive data sitting in the open.
Argy LLM Gateway lays out the full picture of what a control plane does: every request crosses one control plane that resolves identity, applies role-based access control and policy, enforces the budget, runs the guardrails, routes by data residency, and writes an immutable audit record that can be exported to a SIEM, all before the request ever reaches a provider.
GDPR adds a geographic wrinkle. Data residency routing, directing requests to EU-hosted endpoints such as Frankfurt based on policy, is a common way gateways handle this. GDPR itself doesn't demand that data stay exclusively within the EU. Zero data retention, when a provider agrees not to keep copies of requests, is a policy a gateway enforces and verifies. It isn't something any provider turns on by default, and the gateway's audit trail is the only evidence that it actually fired on a given request.
The EU AI Act maps onto these same gateway capabilities almost directly. Its human oversight requirement calls for systems designed so people can actually monitor and step in during use, not just check a box at a few fixed points. Its data governance requirement lines up with residency routing and the PII guardrails already described.
Reliability in production: how fallback architecture prevents provider outages from becoming product outages
Every major LLM provider had at least one significant outage in 2025: OpenAI, Anthropic, and Google all went down at some point. OpenAI's ChatGPT and API went offline for thousands of users in December 2024, one of several disruptions that year. These are a normal part of running on top of these providers, and a team without fallback logic at the gateway level has exactly one option when a provider goes down: wait.
At the volume these systems run, even a small percentage of rescued requests adds up to a large number of users who get an answer.
Most teams collapse fallback into one category, but it actually splits into three, and each one needs its own provider list and its own routing logic. Context-window fallbacks cover a prompt that's too long for the model that received it, where the fix is routing to a model with a larger context window, not retrying the same one and expecting a different result.
The gateway itself becomes a reliability surface, a counterintuitive risk. If the gateway goes down, every feature that touches an LLM goes down with it, all at once. The mitigations are concrete. Use a managed gateway with real SLA guarantees instead of self-hosting on a single instance with no redundancy. None of this is new thinking. It's standard reliability engineering, applied to the layer where LLM traffic now lives.
Governance at scale: workspaces, RBAC, and SSO across the organization
Everything described so far, the virtual keys, the routing tiers, the budget caps, the audit logs, the fallback chains, has to hold up as the number of teams using the gateway grows from a handful to dozens. That's a governance problem as much as a technical one. Workspaces give each team its own isolated environment inside the gateway: its own virtual keys, its own budget, its own routing rules, without one team's configuration leaking into another's.
Role-based access control decides who can change what inside a workspace. An engineer running experiments shouldn't have the same permissions as the person who sets the budget cap for the whole department. Single sign-on ties the gateway into the same identity system the rest of the organization already uses, so access follows a person's actual role, and leaves the moment that role changes, instead of lingering as a forgotten API key somewhere in a team's codebase. AWS Bedrock's own application inference profiles, a provider-native feature, let a team attribute Bedrock costs by application, team, or workload, confirming that this kind of attribution is a direction the providers themselves are building toward, one workspace, one role, one login at a time.