Unified Routing Across LLM Providers in Production
Centralized gateways eliminate scattered API keys and duplicated retry logic across services.
A single team with a single API key can wire a model straight into application code and never notice a problem. That's how almost every AI project starts: one provider, one key, one codebase, and it works fine. The trouble appears once a second team joins in, or a second service, or a second provider. By the time that second LLM-touching service exists, retry logic, auth handling, and provider-specific SDK calls are already being copied from one codebase into another.
Two signals make the problem visible. One is technical: the same exponential-backoff retry code turns up, pasted nearly verbatim, in three or more services. The other is financial: someone in finance asks how much the company spent on LLM calls last month, and getting an answer takes a forensic investigation rather than a query. A production case out of Azure shows how this plays out. Each product team held its own provider keys. Some routed calls through small in-house proxy services they'd built themselves. Most didn't. When finance asked which teams were spending what, the answer came back as a spreadsheet of guesses. When security asked which data had reached which model, the answer was worse than a guess.
Timing is the root issue. You can't see token spend until the invoice arrives, and you can't see data flows until an audit forces someone to trace them. Both are visible only after the fact, in the invoice or in the audit, not in the moment that governance would matter. Once a second LLM-touching service enters the picture, scattered keys and duplicated retry logic stop being a minor inconvenience and start costing engineering time every time a provider changes its API or a team needs to add a new model. Tools like Concentrate AI centralize provider selection and authentication at the infrastructure layer, so individual applications don't each need their own SDK wrapper or their own key-rotation routine.
What an LLM gateway is
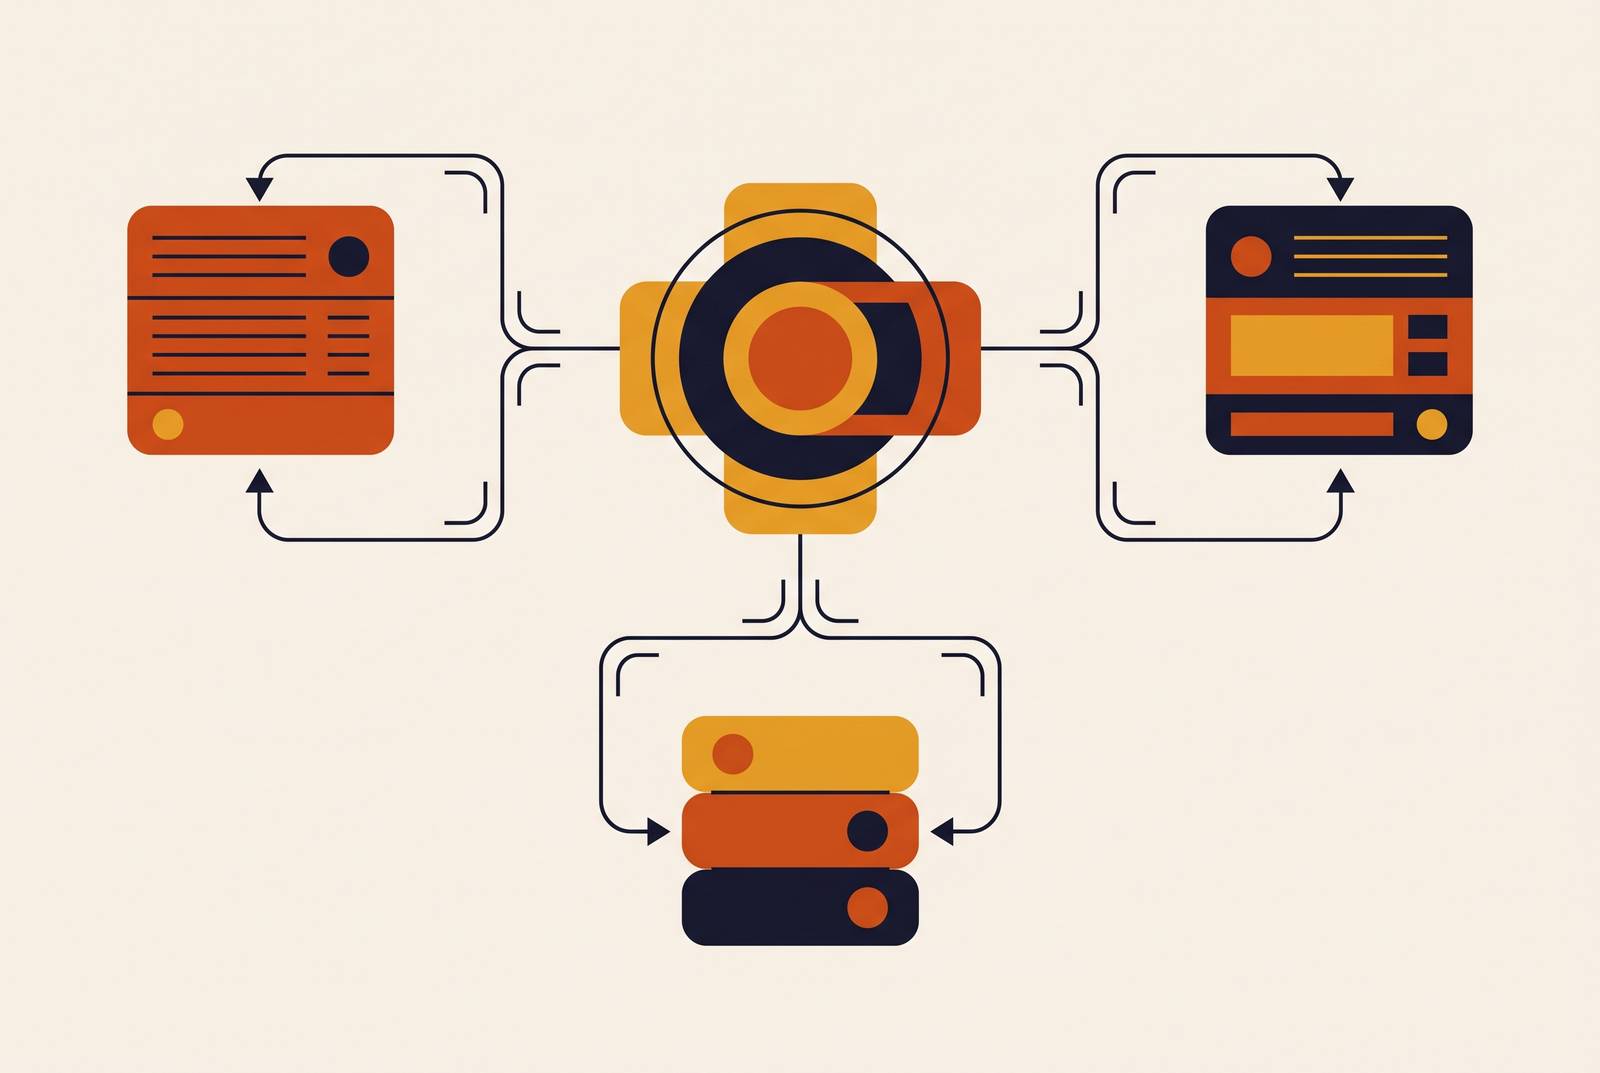
An LLM gateway is a reverse proxy sitting in front of model APIs. Applications send every request to one endpoint, and the gateway handles provider selection, authentication, policy enforcement, and logging behind the scenes. That means a team can swap one model provider for another without touching a line of application code.
The topology is straightforward: application talks to gateway, gateway talks to the AI provider or a self-hosted model. So the gateway, not application code, takes over the direct, per-provider SDK calls. A production implementation built on Azure traces the full path a request takes: authenticate the caller, resolve which tenant is calling, check policy, route the request to a model, meter the tokens used, enforce any budget limits, and log the whole transaction. Every one of those steps runs on each individual call. None of it gets reconstructed after the fact from logs or invoices.
Picture a company running four different workloads: one model handling customer support, another handling coding assistants, a self-hosted model for anything sensitive, and a cheaper provider for high-volume classification work. If there's no gateway, every application that touches any of those four providers has to learn each one's API, auth scheme, and quirks on its own. With a gateway in place, every application talks to one standardized internal endpoint, and the gateway worries about which provider actually handles the request. An LLM gateway sits between applications and model providers as a reverse proxy that standardizes that entire request path, authenticating the caller, resolving policy, routing to the model, metering tokens, enforcing budgets, and logging everything in one auditable flow. Concentrate AI runs this pattern as a fully managed service, so teams don't have to host or maintain the gateway infrastructure themselves.
One more shift matters here. Agentic workflows, where a model calls tools, retrieves data, and chains multiple steps together, are a fast-growing but still early pattern in enterprise AI deployment as of 2026. But if a RAG pipeline, an agent orchestration layer, and tool calls all need to pass through the same control plane, a gateway built only to route single model calls may not hold up. That pressure shapes everything the rest of this piece covers.
How intelligent routing across providers works inside the gateway
Routing inside a gateway is a set of patterns, and which one a team should use depends on whether the binding constraint is cost, latency, output quality, or keeping something running when a provider has a bad day.
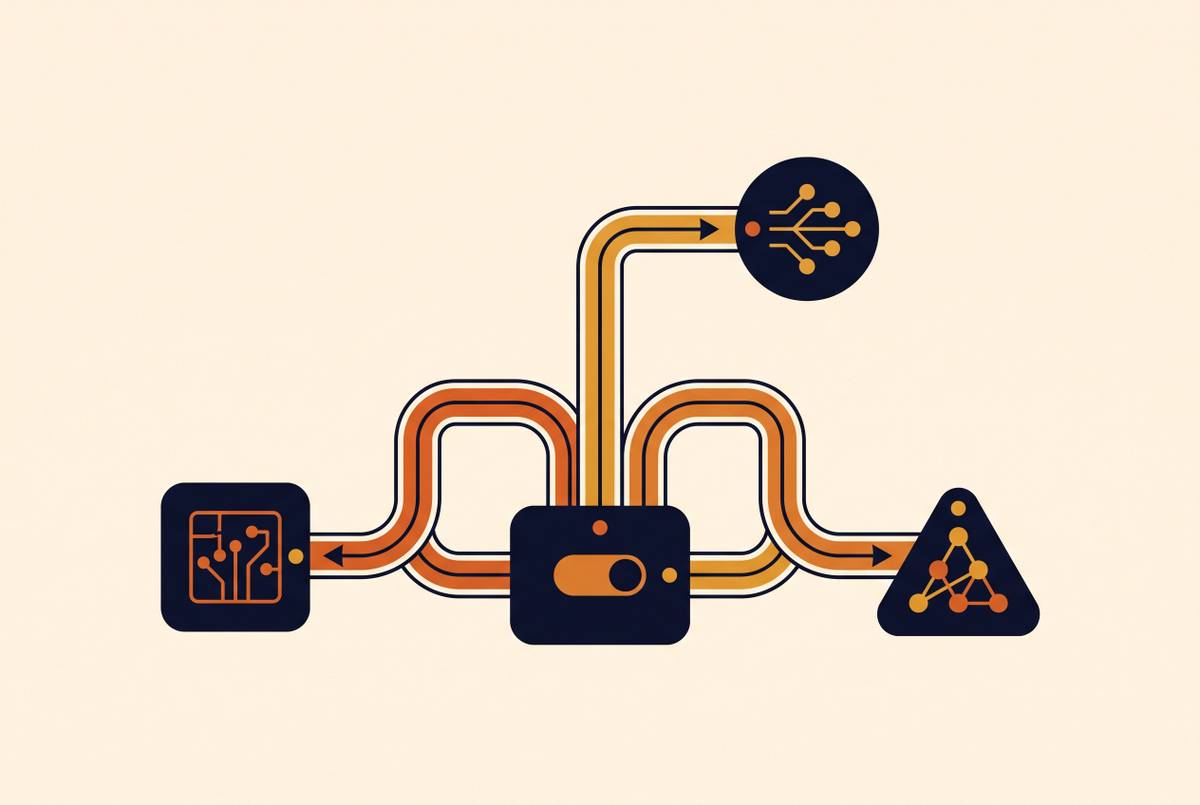
Four patterns appear in production systems today. Static rules by task type send coding requests to one model, and they send summarization requests to another. It's simple to set up and easy to reason about, but it breaks down the moment the mix of incoming tasks shifts and the rules don't shift with it. Task-based classification puts a lightweight classifier at the gateway itself, and it looks at each incoming request to decide which model fits best. That adds a small amount of latency but allows for much finer-grained routing than a fixed rule table. Latency-weighted routing, known as PeakEWMA, adjusts in real time by favoring whichever provider endpoint has shown the lowest recent latency, a pattern Requesty's routing core implements. Cascade or escalation routing tries a cheaper model first and only escalates to a more capable, more expensive model when the cheaper one's output doesn't clear a quality bar, which puts a direct ceiling on spend without giving up quality on the hard cases.
The reason routing is worth this much engineering attention comes down to the spread in cost and quality between model tiers. A 2026 benchmark run across real coding tasks found that budget-tier models run at a fraction of the per-task cost of frontier models, and their pass rates differ meaningfully from the frontier tier but don't disqualify the cheaper models outright. That gap between tiers is large enough that a routing decision made at the gateway translates directly into a line item on the monthly bill. The academic case for this approach predates most commercial gateways. RouteLLM, presented as a poster at ICLR 2025 by researchers from UC Berkeley and Anyscale, showed that routing only a small share of queries to an expensive model while sending the rest to a cheaper one cut costs substantially on MT-Bench while keeping most of GPT-4's measured quality.
Semantic caching deserves more attention than it usually gets. If two prompts ask the same question in different words, a semantic cache recognizes the overlap and returns the cached answer instead of paying for a new model call. Teams running dual-layer semantic caching in production report meaningful hit rates, and they cut both spend and latency without any drop in output quality. The gap between a cache that only matches identical text and one that matches meaning can be substantial on real workloads.
None of this works, though, without an honest caveat. Benchmarks like MT-Bench measure whether a router picks the model that performs best on that specific benchmark. But they don't tell you whether that routing decision matches what real users need under the cost and latency constraints an actual production system faces. A routing configuration that wins on a benchmark can still perform worse on live traffic. Teams need production evaluations run on their own traffic before they can trust a routing table to run unattended. Routing patterns, whether static rules, latency-weighted selection, or cost-first escalation, all depend on real-time visibility into how providers are performing and what tokens actually cost. Without that visibility, a routing decision is a guess dressed up as a policy.
Why observability and spend attribution belong in the gateway
A routing system is only as trustworthy as the ability to check that it's doing what it's supposed to do. That means spend attribution and observability can't live in a separate analytics tool bolted on after deployment. They have to sit in the same layer where routing decisions get made.
The scale of the problem is growing fast. Among businesses that track their own AI spend, token usage grew 1,001% between January 2025 and April 2026, even as the price per token kept falling. That kind of growth curve means any team planning its AI budget a year out should expect usage, not cost per token, to be the variable that moves.
Cost per token is also the wrong number to manage against. Optimizing for a lower cost per token rewards using the model less often, which runs against the entire point of adopting it in the first place. The metrics that actually matter are cost per completed task, cost per workflow, or cost per unit of resolved work, and you measure them against what that same task cost before AI was involved.
Governance built in after a system is already running costs far more to retrofit than governance designed in from day one, because by the time a finance or security team notices a problem, the spend or the exposure has already happened. That's why the metering pipeline inside a gateway needs to behave like a stream processor: it produces per-team and per-model numbers within seconds of each call, instead of a batch job that reconstructs spend weeks later from an invoice. Real-time visibility means tracking cost per query, latency distributions, token usage, and error rates, broken out by model, team, and individual request, with anomaly detection sensitive enough to catch a runaway retry loop before it burns through a month's budget in an afternoon.
Concentrate AI's unified API connects teams to a wide range of providers while surfacing spend attribution by team, project, key, model, and provider in real time. The architecture behind that is the same stream-metering design described above, and it runs without adding a per-token platform fee on top of whatever the underlying provider already charges.
How the gateway enforces data security and compliance
Sensitive data rarely reaches a model because someone typed it in on purpose. It reaches the model because a retrieval chain, an agent's tool call, or a summarization pipeline pulls it in automatically, without anyone reviewing the context before it goes out. So enforcement has to happen at the gateway, before the model ever sees that context.
The failure mode is structural. A retrieval chain pulls a record out of a CRM. An agent tool returns an entire customer table instead of the one field it needed. A support assistant summarizing a call transcript echoes back a phone number that belongs to someone other than the person asking the question. Once that output has already gone out to a user, an audit log can only show that exposure happened, not prevent it.
The design that actually addresses this works in layers: detect personally identifiable information before it ever reaches the model's context window, redact or block it after a response comes back if anything slipped through, and write an audit record that proves exactly which route, which evaluator, and which policy made each decision. Concentrate AI's position is that sensitive customer data, PII and PHI included, should never reach a model provider unguarded, and that any redaction applied along the way should be something a team can review and enforce, not just assume is happening.
PII handling generally takes one of two technical forms. Masking is irreversible: the original value is gone, the result is anonymized, and it falls outside the scope of GDPR entirely. Tokenizing is reversible: the value is pseudonymized rather than destroyed. It remains subject to regulation, and the choice between the two comes down to whether a downstream system needs to reconstruct the original value later.
A zero data retention, or ZDR, architecture rests on three technical pillars: dynamic masking of PII before anything is transmitted to a model, a gateway that holds no state and never writes request content to disk, and audit logging that captures metadata about each event without storing the content itself. The regulatory picture around this is specific. HIPAA requires appropriate safeguards for any system handling protected health information, including business associate agreements, access controls, and audit logging, but HIPAA itself does not require zero data retention. GDPR requires data protection by design as a baseline principle. SOC 2's CC6.1 control requires logical access controls, which a ZDR architecture satisfies at the model layer.
Fallback routing for production AI reliability
No model provider has solved uptime completely, and a gateway with fallback routing built in is the one architectural fix that doesn't require someone to rewrite application code every time a provider has an outage.
The clearest diagnostic signals are copy-pasted exponential-backoff code in three or more services, or a finance question about monthly LLM spend that requires a forensic investigation to answer. A static fallback chain, something like "try Anthropic, then fall back to OpenAI, then fall back to Google," is simple to set up but ignores differences in model quality between those providers, so a fallback can quietly produce a worse answer than the primary call would have. A tiered fallback chain matches capability tier to capability tier instead: try Sonnet on Anthropic directly, fall back to Sonnet via Bedrock, then a quality-equivalent alternative on OpenAI, choosing one judged quality-equivalent at each step. That approach keeps output quality consistent across the whole chain, not just the lights on. Latency-based routing picks whichever available provider is fastest for a given request, based on rolling latency statistics. That pattern only holds up safely if quality equivalence across providers has already been checked with real evaluations. Skip that step, and quality degrades without anyone noticing because the system optimizes purely for speed.
Treating every failure the same way is itself a mistake. A 429 response means the provider is up and running but the account has hit its quota. Retrying the same provider immediately just wastes time waiting on a limit that isn't going to lift itself. A 5xx response is different: it usually signals a transient problem, and the provider may well recover within seconds, so a short retry against the same provider is worth attempting before failing over to a different one entirely. Building that distinction into the gateway's retry logic, rather than hard-coding a single retry strategy into every application that calls a model, is what keeps a brief provider hiccup from turning into a visible outage for the people actually using the product.
Sources
- Comparing Open-Source LLM Gateways in 2026 to Run Enterprise AI at Scale - DEV Community
- Top 5 LLM Gateways for Production in 2026 (A Deep, Practical Comparison) - DEV Community
- LLM Gateway Comparison 2026: Enterprise Buyer's Guide
- An Enterprise LLM Gateway: Centralized Access, Metered Usage, and Guardrails for Production AI on Azure - DEV Community