Managed LLM Gateway Providers Compared for Teams Skipping Proxy Ops
Managed gateways let teams skip infrastructure work while keeping routing control.
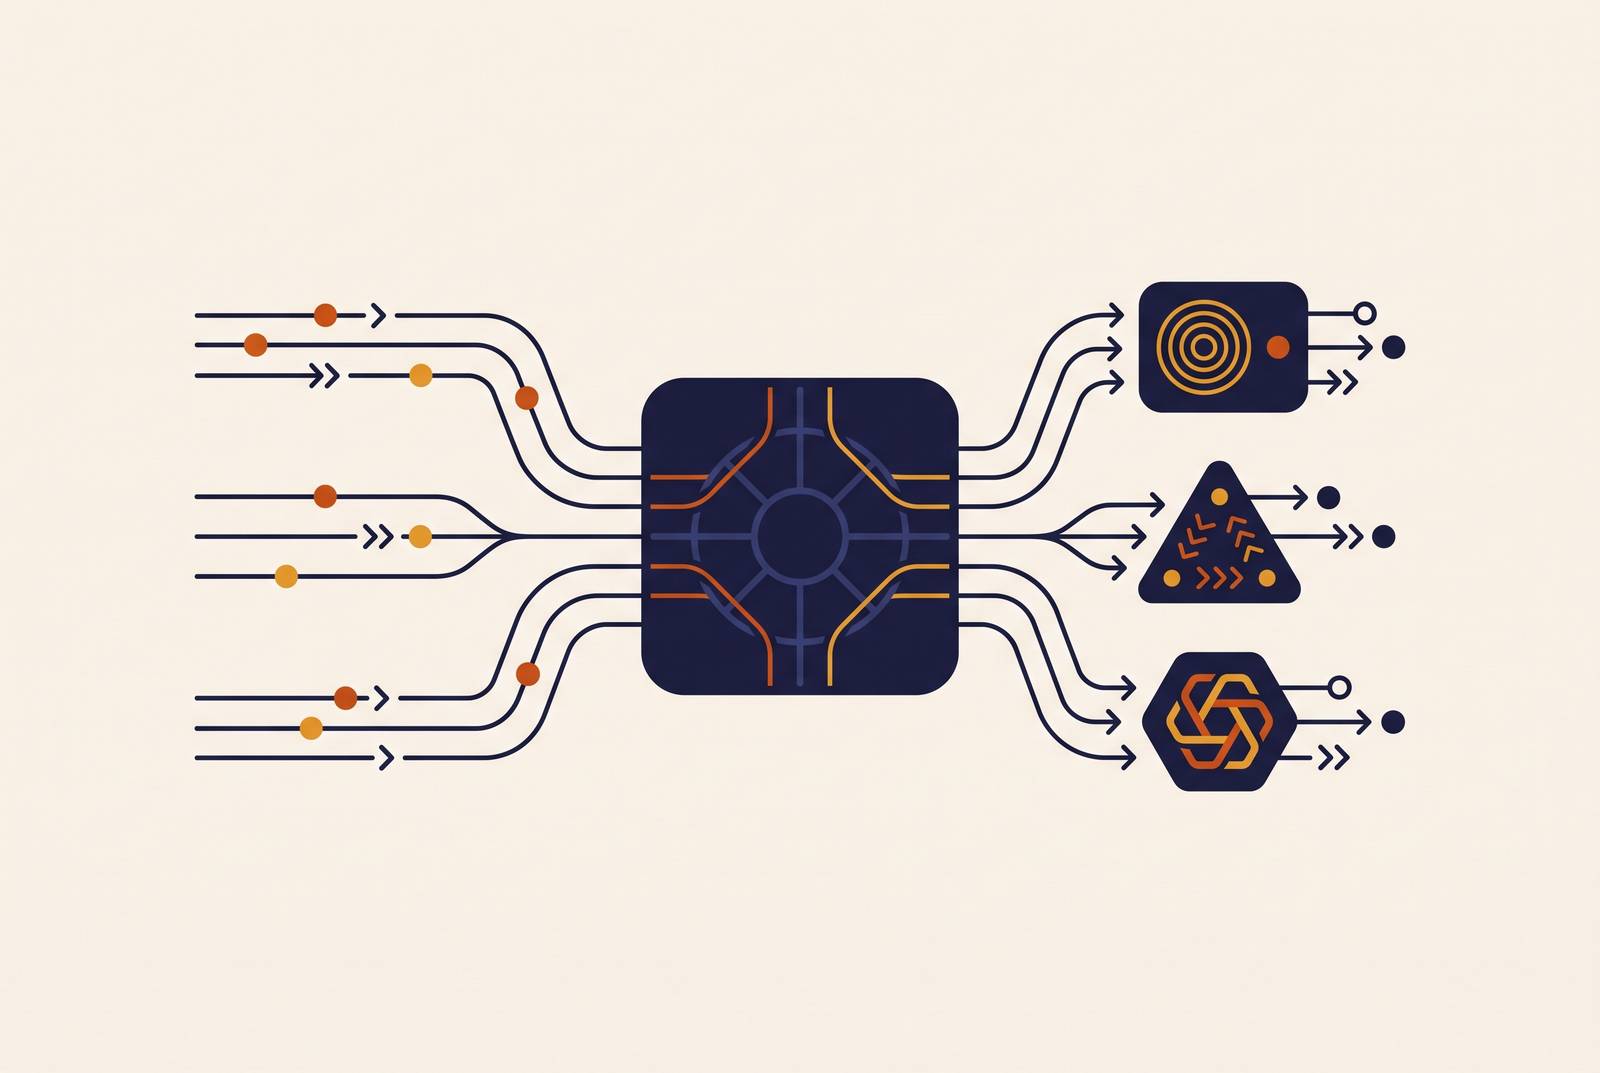
Most teams don't choose to build a self-hosted LLM gateway. They back into one, one integration at a time, until a production system exists that nobody budgeted for. The real comparison for teams trying to skip proxy ops is which managed providers absorb the infrastructure burden while preserving routing control, spend visibility, and security, keeping engineering time on the product.
The Cost of the Self-Hosted Gateway Path
The failure mode looks the same almost everywhere it happens. Then a second model gets added for a different use case. A compliance question, usually from legal or a customer security questionnaire, asks where prompts get logged and who can see them. A second model, a second team, a second provider, or a second compliance question each turn a self-hosted gateway into a production system that someone has to own, patch, and staff for.
Each threshold forces a different kind of work that has nothing to do with the product the team was actually hired to build. A second provider means failover chains. A compliance question means central credential management, audit logs, and a redaction policy that can survive a review. None of that is incidental work. It's the full job of a gateway, arriving in pieces, usually without anyone deciding on purpose to build one.
The typical sequence makes it worse. Then, under incident pressure, usually after an outage or a surprise invoice, a gateway gets retrofitted in a rush. That is the worst possible moment to get an architecture decision right: during an incident, with stakeholders watching, and with whatever shortcuts are fastest to ship.
Self-hosting also puts security ownership squarely on the team that built it, and that ownership comes with real exposure. In March 2026, a supply-chain incident hit the LiteLLM ecosystem: two PyPI releases were backdoored after a credential theft, and the malicious packages were quarantined within about three hours. That's operational readiness many teams haven't staffed for, because they didn't think of themselves as running security infrastructure. They thought they were running a proxy.
The operational surface keeps expanding as the gateway matures: a Postgres instance to run, containers to patch, dependencies to update, incidents to own when any of it breaks. Teams that say self-hosting gives them control over everything are right about the control. But control over infrastructure only pays off if there's staff and process behind it to exercise it safely. For most teams trying to ship, that control is a liability wearing the costume of autonomy.
What a managed gateway absorbs (and what it still can't do for you)
A managed gateway earns its keep by taking over the entire operational surface described above: provider key vaulting, failover logic, spend enforcement, PII redaction, and credential lifecycle management. What it does not take over, and shouldn't, is routing policy, budget decisions, and the judgment needed to interpret what the observability data is actually telling the team. Those stay with the people who understand the product.
Concretely, the managed layer hosts and patches the proxy so nobody on the team has to. It holds provider API keys in a central vault, so individual applications never touch raw credentials. And it routes traffic to healthy providers automatically when one starts degrading.
What stays with the team is the policy layer: deciding which model serves which workload, setting the actual budget thresholds, reviewing the audit trail for anything unusual, and checking that quality holds up when a fallback provider fires instead of the primary one. A managed gateway doesn't make those decisions. It makes sure the team has the information and the levers to make them well.
The distinction from a conventional API gateway matters here. An LLM gateway carries concerns that a standard API gateway never had to deal with: token-level cost metering, semantic caching of completions, PII redaction across both prompts and responses, and fallback logic that accounts for model quality. A health check tells you a provider responded. It says nothing about whether the response was any good.
The credential vault design carries more weight than it first appears. When provider keys live only inside the gateway, and applications hold short-lived scoped tokens instead, a leaked application token gets rate-limited, budget-capped, and revoked instantly, without anyone having to rotate the underlying provider key or touch any other service. This is the architecture that neutralizes the LLMjacking attack class: the entire category of attack where a stolen key gets used to run up usage on someone else's account disappears at the design level because the design catches it before the fact.
The job has also gotten bigger in 2026. With agentic workloads now running in production, a single user request can trigger multiple model calls across multiple providers in sequence. Absorbing proxy ops used to mean governing one completion at a time. Now it means governing the entire chain, start to finish, which is a materially harder problem than it was two years ago.
Concentrate AI: managed gateway built for teams that govern AI at scale
Concentrate AI absorbs the full infrastructure burden, provider key management, routing, spend enforcement, and security controls, through a single unified API that connects to more than 130 LLM models.
Routing on Concentrate AI is built to stay visible. The position behind that design is straightforward: automatically swapping models without the team knowing it happened isn't a feature worth having. Routing decisions stay transparent and under the team's control, with a chain the team sets itself, so if one provider degrades or rate-limits a request, the system follows the next provider in that chain rather than making a silent substitution somewhere upstream.
Spend visibility is handled before the invoice arrives, not after. Cost tracking is real-time and granular, broken down by team, project, key, model, and provider, and budget enforcement happens at the request path itself. That means overspend gets structurally prevented rather than reported after the money is already gone, which is the difference between a dashboard and an actual control.
Security isn't held back for an enterprise tier that only larger customers can reach. PII, PCI, and PHI redaction come with a redaction policy that's reviewable and enforceable, alongside RBAC and audit logs, available to teams of any size from day one. For a two-person team handling customer data as carefully as a two-thousand-person one, that's the right default.
There's no per-token platform markup built into the pricing. Cost scales with what the underlying provider actually charges, not a percentage skimmed off every call on top of it. For teams tracking usage against margin, that's a meaningfully different cost structure than a markup model, where the platform's revenue grows in lockstep with the team's bill regardless of whether the platform added any value to that particular call.
Team workspaces, SSO, and governance controls are built to scale with the organization. And provider outages are handled at the infrastructure layer itself. Engineering teams don't write failover logic by hand, because the API they're calling already handles fallback and reliability.
Concentrate AI fits engineering teams and engineering leaders from seed stage through mid-market and enterprise, specifically where AI usage is growing faster than internal governance can keep pace with it.
OpenRouter: widest model catalog for teams where variety is the binding constraint
OpenRouter solves a narrower problem extremely well: reaching a wide catalog of models fast, without building a separate integration for each provider. For a team that needs to test ten models across three providers by Friday, that's exactly the right tool.
Provider-level fallback and load balancing come built in. If the provider currently serving a given model starts erroring or slowing down, requests shift automatically to another provider serving that same model, without the team having to write that logic themselves. Routing decisions factor in price, throughput, latency, availability, and data policy, with sensible defaults that don't require much configuration to get useful behavior out of the box.
The honest limitation is on the governance side. Per-team spend attribution, RBAC, audit logs, and compliance controls mark a scope boundary where OpenRouter stops leading and stops being the default pick for an organization.
Cloudflare AI Gateway: edge-native routing for teams already running on Cloudflare
Cloudflare AI Gateway's strongest case is for teams that already run their infrastructure on Cloudflare and want AI traffic treated as just another first-class workload inside that same system, governed by the same tooling as everything else. For those teams, the fit is close to seamless. For teams coming in cold, it's a harder sell.
The pricing is hard to argue with at the entry level: exact-match caching, analytics, and rate limiting are free on every plan. There's no upfront cost to start routing traffic through it. A unified REST API, added in May 2026, offers separate OpenAI-compatible and Anthropic-compatible endpoints, which cuts down integration friction for teams already built around either SDK shape. Workers Free costs nothing, and Workers Paid starts at $5 a month, a modest number for teams weighing it against a managed subscription elsewhere.
Built-in DLP profiles can scan both inbound prompts and outgoing completions for credit card numbers, social security numbers, insurance and tax identifiers, and custom enterprise regex patterns on top of that. It's a genuinely useful set of guardrails for teams handling sensitive data, but guardrails and DLP are still treated as features that are generally available as of 2026 evaluations rather than long-proven, battle-tested systems, and teams whose compliance requirements are already locked in today should weigh that maturity gap carefully before depending on it.
The bigger trade-off is architectural. The fit is strong when a team already runs Workers, WAF, and CDN on Cloudflare and wants one more piece of its stack under that same roof. As a standalone gateway choice, disconnected from the rest of that ecosystem, it's a much harder case to make.
Cloudflare AI Gateway fits teams already operating on Cloudflare infrastructure that want AI traffic governed by the same tooling running the rest of their stack, and that can live with compliance controls still maturing for now.
LiteLLM: the self-hosted benchmark
LiteLLM is the most capable self-hosted gateway available today, and that capability is precisely what makes it the clearest argument for why managed alternatives exist. It's a strong option that reveals how much operational weight a team takes on by choosing it, rather than a weak option that managed providers beat on features.
It ships as an open-source proxy and a Python SDK that wraps more than 100 LLM providers behind a single OpenAI-compatible API.
An enterprise commercial license adds SSO, SAML, audit logs, custom SLAs, and dedicated support, though pricing for that tier isn't published as a fixed list price and requires a direct sales conversation.
The operational cost that comes with all of this is documented. The team running LiteLLM runs the Postgres instance behind it, patches the container, and owns whatever incident follows when a dependency breaks, security incidents included. Eight GitHub Security Advisories were published against the project in 2026, three rated Critical and five rated High. It's a statement about where responsibility sits: with the team that deployed it, not a vendor on the other end of a support contract.
The decision condition for choosing LiteLLM over a managed alternative comes down to two things that both need to be true at once. Engineering time has to be genuinely cheaper than a managed subscription, and data residency requirements have to rule out sending traffic through a third-party SaaS provider. Either condition alone doesn't settle it. Both together do.
The four dimensions that separate managed providers in practice
Once a team has ruled self-hosting in or out, the real differences between managed providers aren't visible on a feature comparison chart. They show up across four operational dimensions: how transparent the routing is, when spend gets enforced, how deep the security controls go, and what happens to traffic when the control plane itself has a bad day.
Routing transparency is the first test. A gateway that swaps models automatically without telling the team is not the same thing as one that routes explicitly and lets the team control that routing. The right question to ask any provider: can the team see, at the level of an individual request, which model and provider handled it, and can they enforce that a specific workload always stays on a specific model?
Spend enforcement timing is the second test, and it's where a lot of gateways quietly fail. The budget check has to happen before the provider call goes out, because end-of-month invoice reconciliation is an autopsy, not spend management. This matters even more as token spend grows not just from higher volume but from workloads shifting toward heavier, more expensive models, which makes enforcement before the call goes out a lot more valuable than enforcement after.
Security depth is the third test. Zero data retention matters for regulated industries specifically, and it needs to be enforced at the routing layer itself, not just written down as a policy somewhere. None of this is an enterprise extra bolted onto a premium tier. Any team handling customer data needs these controls from the first day it starts sending traffic.
Control plane resilience is the fourth test, and it's the one teams tend to overlook until it costs them. A gateway that fails open, letting traffic through when it can't make a routing decision, behaves very differently under stress than one that fails closed. Either answer can be defensible. Not having an answer at all is not.