Vertex AI Rate Limits and Quota Management in Production
Understanding which quota regime you're using prevents silent failures in production.
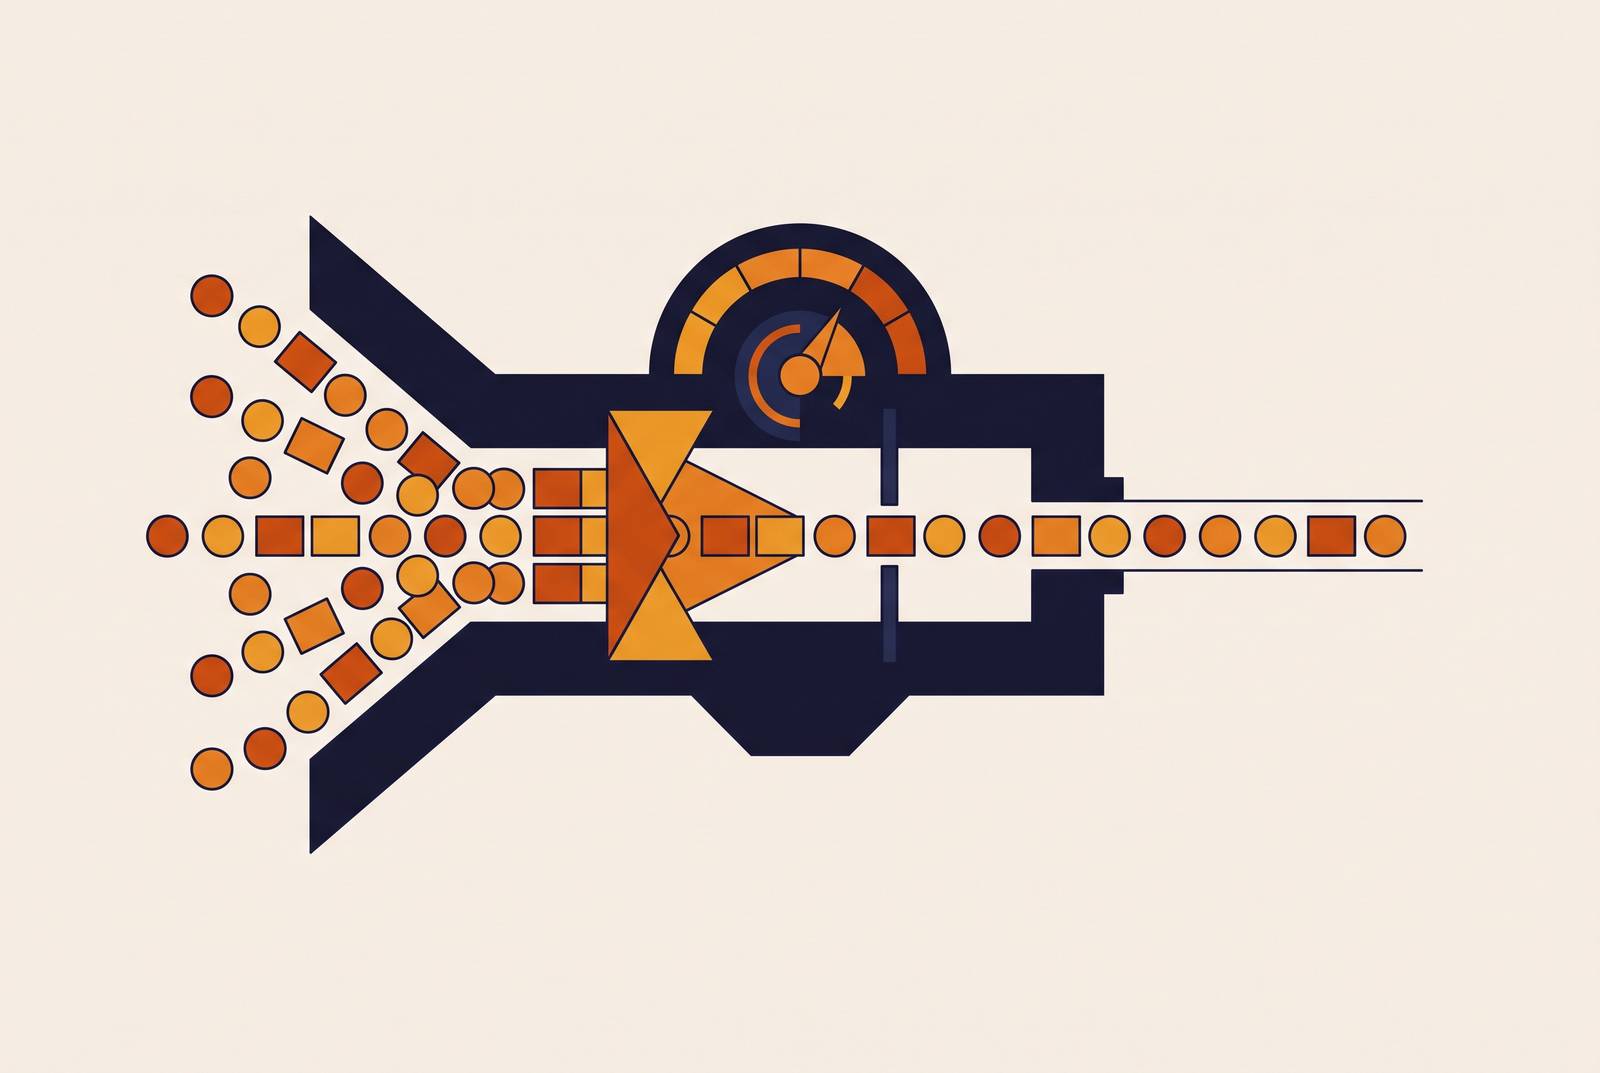
Vertex AI's coexisting quota regimes (standard per-project quotas, Dynamic Shared Quota, and Provisioned Throughput) each create distinct failure modes in production. Standard per-project quotas, Dynamic Shared Quota, and Provisioned Throughput look like variations on a theme, but they behave nothing alike under pressure, and mixing up which one applies to a given model is where most production incidents start.
The three quota regimes on Vertex AI and why conflating them causes production failures
A team hits its first 429 error during a spike and assumes the fix is simple, request a quota increase, but that assumption only holds for one of the three regimes. That move only works for one of the three regimes, and figuring out which one applies has to happen before anything else.
Regime one is the standard per-project, per-region quota. It covers models earlier than Gemini 2.0 along with some non-Gemini models, and it works the way most engineers expect quotas to work: fixed limits, visible in the console, with a real path to request more. Regime two is Dynamic Shared Quota, or DSQ, which governs newer Gemini models running on Standard PayGo. DSQ splits available capacity across every customer hitting that model and region at the same time, so there's no fixed number to increase, because there's no fixed number, period. Capacity gets competed for, not reserved. Regime three is Provisioned Throughput: dedicated compute bought ahead of time, measured in generative AI scale units (GSUs), with quota enforced at each request during a defined window.
The conflation risk appears in two directions. Teams running on DSQ file quota increase tickets that go nowhere, because there's no lever on the other end to pull. Teams running Provisioned Throughput often don't notice that their overflow traffic has quietly started billing as pay-as-you-go, which appears nowhere until the invoice does. The fastest diagnostic question any team can ask is simple: which model generation are you actually running, because that answer determines which regime you're in. One more scope detail matters here and comes back later: quotas apply at the Google Cloud project level, so usage in one project has zero effect on quota in another.
How standard per-project quotas work and where they break under load
Under the standard system, quota gets measured across a few dimensions: tokens per minute (TPM), requests per minute (RPM), and separate modality-specific caps for preview and multimodal models. The main lever for getting more headroom isn't a bigger number on one region, it's spreading across regions. A single project can hold up to 30,000 online inference requests per minute in one supported region, and another 30,000 in a second supported region, because quota in each region runs independently of the others How to Manage Quotas and Rate Limits for Gemini API Requests in Vertex AI.
That independence is the whole game. A team funneling every request through one region hits the wall at 30,000 RPM and stays there How to Manage Quotas and Rate Limits for Gemini API Requests in Vertex AI.
Evaluation traffic is a subtler drain worth watching. If a model like gemini-2.0-flash gets used both for production inference and for model-based evaluation, both draw from the same per-project quota pool. Teams running evals alongside live traffic are, in effect, competing with their own production workload for the same slice of capacity. Embedding models carry their own overlooked sub-limits: up to 250 input texts per request, up to 20,000 tokens per request, and only the first 8,192 tokens of any single input text actually get used for the embedding blevinscm.github.io P1 launch: add account-level AI spend ceilings beyond per-minute rate limits · Issue #1041 · vertex-studyAI/vertexED.ai. Teams that batch embedding calls without checking these numbers can waste tokens or trip request-level limits well before they ever approach their RPM ceiling.
Checking current limits is straightforward. The GCP console has a path through IAM & Admin, then Quotas & System Limits, filtered by "Vertex AI API" and searched for "gemini". The same data is available programmatically through the gcloud CLI or the Cloud Monitoring API, using the serviceruntime.googleapis.com/quota/rate/net_usage metric. Requesting an increase works through the same console quota page, for this regime specifically. That path simply doesn't exist for DSQ models, which is the mistake teams keep making.
Dynamic Shared Quota (what "no fixed quota" means in a traffic spike)
DSQ removes the request-an-increase workflow entirely. Capacity gets distributed dynamically across every customer hitting a given model and region, and there's no way to reserve a slice of it ahead of time. For Standard PayGo on current Gemini models, throughput tiers get set by organization-level traffic sent to the global endpoint rather than fixed per-region numbers, though the system ceiling is still 30,000 RPM per model per region How to Manage Quotas and Rate Limits for Gemini API Requests in Vertex AI.
This produces a specific kind of failure. During a global demand spike for a popular model, DSQ capacity compresses for everyone simultaneously. That's a hard thing to plan around, because it means the same traffic pattern that ran fine yesterday can get throttled today for reasons that have nothing to do with anything the team changed.
There's a second wrinkle in how Standard PayGo scales throughput: it tracks rolling 30-day spend Gemini Enterprise Agent Platform. A brand-new project with little billing history gets less starting headroom than an established one, even if the parent organization has plenty of spend elsewhere Gemini Enterprise Agent Platform. So launching a new project into production means inheriting a lower capacity floor by default, regardless of how much history sits one level up in the org.
Gemini's newer reasoning models add a cost dimension that's easy to miss. Gemini 3.x models bill internal reasoning tokens as output, at full rate, so a short visible answer can carry a token cost far larger than its length suggests. That accelerates TPM consumption in ways that don't track with what a dashboard showing response length would suggest.
Gemini 2.5 Flash-Lite shuts down October 16, 2026 on the Gemini Developer API, or October 20, 2026 on the Agent Platform Gemini API, according to Firebase's documentation, and new projects can no longer start on Gemini 2.5 models at all P1 launch: add account-level AI spend ceilings beyond per-minute rate limits · Issue #1041 · vertex-studyAI/vertexED.ai. Teams still running 2.5 in production need a migration plan, not just for continuity's sake but because the cost floor moves with the shift to newer models P1 launch: add account-level AI spend ceilings beyond per-minute rate limits · Issue #1041 · vertex-studyAI/vertexED.ai.
One more quota dimension applies specifically to Firebase AI Logic users: a default of 100 RPM per user, applied at the project level across all apps and IPs Gemini Enterprise Agent Platform. It's adjustable, but it sits on top of whatever the underlying Gemini API is already enforcing, which means it's a second ceiling, not a replacement for the first one How to Manage Quotas and Rate Limits for Gemini API Requests in Vertex AI. During a global demand spike for a popular model, DSQ capacity compresses for everyone simultaneously, and your 429s are not a function of your own usage history: they're a function of the platform's aggregate load.
Provisioned Throughput (the capacity guarantee that comes with sharp edges)
Provisioned Throughput exists for one reason: predictability. Teams buy dedicated compute ahead of time, measured in GSUs, and the quota ceiling becomes a direct function of how many GSUs got purchased and how much throughput each one delivers. For production workloads that need stable latency and high availability, that predictability is the whole point.
Enforcement isn't locked to a rigid window either. Vertex AI uses a flexible enforcement window for Gemini models that adjusts based on model type and number of GSUs provisioned, designed to absorb traffic spikes without punishing legitimate burst patterns.
The sharp edge is spillover. If a request exceeds the remaining Provisioned Throughput quota, it doesn't just fail, it gets processed anyway, silently, as an on-demand request billed at pay-as-you-go rates. That appears as spillover in the monitoring dashboard, but only if someone's actually watching that dashboard. Teams that aren't find out about it on the next invoice instead.
For teams where cost control affects them more than uptime does, restricting the deployment to Provisioned Throughput only fixes the configuration. In that mode, a request that exceeds the order amount returns a 429 instead of quietly spilling over into billable overflow. That has to be set deliberately, though. It isn't the default behavior.
Provisioned Throughput does not cover quotas for other tools like Grounding, and additional quota for those tools must be requested separately depending on workload size. And a PT order for a given model doesn't extend to models called through other Gemini Enterprise Agent Platform products, things like Vertex AI Agents or Agent Search. Teams building agentic products on top of Vertex AI can't assume their PT purchase covers agent-originated traffic, because it doesn't.
The decision comes down to variability. Provisioned Throughput makes sense when predictable latency and guaranteed availability are worth more than the upfront commitment. DSQ or standard quotas stay the more rational choice for workloads where volume is uncertain or highly variable.
Regional vs. global endpoints (the routing decision with the biggest reliability leverage)
Regional endpoints keep processing inside one geography and support the full feature set: tuning, batch prediction, context caching, data residency compliance. That makes regional the right default whenever any of those requirements actually exist.
The global endpoint works differently. It routes each request to wherever free capacity happens to be across regions, which raises availability and cuts down on 429 errors under DSQ, since it's drawing from a much wider capacity pool. The tradeoff is no data residency guarantee, and no support for tuning, batch prediction, or context caching.
Regional stacking is the complementary move here. Two separate regional endpoints in two separate supported regions give two independent quota pools, so a team routing across both regions has effectively doubled its per-minute ceiling under the standard quota regime. For teams under GDPR, EU AI Act high-risk obligations, or contractual data locality terms, the global endpoint isn't an option at all. Regional stacking, quota increases, and Provisioned Throughput are the only levers left.
There's a second reason the global endpoint matters specifically for DSQ workloads: Standard PayGo throughput tiers get evaluated at the organization level for traffic sent through global. So routing through the global endpoint isn't just a capacity strategy, it's also how the tier itself gets measured. Most teams should default to regional and treat global as a fallback target for workloads that don't involve sensitive data or batch processing. Global should never carry primary traffic when tuning, batch, or context caching is part of the pipeline.
Client-side rate limiting and exponential backoff (the defensive layer that prevents wasted requests)
Server-side quotas only tell half the story. A 429 still burns a request slot in some configurations, adds latency, and degrades the experience for whoever's waiting on the other end. Client-side rate limiting exists to stop the application from ever firing a request that's going to get rejected in the first place.
A token bucket is the standard approach: track available capacity in memory, refill it at whatever rate is allowed, and block or queue new requests once the bucket runs dry. That keeps an application from issuing a burst that blows past the per-minute ceiling, even accidentally.
Retries need their own discipline. On a 429 or a 503, wait an exponentially increasing delay before trying again, add random jitter so that multiple service instances don't all retry at the exact same moment and create a new spike, and cap the retry count somewhere reasonable, five is a common ceiling. Not every error deserves a retry, either. A 429 or 503 signals temporary exhaustion, so both are worth retrying. A 400 or 401 is not, because those errors mean something's wrong with the request itself, and retrying it just repeats the same failure.
Idempotency deserves particular attention here, because it's where retries turn expensive. If a request actually succeeded but its response got lost in transit, a naive retry doesn't just resend a request, it fires a second billable generation on top of the first P1 launch: add account-level AI spend ceilings beyond per-minute rate limits · Issue #1041 · vertex-studyAI/vertexED.ai. This is the exact failure mode flagged in the vertexED.ai production issue opened September 19, 2026: idempotency keys are what prevent that kind of double billing on retry P1 launch: add account-level AI spend ceilings beyond per-minute rate limits · Issue #1041 · vertex-studyAI/vertexED.ai.
A per-minute rate limit is not a spend ceiling. An account that stays within 60 requests per minute all day can still rack up serious cumulative provider charges over hours or days P1 launch: add account-level AI spend ceilings beyond per-minute rate limits · Issue #1041 · vertex-studyAI/vertexED.ai. Per-minute controls and account-period spend limits are separate concerns that must both be addressed P1 launch: add account-level AI spend ceilings beyond per-minute rate limits · Issue #1041 · vertex-studyAI/vertexED.ai. For user-facing applications on Firebase AI Logic, the default 100 RPM per-user limit is a reasonable starting point, but it needs tuning: loose enough to cover one user's legitimate session, tight enough that no single user can eat the shared quota that every other user depends on Gemini Enterprise Agent Platform.
Monitoring quota consumption before it becomes an incident
The baseline signal is serviceruntime.googleapis.com/quota/rate/net_usage in Cloud Monitoring, which gives per-project quota consumption and can be queried across time intervals to see how close each region and model is running to its ceiling. The console path through IAM & Admin, then Quotas & System Limits, filtered by "Vertex AI API," works fine for a quick spot-check. It's not built for alerting, though. Automated threshold alerts need actual Cloud Monitoring API queries running in the background.
Provisioned Throughput adds its own signal: spillover traffic. Monitoring dashboards report spillover separately from in-quota traffic, and any team that set up PT specifically to control cost should treat a spillover metric as something to act on immediately, not a curiosity to glance at during a weekly review.
What's worth an actual alert, rather than a dashboard glance: quota utilization climbing toward the ceiling (not just breaches after the fact), spillover events on PT workloads, and unusual per-account generation volume. That last category is what catches a denial-of-wallet pattern before it ever reaches a provider invoice. Teams that only reconstruct spend from the invoice are always working with a lag, and by the time that invoice lands, an expensive pattern may have already been running for weeks.
Agentic workloads make this harder still. A multi-step agent can generate a large number of model and tool calls for a single user action, which means measuring cost per individual API call stops being useful. The real unit of measurement has to be the full agent run, start to finish, not any one request inside it.
Spend ceilings and budget controls as a distinct layer from rate limits
Rate limiting and spend control solve different problems, and treating them as one thing is where budgets quietly blow past expectations. A service rate-limited to 60 RPM per endpoint can still generate substantial cumulative spend once it's running for hours across many users, because a rate limit governs throughput, not total dollars spent P1 launch: add account-level AI spend ceilings beyond per-minute rate limits · Issue #1041 · vertex-studyAI/vertexED.ai.
A production issue opened September 19, 2026 against a Vertex AI-backed application makes the gap concrete P1 launch: add account-level AI spend ceilings beyond per-minute rate limits · Issue #1041 · vertex-studyAI/vertexED.ai Gemini Enterprise Agent Platform. Every route had a per-minute rate limiter in place, which looked like solid coverage, but the system had no dollar-cost calculation anywhere and no monthly account budget P1 launch: add account-level AI spend ceilings beyond per-minute rate limits · Issue #1041 · vertex-studyAI/vertexED.ai Gemini Enterprise Agent Platform. That meant a single valid account could stay entirely within its per-minute limits while still generating substantial cumulative provider charges over time P1 launch: add account-level AI spend ceilings beyond per-minute rate limits · Issue #1041 · vertex-studyAI/vertexED.ai Gemini Enterprise Agent Platform.
Closing that gap takes a few pieces working together: a server-owned usage record tied to authenticated user, capability, and billing period; rolling hourly and daily guards layered on top of the existing per-minute limits; an account-period usage ceiling; and a global emergency ceiling on provider spend that isn't dependent on the provider's own billing tools to catch it. Retries and failover events can't be allowed to double-count against any of this, either, since idempotency has to hold at the accounting layer just as much as at the request layer.
Privacy sets a boundary on how this gets built, too. Raw prompts and responses have no place in a usage accounting table. Only fixed metadata belongs there: capability, provider, model, token count, cost. Nothing about what was actually asked or answered.
And the Gemini 3.x reasoning cost wrinkle resurfaces here in a different form. Because those models bill internal reasoning tokens as output at full rate, a short visible response can carry a real cost far above what its length implies. Any spend ceiling built on request count alone will systematically underestimate the actual exposure on reasoning workloads. Cost tracking has to be built on tokens and dollars, not request counts, or it's measuring the wrong thing.
Multi-project and multi-provider architecture for teams that need headroom beyond a single project
The project boundary on quota is real and it's useful. Regional stacking inside one project already adds up to 30,000 RPM per supported region; stacking multiple projects on top of that multiplies the ceiling again, and teams operating at real scale often end up needing both levers at once How to Manage Quotas and Rate Limits for Gemini API Requests in Vertex AI.
None of that comes free. Multi-project architecture means separate provider keys per project, separate monitoring setups to watch, separate billing accounts to reconcile. Multi-project scaling solves a real capacity problem, but it trades a quota ceiling for a management burden, and teams need to decide which constraint they'd rather live with before they build around it. Use of a resource in one project does not affect available quota in another (separate GCP projects give independent quota pools), making multi-project architecture a legitimate capacity strategy for high-volume teams. The model-provider boundary becomes the limit at Vertex AI's.
Sources
- How to Manage Quotas and Rate Limits for Gemini API Requests in Vertex AI
- P1 launch: add account-level AI spend ceilings beyond per-minute rate limits · Issue #1041 · vertex-studyAI/vertexED.ai
- Rate limits and quotas | Firebase AI Logic
- Gemini Enterprise Agent Platform quotas and limits | Google Cloud Documentation
- Generative AI On Vertex AI Quotas And System Limitsstay Organized With Collectionssave And Categoriz - Vertex Generative AI