Gateway-Enforced Redaction Pipelines Compared by Detection Method NER Regex and ML Models
Combined regex, NER, and ML detection catches sensitive data before it reaches model providers.
For teams handling PHI, a HIPAA-compliant AI gateway needs BAA coverage and redaction before data reaches the model provider. Concentrate offers managed PII and PHI redaction, with BAA availability on its paid plan. This comparison of gateway-enforced redaction pipelines explains why production configurations should combine regex, NER, and selective ML-based detection according to the data they handle, their latency budget, and their compliance obligations.
Why PII leaves the perimeter before anyone notices
Users and agents cannot reliably sanitize every prompt themselves. Sensitive data is part of enterprise AI use, and unmanaged personal accounts let that data leave without passing through corporate controls at all. A developer convention cannot govern traffic it never sees. Sensitive text can leave through any application or account outside the enforced path.
A model API is a third-party destination. Sending a name, SSN, or medical record in a prompt shares that information with an external processor and, by default, its logs. PHI sent to a provider without a BAA creates a presumed breach under HIPAA and may be a reportable disclosure. GDPR also reaches personal-data processing by companies serving EU users, regardless of where those companies are based. These obligations make the gateway boundary the appropriate chokepoint for a shared policy, enforced before routed prompts leave the perimeter and without changes to application code.
What gateway redaction actually does to a request
Gateway redaction is a synchronous step on the request path. It scans text for personal data and rewrites matched spans before forwarding text to a provider or writing it to a log store. Inspection covers outbound prompts and inbound responses. A match can trigger detection only, which records the finding without changing the payload, blocking, which rejects the request or response with a policy error, or redaction, which replaces the matched text and forwards the sanitized payload.
Irreversible masking replaces a value for good, such as changing alex@example.com to [EMAIL]. Done correctly, it produces anonymized data that cannot be linked back to a person and falls outside GDPR scope. Reversible tokenization instead substitutes a token whose mapping remains in a secure vault, allowing the correct value to return on the response path. GDPR Article 4(5) treats this as pseudonymization, so the data remains personal data.
Masking works well for logging and analytics, while tokenization works well for live flows that need to return personalized values. That choice precedes the detection stack. In either mode, a false negative leaves the original sensitive span untouched, so the replacement mechanism cannot compensate for a detector that never finds it.
What the three detection methods can and cannot catch
PII in model traffic extends beyond fixed-format identifiers. It includes names, contact details, governmental and financial identifiers, digital identities, credentials, and dates, while sensitive-data policies may also cover internal code names and proprietary source code. The formats differ too much for one detector. Regex matches predictable structures such as emails, SSNs, phone numbers, IP addresses, and API keys, with readable patterns and reproducible results. It misses names, addresses, and other personal information without a predictable format.
Named entity recognition, or NER, adds contextual coverage for people, locations, organizations, and addresses. Fine-tuned models use a fixed entity set and are built to find known types quickly and accurately. Zero-shot models such as GLiNER accept entity labels at inference time, so the labels can change, though accuracy is slightly lower on benchmarks. Backend choice changes coverage as well as performance. Default spaCy NER struggles with non-Western names, while transformer-based alternatives such as GLiNER and DeBERTa fine-tunes substantially narrow that gap.
Language-model detection reaches further into contextual and implicit references. A sentence such as “Please forward this to Sarah at the downtown office” requires more than fixed-format matching. NER is itself machine learning, but the ML/LLM category here denotes language-model-based detection beyond the entity-recognition layer. It can find more through context, but takes longer to process text and is less predictable.
How precision, recall, and latency differ across the three methods
Precision tells how often a detected span is truly sensitive, while recall tells how much of the sensitive content the detector finds. Latency is the time that detection adds to processing. Regex favors precision and speed on covered identifiers, adding under 2ms per request. A pattern cannot recognize a category it was never written to detect, however reliable its matches are within that category.
NER exchanges additional latency for broader recall. An NER model adds roughly 35ms, compared with approximately 180ms for an external PII API call, which favors small on-gateway models over a remote redaction service. Transformer variants also trade throughput for accuracy. Higher-accuracy models process fewer documents per second, while zero-shot variants offer adaptable entity coverage without retraining. The backend therefore changes both what the pipeline can recognize and how much traffic it can sustain.
GPT-4 class models achieve higher recall on contextual and implicit PII than regex or NER alone, although hybrids and some specialized models can match or exceed that recall. Throughput is their principal constraint. They process a small fraction of the documents per second supported by NER and incur the highest cost per detection event, making full-traffic scanning difficult to justify. Reported F1 scores do not remove this tradeoff or guarantee deployment performance. Clean test sets understate real-world misses on out-of-distribution text, so a strong aggregate score is not evidence of complete coverage.
Why layering methods beats choosing one
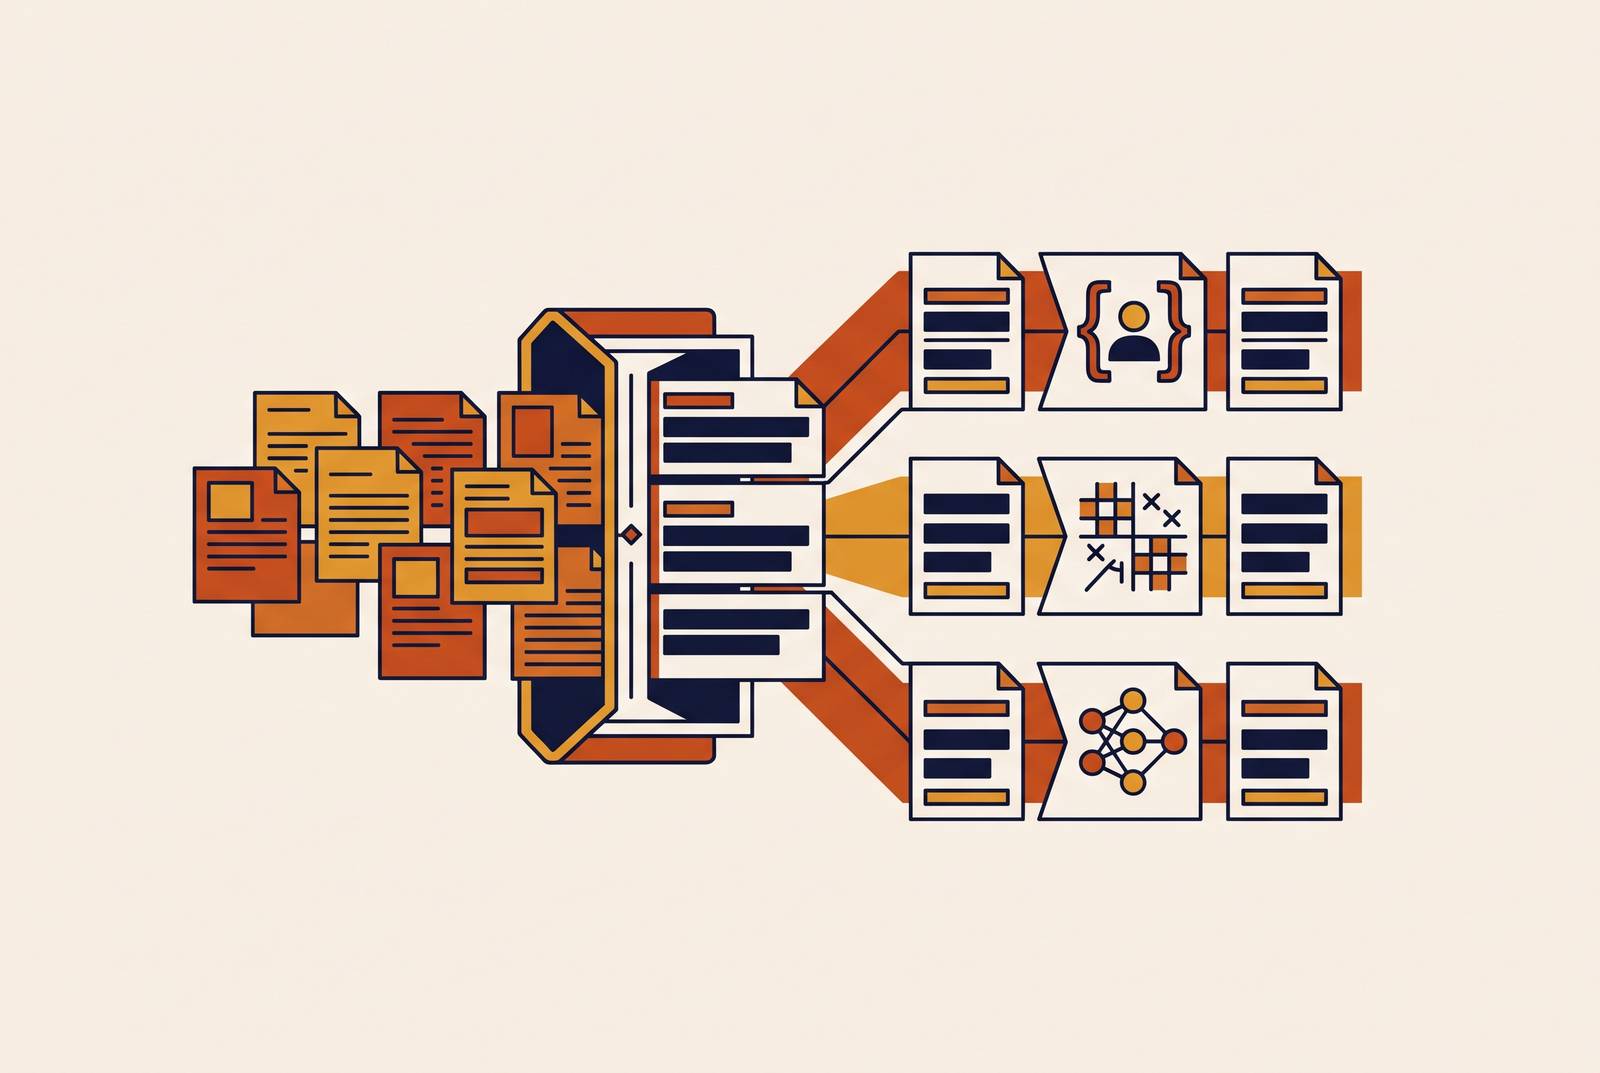
Layering assigns each detector the work it handles well. Regex runs first because structured matching is inexpensive, NER follows for names and addresses, and language-model checks apply selectively where contextual disclosure is the primary risk. This arrangement broadens coverage without imposing the slowest method on every request. The added latency remains a legitimate objection. However, an on-gateway regex and NER combination can stay under 40ms, well below the approximately 180ms associated with a remote PII API call.
Microsoft Presidio illustrates this architecture without being a detection model itself. It is a pluggable framework that combines regex recognizers with an NER backend, using spaCy by default and allowing alternatives such as GLiNER or a DeBERTa fine-tune. Custom recognizers add domain-specific entities without replacing the pipeline. Secrets need a distinct layer as well. Dedicated scanners cover API keys, tokens, AWS credentials, and connection strings rather than relying on NER or language-model detection to handle them. Layer selection should therefore follow the required entity coverage and sustainable throughput, rather than a preference for the most sophisticated model.
Matching detection method to PII type, throughput, and compliance surface
The practical decision framework starts with the intersection of data type and workload. Regex alone is sufficient for a scope limited to predictable structured identifiers such as card numbers, SSNs, emails, and phone numbers. Names, addresses, and references to organizations in free text need NER, and the choice of backend depends on how accurate it must be and whether the entity set needs to change. Contextual disclosures justify selective language-model checks on high-risk traffic. Credentials and API keys belong with dedicated secret scanners.
High-volume customer-facing agents and real-time support favor regex plus lightweight NER, because language-model detection is not viable on their hot path. Lower-volume clinical workflows and legal document processing can justify a full regex, NER, and language-model stack when their latency budget permits it.
Compliance adds constraints that performance cannot override. PHI workflows need PHI-specific coverage, such as the entity types supported by NVIDIA GLiNER-PII, and redaction within the perimeter before any external endpoint receives unredacted PHI. BAA coverage remains a separate requirement for the gateway and provider. Under GDPR, irreversible anonymization and reversible pseudonymization have different regulatory consequences, while CCPA and state-law deletion and disclosure obligations are undermined by uncontrolled prompt sharing.
How production gateways implement these detection layers
Gateway products differ in where detection runs and who operates it. LiteLLM supports NLP-based redaction through separately deployed Presidio containers, while Kong AI Gateway uses its AI PII Anonymizer Service. Those services become dependencies that teams must keep available. LiteLLM also provides a native regex-based content filter that requires no external service, distinguishing basic pattern matching from its separately operated NLP layer.
Detection does not always mean payload rewriting. Cloudflare AI Gateway documents DLP actions that flag or block sensitive data, but no redaction action that sanitizes matched content and forwards it. OpenRouter scans only requests, so it leaves response-path PII in model responses unchecked. The suitability of these different policy capabilities depends on whether the workflow needs detection, rejection, or continued processing with sanitized text.
Remote detection adds delay and requires teams to watch where the raw text goes. Concentrate offers managed gateway-enforced PII and PHI redaction at one API chokepoint across its supported providers, without a proxy for teams to deploy or maintain. It provides zero data retention on all plans, with HIPAA compliance including BAA availability on the paid plan, and SSO, RBAC, and audit logs available without an enterprise contract. Policy scope remains a separate evaluation criterion. Rules scoped by team, key, model, or tool call allow healthcare and marketing workloads to share a gateway without forcing identical treatment on different data.
Governance controls that make redaction enforceable at scale
Detection engines find sensitive spans, but access controls decide whether the policy is applied every time. Identity controls using OIDC, OAuth 2.0, SAML, or SCIM replace reliance on shared API keys and support per-team enforcement. Shared credentials make it hard to tell who used a policy exception. RBAC defines which teams can view, modify, or bypass rules, as well as which individuals may reveal a redacted value during an investigation. Audit trails then make those decisions available for compliance review.
Logs and traces can become the longest-lived copies of a prompt, so retaining raw text there defeats provider-path redaction. Tokenized pipelines also need governed access to the vault mapping and clear conditions for re-identification. Short vault TTLs limit that exposure.
For PHI-handling teams, access to governance cannot depend on organizational size. A five-person healthcare startup has the same regulatory obligations as a hospital system. SOC 2 Type II, SSO, audit logs, and a BAA should therefore be available from day one. The relevant buying criterion is whether enforceable controls and contractual coverage are accessible when PHI processing begins.
Choosing a detection configuration for a production redaction pipeline
A production decision begins with three questions in sequence. What PII types must be caught, what latency can the workflow tolerate, and what compliance surface must the policy demonstrably cover. Before selecting the stack, the team should resolve whether the application needs re-identification. For PHI, the architectural prerequisites remain redaction inside the perimeter and BAA coverage for the gateway, because detector quality cannot repair an incorrect data boundary.
For most production traffic, the starting configuration is regex for structured identifiers, dedicated scanning for credentials, and NER for names and addresses, with policies scoped per team and key. Language-model detection belongs on selected clinical notes, legal documents, or support transcripts where implicit references justify its cost. It does not belong on every request merely because its contextual recall is stronger. People still need to check samples of redacted traffic from time to time to find patterns of misses that automated detection and clean test sets fail to show.