Request Deduplication in High-Volume LLM Gateway Traffic
Deduplicating requests at the gateway saves costs and latency at scale.
A meaningful share of LLM requests at high traffic volumes are duplicates, and every one that reaches a provider costs money and adds latency it didn't need to. Production traces show daily request volume climbing, peaking, and falling rather than holding steady, and research on high-volume LLM serving confirms that two days with identical request counts can represent very different amounts of actual compute work, depending on input structure and the state of the serving instance's KV cache. That variability matters because it means redundancy isn't a fixed, predictable tax. It fluctuates with traffic patterns, retry storms, and how services are wired together.
Published production data puts near-duplicate requests at 15 to 25% of total traffic. At that share, catching duplicates is a first-order lever on cost and latency, something to build into the system from day one rather than a cleanup task for later. The economics are different from traditional API traffic, too. A single redundant LLM request can burn through thousands of tokens, and the dollar cost of that duplication scales with prompt length, not simply with how many requests came in. A long document summarization prompt retried twice costs twice as much, every time, at whatever rate that prompt's length commands. Multiply that by a retry loop, a webhook that fires twice, three microservices independently issuing the same query, or a user resubmitting a question they already asked, and the waste adds up fast across a production system handling real volume.
The Gateway Layer as the Right Enforcement Point
Deduplication has to live in the infrastructure layer, not scattered across application code and not left to providers to handle. Neither of those two places can see the whole picture, and only a system that sees every request can catch the ones that repeat.
Calling provider SDKs directly from business logic is already a known anti-pattern in production AI systems, because routing, retries, and caching all need a gateway that every service routes through. Providers themselves don't offer a reliable substitute. OpenAI's and Anthropic's bulk endpoint custom_id fields exist to map requests to results, not to deduplicate anything, result ordering isn't guaranteed, and providers don't return byte-identical outputs on repeated calls. Enforcement has to sit upstream of the provider, not inside it.
Application-level deduplication has its own failure mode. Building the logic into each service separately causes it to drift between teams, get forgotten when someone spins up a new microservice, and leave no unified audit trail, the same breakdown that makes per-service PII redaction unreliable in practice. A gateway sitting in front of every provider call avoids that by intercepting duplicates before they generate a single token, saving both the provider cost and the wait time for a response that already exists somewhere. Deduplication belongs alongside the other functions a production gateway already handles. Provider abstraction, routing, retries and fallback, caching, observability, and rate limiting all depend on the gateway seeing the full request stream, and deduplication is a natural extension of that same visibility. Each one catches a different class of duplicate, and together they form a pipeline rather than a set of options to pick between.
Request normalization: making equivalent prompts look identical before any comparison
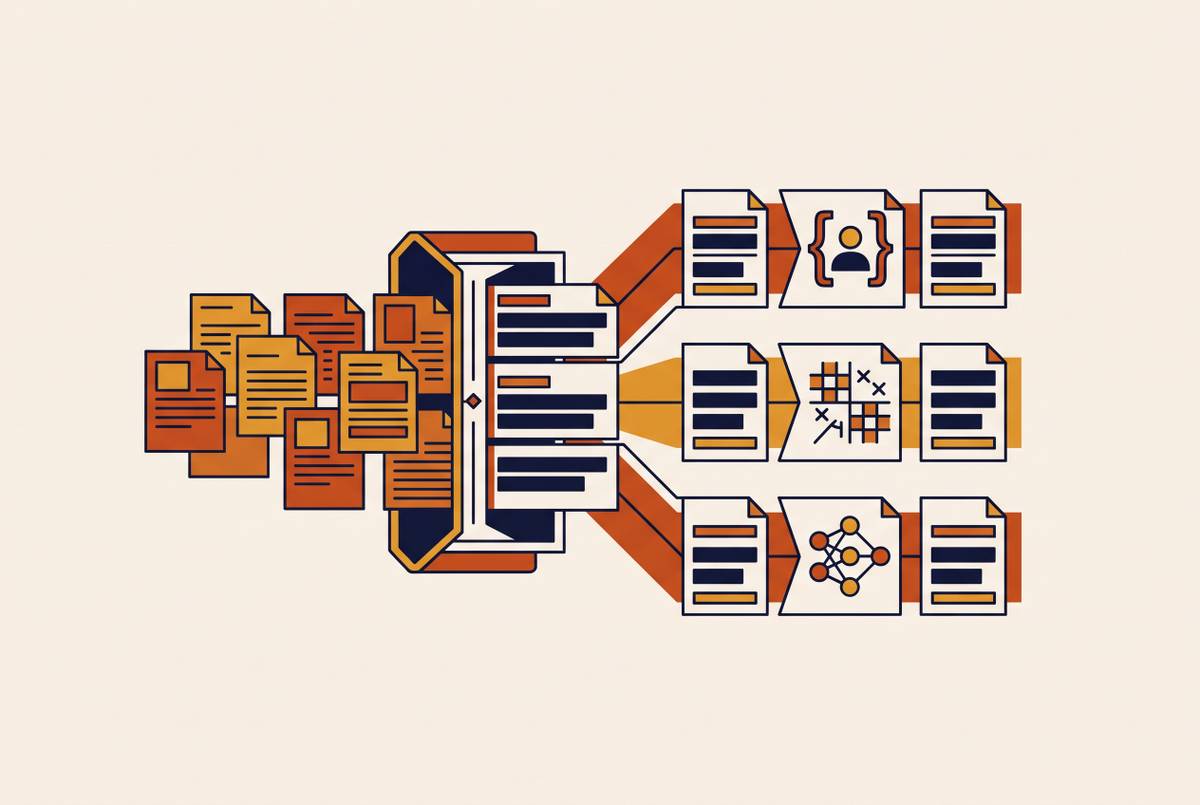
Before a gateway can tell two requests are duplicates, it has to strip away the surface differences that mean nothing to the model itself: whitespace, field order, casing. Two requests can carry the exact same prompt and still look completely different as raw bytes, and no comparison method downstream works reliably until that gap is closed.
The sources of this spurious variation are mundane but constant: trailing whitespace, inconsistent newline handling between clients, JSON field order that shifts across SDK versions, and temperature or parameter defaults that differ from one client library to the next. None of that changes what the model is being asked to do. Normalization doesn't touch the meaning of a request, it only removes the noise a model would treat identically anyway. A prompt submitted with a trailing newline and one without it should produce the same fingerprint, because the model doesn't care about the newline.
Skipping this step has a measurable cost. A naive exact-string match, run without normalization, catches roughly 2% of duplicate traffic by industry measurement. Normalization is the step that makes hash-based deduplication worth doing at all, because it collapses the surface variation that would otherwise cause a true duplicate to register as a miss. The normalization layer should also resolve model identifiers to a canonical form. A request naming gpt-4o and a request naming the same model under an alias need to land on the same normalized representation, so that routing and deduplication are working off the same underlying reality.
Content hashing: detecting exact and near-duplicate requests efficiently at high throughput
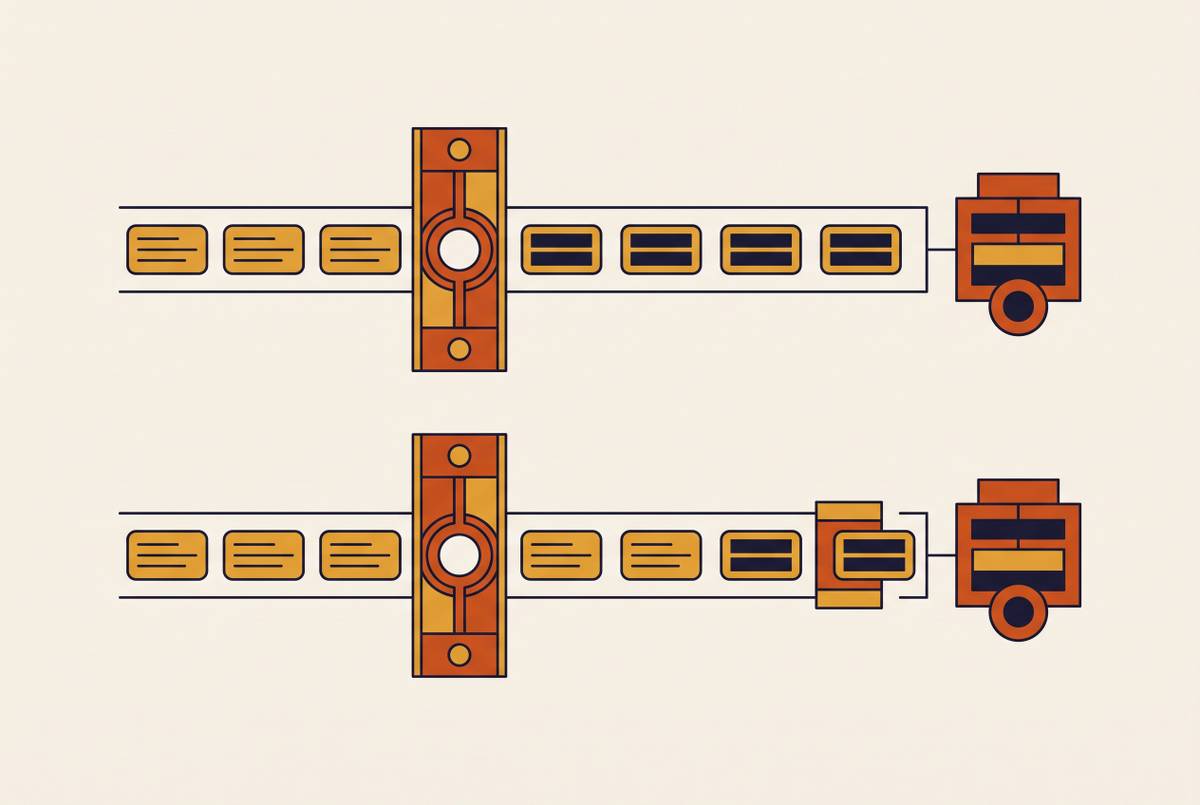
Once a request has been normalized, hashing its content produces a short, fixed-length key. The gateway checks that key against a cache in sub-millisecond time, which makes catching exact duplicates close to free no matter how much traffic is flowing through.
The pattern is straightforward: normalize the request, hash the canonical form (the prompt, the model, the parameters), check that hash against a fast store, return the cached response on a hit, and store the new response on a miss. This catches the most common duplicate patterns in production: the same prompt retried after a timeout, two services independently issuing the same query at the same moment, a webhook that fires twice. None of it requires any understanding of what the prompt means. It's pure pattern matching on normalized content. That naive 2% hit rate from exact-string matching becomes something much more useful once normalization and hashing work together, collapsing the surface variation before the comparison happens.
Running this well in production means getting a few details right. TTL policy on the hash store has to match the nature of the response: short-lived answers, like real-time data lookups, need short TTLs, while stable knowledge responses, like document summaries or classification templates, can sit in cache much longer without going stale. Hash collisions are a real risk but a manageable one. Using a cryptographic hash like SHA-256 and including the model identifier and parameters as part of the hash input keeps two prompts routed to different models from ever sharing a cache key. There's also a useful connection to how LLM serving actually works at the infrastructure level. Research on request scheduling shows that a request whose prefix tokens are already sitting in an instance's KV cache costs less compute to serve. Gateway-level hash deduplication goes a step further than that: it stops the request from reaching the provider at all, which beats a cheaper computation every time. What hashing can't do is catch two prompts that mean the same thing but are phrased differently. That's a separate problem, and it needs a separate technique.
Idempotency keys: preventing duplicate charges during retries and failover
Content hashing solves duplicate content. It doesn't solve the problem of a client that retries a request because it believes the first attempt failed, when in fact the original call is still in flight or already succeeded. That's what idempotency keys are for.
The mechanism works like this: the client generates a unique ID for each logical operation and attaches it to every attempt tied to that operation. The gateway claims that ID atomically before it calls the provider, and if a retry comes in carrying the same ID, the gateway returns the stored response instead of making a second call to the provider. This matters most in scenarios where a double-billed call is both costly and consequential: operations where a single API call carries real expense, and any workflow where the downstream system is stateful, like order processing, agent tool calls, or database writes triggered by a model's output. An agent that calls a tool to charge a customer's card should never do it twice just because a network blip triggered a retry.
Idempotency keys and content hashing solve different problems and belong together rather than in competition. Hashing catches repeated content regardless of where it came from. Idempotency keys catch repeated attempts at the same logical operation, regardless of whether the content matches anything in cache. Support for this varies by gateway. Some ship request-hash idempotency with configurable TTLs built in, some expose the key as a surface but leave actual enforcement to whatever retry logic the client implements, and some don't offer an idempotency primitive at the gateway level at all. There's also a billing wrinkle: a billing ledger needs idempotent ingest so the same request isn't counted twice, but the gateway's deduplication logic and the billing meter are usually separate systems. Teams that treat gateway logs and billing records as interchangeable end up double-counting spend, and the fix is reconciling by event ID rather than by content hash.
Semantic matching: catching duplicate intent when the wording differs
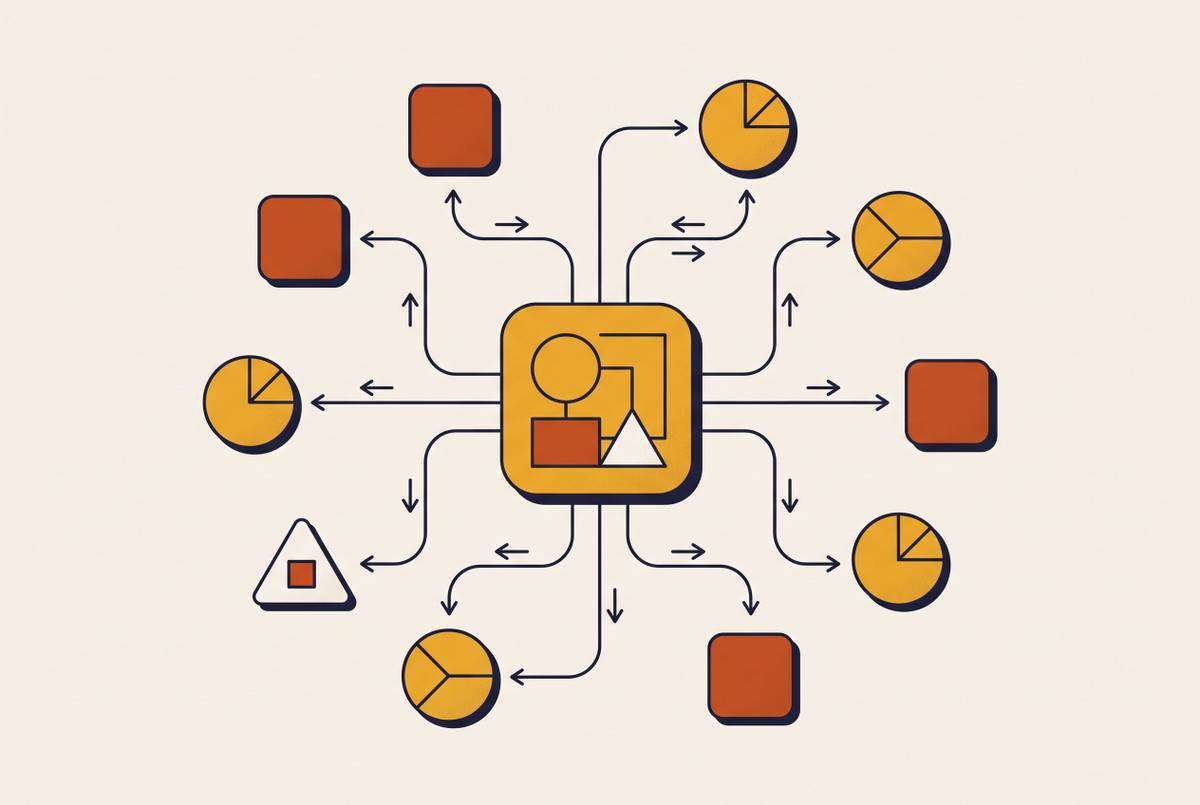
Normalization and hashing both work on the literal content of a request. Neither one catches two prompts that ask for the same thing in different words, and in user-facing applications, that population of near-matches is often larger than the population of exact duplicates. Semantic matching is built to close that gap.
The scale of the opportunity is substantial. Real users ask the same underlying question in dozens of different phrasings, which accounts for the gap between those two numbers. The mechanism behind it embeds each incoming request as a vector, searches a vector store for near neighbors above a similarity threshold, and returns the cached response on a hit, falling through to the provider and storing the new response on a miss. Getting the similarity threshold right is what makes this safe. Setting the threshold too low causes semantically distinct prompts to share responses, which produces wrong answers. Setting the threshold too high causes the hit rate to drift back down toward the exact-match baseline.
Semantic matching costs more to run than hashing does. Embedding a request and searching a vector store both add latency that a hash lookup doesn't carry. The way to manage that cost is pipeline ordering: run semantic matching only after a cheaper hash check has already missed, not on every single request. It also isn't the right fit everywhere. It works well for stable knowledge domains like FAQ handling, document summarization, and classification, and it works poorly for anything where exact wording carries intentional meaning, like code generation or structured data extraction, where small differences in a prompt are supposed to produce different outputs. One more detail carries real operational weight: a semantic hit on one user's query should never be served to a different user if the cached response contains that first user's private information. The gateway needs to scope semantic cache lookups by tenant or by data sensitivity tier before any of this runs in production.
Where Each Technique Sits in the Pipeline
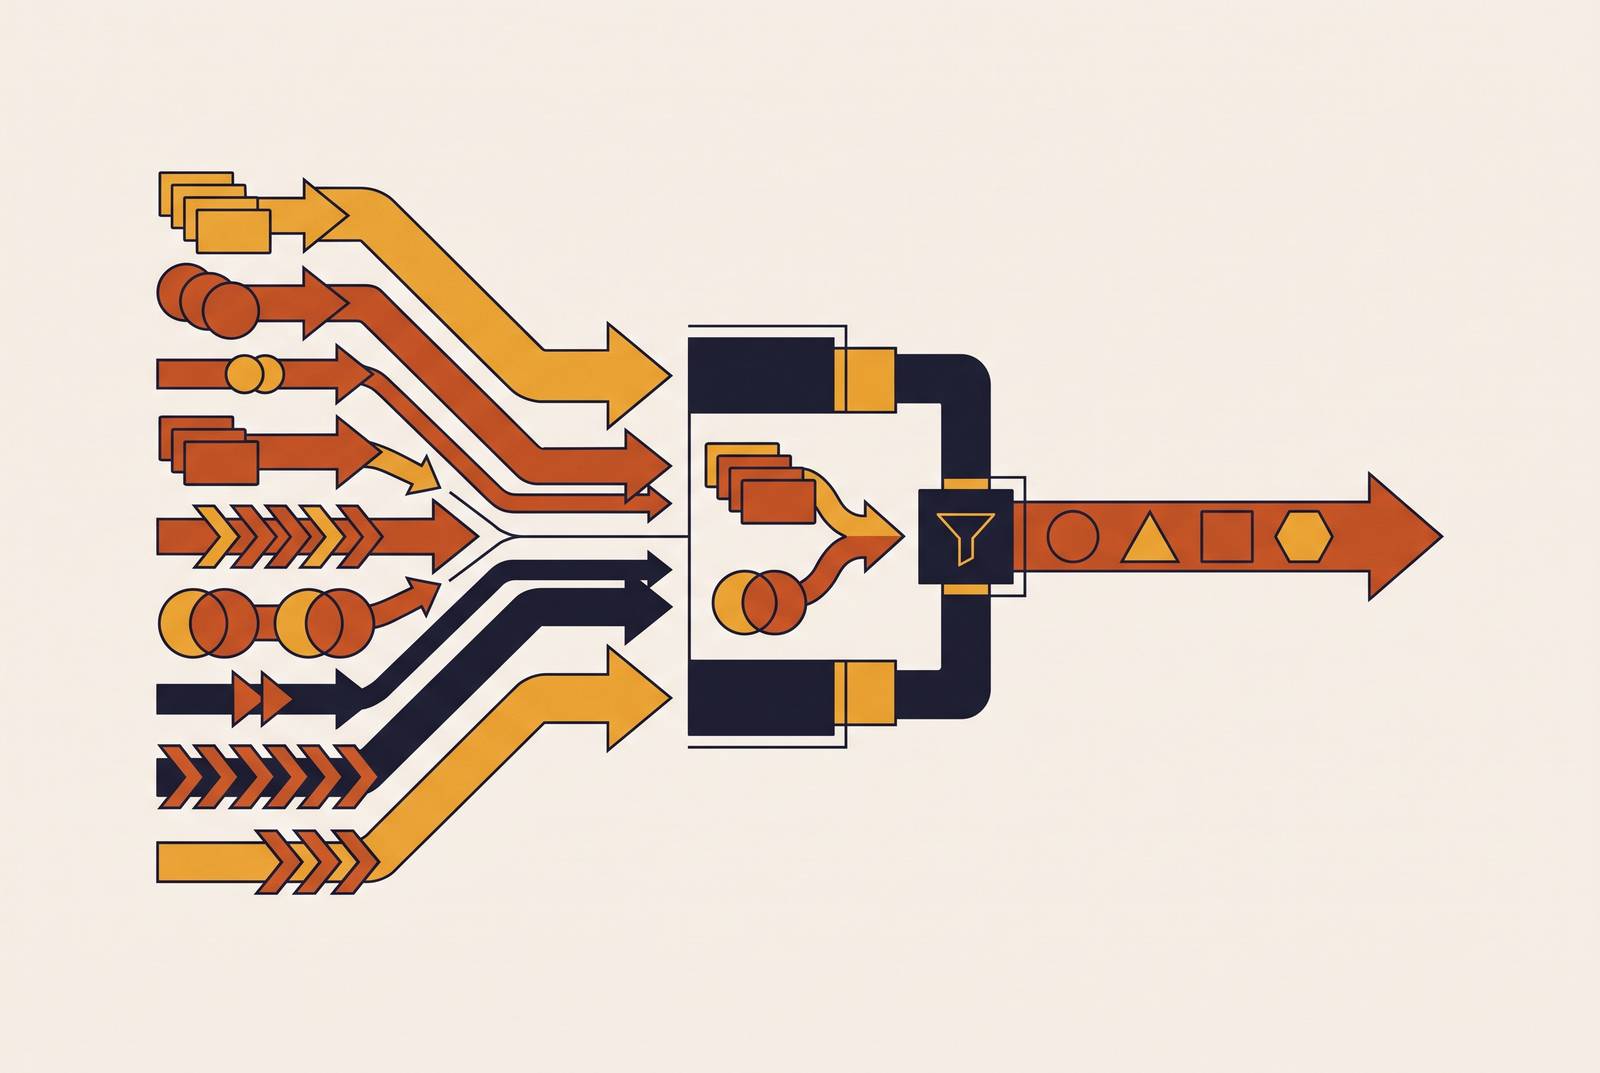
These four techniques aren't competing options a team picks among. They address different classes of duplication, sit at different points in the same request pipeline, and each one catches what the step before it can't.
Normalization comes first, and on its own it catches nothing at all, because its only job is preparing requests so a later comparison can actually work. Hashing comes next, and without normalization in front of it, hashing collapses on trivial surface variation and produces false misses, treating two identical prompts as different just because one had a trailing space. Idempotency keys sit alongside hashing rather than behind it, because they solve a different problem: without content hashing in the mix, idempotency keys alone miss the case where the same content arrives from two independent callers using two different request IDs. Semantic matching comes last, and it needs to, because running it without a hash pre-filter wastes embedding compute on requests that a cheap hash check would have caught anyway.
Streaming responses complicate this pipeline in a specific way. A gateway serving a streamed response has to buffer enough of the stream to confirm a cache hit before it can return the cached version, or else accept that streaming requests simply bypass certain layers of deduplication. Either choice is workable, but it needs to be a deliberate policy rather than something left to chance. Observability matters just as much as the pipeline order itself. A gateway operating this system should log which layer produced each hit, whether that's an exact match, a semantic match, or an idempotency match, along with the TTL of the entry that matched and the provider call that got skipped, all without logging the raw prompt content or any personal information it might contain. Put together, the order runs normalize, then hash, then check idempotency keys, then fall through to semantic matching only on a miss, with the provider called as the last resort.
What to Implement First
Most teams get the most value fastest by starting with idempotency keys and content hashing, because neither one requires any machine learning infrastructure and both catch the costliest duplication scenarios right away.
Idempotency keys come first if the application has retry logic, webhook consumers, or agent tool calls anywhere in it, because a double-billed LLM call in those situations is immediate, visible, and easy to audit. Normalization and hashing follow close behind. That combination needs nothing more than a fast key-value store like Redis, delivers exact-match deduplication at sub-millisecond overhead, and produces hit rates visible in gateway logs within days of going live.
The build-versus-buy decision affects each of these layers. Self-hosted open-source gateways such as LiteLLM take 2 to 4 weeks of engineering time to deploy for production use, on top of ongoing infrastructure for Redis, PostgreSQL, monitoring, and deployment automation, before the deduplication pipeline itself is even built. A managed gateway such as Concentrate AI handles normalization, hashing, idempotency, and the full deduplication pipeline across 21 providers through a single API, without requiring a team to run the underlying cache infrastructure, manage TTL policy model by model, or rebuild the pipeline every time a new provider gets added. For organizations where AI usage is growing faster than internal governance can track, that overhead compounds on its own: every new provider, every new model, every new team workspace is one more surface that needs covering.
Sources
- Best 5 AI Gateways for LLM Failover and Fallback in 2026
- Building LLMs in Production 2026: A Step-by-Step Playbook
- Simple is Better: Multiplication May Be All You Need for LLM Request Scheduling
- A Year in LLM Serving: Workload Evolution, Caching and Load-Balancing
- LLM Integration for Production Apps: Rate Limiting, Caching & Fallbacks That Actually Work