Operational Burden of LLM Provider Key Rotation at Scale
Managing multiple LLM provider keys at scale requires architectural solutions, not spreadsheets.
Managing LLM provider API keys at scale is not one task but several incompatible ones running at the same time. Every provider a team adds brings its own SDK, its own authentication model, and its own key lifecycle, and none of those pieces talk to each other. The burden this creates does not grow one unit at a time. It compounds.
Multi-provider LLM architectures and the credential management problem that grows faster than teams expect
Adding OpenAI, Anthropic, and Google to a single application makes the engineering task look, on paper, like "rotate the API keys" three times. What looks from the outside like a single administrative concern, "rotating API keys," is actually a set of parallel, incompatible workflows that must be run simultaneously.
OpenAI requires someone to manually delete old keys. As of September 2026, newly created project API keys can carry configurable expiration dates and maximum-lifetime policies, but that configuration has to be set up and maintained on top of the deletion step. Google takes a different approach entirely: service account keys don't expire on their own, and expiration only happens if an organization policy is written and applied to force it. One provider wants manual deletion, one offers optional expiration windows a team has to configure, and one needs an organization-level policy just to get keys to expire, and lining these up shows the incompatibility is the whole story. None of the three mechanics map onto each other, so no single rotation runbook covers more than one provider.
Without something sitting above all three systems to coordinate this, the work doesn't get centralized by habit. It gets split up by necessity. Different teams end up holding different API keys, running different provider SDKs, tracking different rate limits, and pulling different usage reports, each team working from its own partial picture. This is a structural property of multi-provider architecture, not a tooling gap that a better spreadsheet fixes: add a fourth provider and the number of incompatible rotation workflows a team has to run in parallel doesn't go up by one, it goes up by one entire authentication model, one entire key lifecycle, one entire set of edge cases. The size of the problem tracks the number of providers in the stack, not the size of the team trying to manage them.
The cost of deferred or ad hoc key rotation
Teams that treat provider keys like shared passwords, one key per provider, distributed across repos, never reviewed, do not avoid rotation; they defer it until it becomes a crisis. They push it down the road until it surfaces in production as an incident: a quota spike nobody can explain, a credential found in a public repository, a key that should have been dead months ago and wasn't.
That last failure mode is the quiet one. A key that was never revoked stays valid long after the access it was issued for stopped making sense, and it stays exploitable the entire time nobody's looking at it. The danger is a live credential sitting in a codebase, waiting.
The compliance side of this is wider than most teams expect going into their first SOC 2 audit. SOC 2's Trust Services Criteria are principles-based: they expect to see controls around key rotation, audit logging, and encryption at rest, but they don't hand a team a specific rotation cadence, a format for immutable per-provider access logs, or a required encryption standard. That absence of a prescribed checklist sounds like flexibility. In practice it means a team has to design its own rotation policy, its own logging approach, and its own encryption posture, then defend all three choices to an auditor who is grading judgment, not compliance with a fixed rule.
For a team that didn't build any of this in from day one, the retrofit is not a quick patch. It means auditing every deployed service to find where provider keys live, updating CI/CD pipelines to support rotation without a deploy freeze, coordinating the change across every team that touches those services, and validating that the audit logging an auditor will actually ask for exists and works, all while production traffic keeps running. That's a multi-team, multi-sprint undertaking, not an afternoon of cleanup.
The shared-key pattern makes all of this worse. When one provider key is shared across many teams or services, removing one person's or one integration's access means revoking the whole key, and revoking the whole key means every other service using it breaks at the same moment. There's no way to rotate that key without some downtime unless there's tooling in place built specifically to prevent it. So teams either hold off on rotation and let the security debt pile up, or they rotate under pressure, at the worst possible time, with no clean way to back out if something breaks. These costs are the predictable output of running a flat-key architecture against a multi-provider stack, and they point directly at the architectural fix.
The gateway layer as the right architectural intervention, not a workaround
Provider API keys belong in the gateway, not scattered through application code. That single decision about where credentials live turns key rotation from a production fire drill into a routine platform operation.
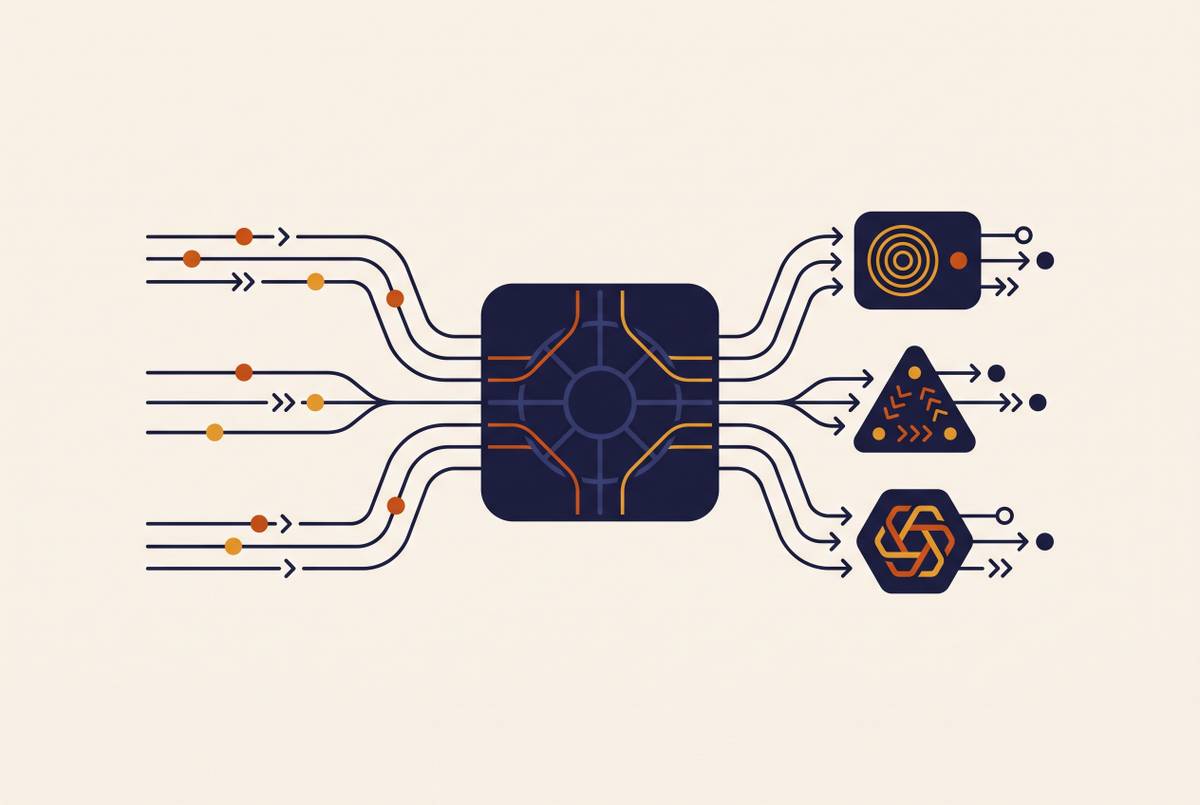
The mechanism is a virtual key layer. The gateway holds the real provider credentials and hands out scoped virtual keys to each service or team. An application authenticates to the gateway using its virtual key, and the gateway quietly swaps in whichever real provider credential is current. No application should ever need a redeploy just because a provider issued a new key upstream. The provider-facing credential changes behind the gateway; the application-facing credential stays fixed.
Virtual keys can be scoped tightly, to a specific model, a specific budget, a specific type of request. Pulling access from one team or shutting down one integration is a single operation inside the gateway rather than a rotation that touches every other consumer of that provider key. This is what breaks the shared-key trap described above: when a developer leaves or an integration needs to lose access, the gateway revokes that one virtual key and leaves the underlying provider key, and everyone else's access, untouched.
Rotation without downtime becomes routine rather than a special project, because the provider key rotates at the gateway layer while the application's virtual key stays exactly where it was. The heterogeneous workflows from the first section, OpenAI's manual deletion, Google's policy-based expiration, Anthropic's own mechanics, all become something the gateway handles internally, instead of something every application team has to learn and implement on its own. Concentrate AI, a fully managed LLM gateway, is built around exactly this placement: incompatible rotation mechanics across OpenAI, Anthropic, and Google become a gateway-internal concern rather than something every application team must understand and implement separately.
Two rotation patterns a gateway enables
Once a gateway owns the credential, a team gets to choose how rotation happens, and the choice should follow deployment topology, not preference.
In-place rotation updates every model reference pointing at a provider key all at once. It's fast, but it assumes every consumer can handle a brief moment of re-authentication without throwing an error. This pattern fits when the number of consuming services is small, the provider's credential mechanics are simple to swap, and the traffic pattern can absorb a short transition window.
Replacement-key rotation is more careful. The gateway provisions a new provider key, moves model aliases over to it in stages, and keeps the old key alive until the last consumer has made the switch, leaving a clean rollback point at every stage of the migration. This pattern makes sense when many models or environments share the current key, when the provider's credential mechanics are genuinely complicated, or when traffic volume is high enough that an all-at-once authentication failure isn't something the business can absorb. It only works because the gateway, not the application, owns the credential. The application never knows or needs to know which specific key is active at any given moment in the migration.
Teams running a flat key architecture, no gateway between application and provider, don't get a choice here. The replacement-key pattern isn't available to them at all, because there's nothing in the stack to stage the migration. They rotate all at once or not at all, so rotation keeps getting pushed off.
Key management as part of a full gateway feature set
Key rotation is the sharpest edge of the multi-provider operational burden, but it's one piece of a larger set of concerns a production gateway has to own, and the same decision to centralize credentials is what makes the rest of this list possible. Six features tend to separate a production-ready gateway from a thin proxy: unified provider abstraction, model routing, retries and fallback, caching, per-request observability, and rate limiting built on virtual keys. Each one leans on the credential centralization the gateway already provides.
Virtual keys that drive rate limiting and budget enforcement use the same scoped-credential mechanism that makes clean rotation possible. A runaway agent loop can't blow through its quota, because the gateway holds the credential and checks the limit before the request ever reaches the provider.
Per-request observability tracks input tokens, output tokens, latency, cost, and which feature and team generated the call. Without it, figuring out why a bill spiked turns into a forensic investigation after the fact. With it, a cost regression is caught within hours instead of appearing as a surprise on the monthly invoice.
Fallback chains let the gateway reroute to an alternate provider the moment one provider degrades, with no manual intervention required. Because the gateway already holds credentials for every provider in the stack, it can execute that fallback without any change at the application layer.
The pattern repeats across all six features: work that would be expensive to build separately for every application, every team, and every provider becomes one implementation at the gateway layer, and every consumer of that gateway inherits it automatically, with no extra integration work on their end.
Security and compliance requirements in the gateway credential model
For a security or compliance team, the gateway's credential model has to prove to an auditor that access was controlled the whole time. The gateway's credential model answers that question directly, because it's also the single enforcement point where security and compliance controls actually get applied, for any team handling sensitive data, not just the ones in a formally regulated industry.
Audit logging becomes realistic once every provider request runs through one layer. Each request carries structured metadata, which virtual key sent it, which model answered, how many tokens it used, what came back, and that produces an immutable trail without anyone having to instrument each application by hand. Production-grade gateways expose this as metrics and traces through Prometheus and OpenTelemetry, plugging into the observability stack a team already runs instead of standing up a second, parallel audit system.
PII filtering, secret masking, and prompt injection detection only work from the gateway, because the gateway is the one place in the stack that sees every request before it reaches a provider. Secret masking automatically strips API keys, tokens, and credentials out of model responses before they reach whatever consumed them downstream, closing a risk that would otherwise sit invisibly in application logs until someone happened to find it. A self-hosted proxy with no security configuration applied routes straight through to providers with no scanning: every one of these protections has to be added by hand and kept up to date, and a managed gateway removes that configuration burden from application teams.
Zero Data Retention routing has become a standard compliance control enforced at the gateway layer: requests get sent only to providers that have contractually agreed not to retain or train on prompt data, a rule the gateway enforces without any application code ever needing to know it exists. The compliance surface is broader than most teams anticipate before their first SOC 2 audit.
RBAC and workspace isolation turn into properties of the data plane itself once the gateway owns tenancy. Retrieval gets filtered by tenant at the index, caches get keyed by tenant, and credentials get minted per tenant, so a tool call physically cannot borrow another tenant's authority even by accident.
Provider outages and compliance-driven model suspensions as the forcing function for multi-credential resilience
Uptime numbers for any single provider understate the real production risk, because failures tend to cluster. A major outage is rarely one provider going dark. It's several going down in the same window, often during the exact stretch when traffic is heaviest.
Some outages come from compliance decisions, not infrastructure failures, and those can't be anticipated or planned around at the application layer. On June 12, 2026, the US Commerce Department ordered Anthropic to suspend access to Claude Fable 5 and Mythos 5 for foreign nationals, and Anthropic responded by disabling both models for every customer, immediately, with no advance notice and no firm date for restoration.
Teams whose application code called those model endpoints directly had no way to reroute without writing new code and pushing a deployment. Teams running a gateway that routed those model aliases to configurable targets could update one routing rule and move on, with the application layer untouched the entire time. That gap, a code change and a deployment on one side, a single routing update on the other, is what gateway-managed credentials and routing are actually built to close, and it's the same architectural choice that solved rotation, compliance logging, and fallback: hold the credential and the routing decision in one place, and every downstream problem gets smaller.