Routing-Layer Telemetry for Multi-Provider AI Cost Tracking by Team and Project
Track AI spending by team and project in real time at the routing layer.
Someone on the finance team asks a simple question: what did the company actually spend on AI last month, broken down by team and project. In most organizations, nobody can answer that cleanly. Cost attribution falls apart because of how the requests are wired. When application code calls a provider directly, no single system ever sees the full picture.
Each team ends up with its own API key, its own SDK, its own retry logic, and its own usage report. None of these views talk to each other, so there's no shared ledger anywhere in the company, just a pile of disconnected receipts.
The application layer can't fix this, because every application only sees its own traffic. Multiply that blind spot across a dozen services and three or four providers: the result is a stack of provider invoices arriving at month's end with aggregate totals and zero context.
Reconstructing which team or project drove which charges after the fact means digging through logs, cross-referencing timestamps, and guessing at which service called which model at 2 a.m. Most finance and engineering teams never finish that work. They give up somewhere around "close enough" and move on.
A typical AI stack in production today runs through several layers: the application, then an orchestration or agent framework like LangGraph, CrewAI, or LlamaIndex, then an LLM gateway, and finally the providers themselves. Of every node in that chain, only one sees every request from every service headed to every provider: the gateway. That single fact is the reason the rest of this piece exists.
What the gateway layer captures
The routing layer is the only point in the stack where cost attribution can be complete, consistent, and happen in real time.
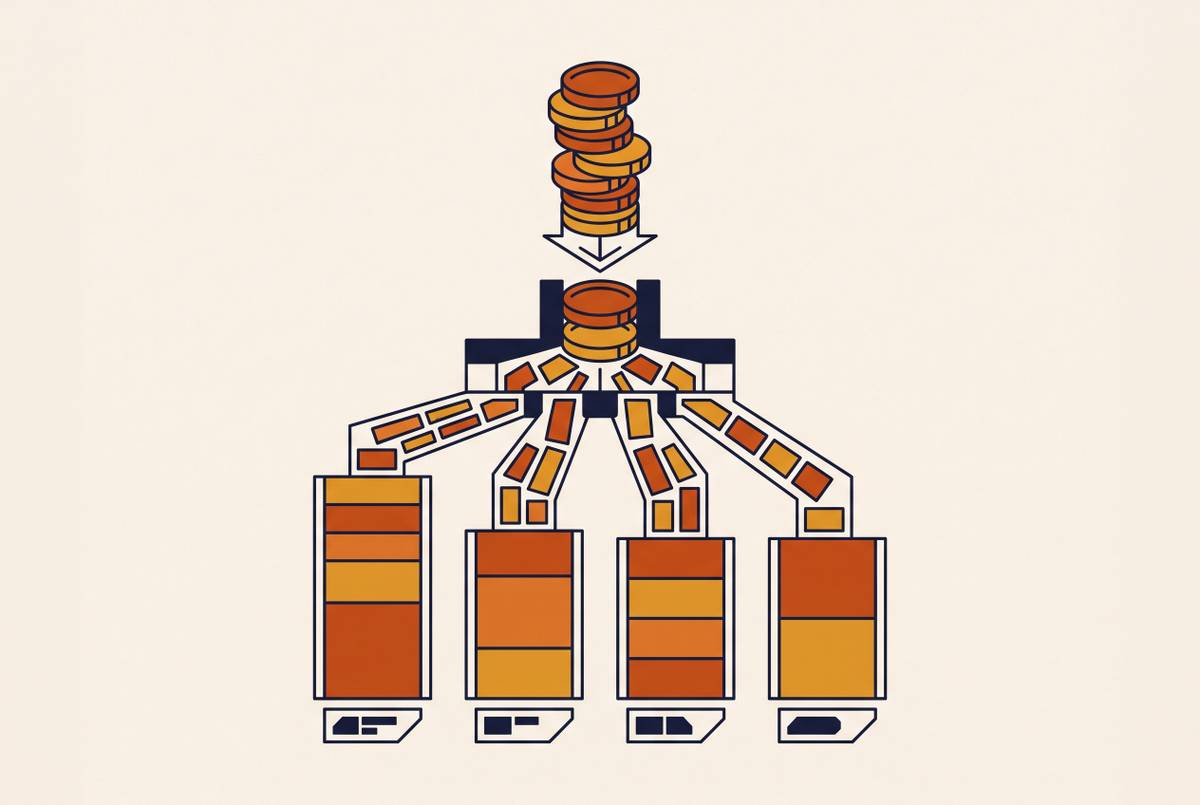
Because the gateway intercepts every request before it leaves the organization, it can attach identity, team, project, and policy metadata to each call no matter which application sent it or which provider ends up receiving it. A request doesn't need to carry its own context through three layers of orchestration code. The gateway stamps that context on the way through.
A production LLM gateway logs, for each request: input and output tokens, estimated cost, which model and provider got picked, what routing decision was taken (primary, fallback, or served from cache), latency, and the identity of whoever made the call, whether that's a team, a user, a virtual key, or a tenant. That's a different kind of record than a provider invoice, which only shows a lump sum per billing period with no breakdown by caller.
The gateway also captures what no invoice ever will: which routing decision fired, whether a fallback kicked in because a primary provider was down, whether a cached response avoided a provider call entirely, and which policy applied to that specific request. An LLM gateway is model-aware, token-aware, and prompt-aware in a way a generic API gateway or scattered application logging simply isn't built to be. It understands that two calls to the same endpoint can differ by orders of magnitude in cost, depending entirely on how many tokens moved through them.
That completeness is what turns attribution from a guess into a fact. A dashboard built on gateway telemetry can answer "what did Team X spend on Project Y last Tuesday" with a precise number, not an estimate stitched together from five different invoices.
The dimensions telemetry must capture to make attribution usable
Capturing data isn't the same as capturing the right data. Telemetry that misses the dimensions that actually matter produces dashboards that look busy but can't answer the questions engineering and finance teams are actually asking.
A usable telemetry record needs team or workspace, project or application, virtual key or user identity, model and provider, routing decision (primary, fallback, or cache), input and output token counts tracked separately, estimated cost per request, and a timestamp. Dropping any one of these makes a whole class of questions unanswerable. Team and project fields answer the core finance question: what did each group spend, and on what. Routing decision answers a harder one: was this request served by the primary model, a fallback, or a cache, and that distinction changes the entire cost story. A project whose spend spikes in a given week might simply be dealing with a provider outage that pushed its traffic onto a more expensive fallback model, and without routing decision captured as its own field, that spike looks like unexplained waste.
Raw token totals, even when captured correctly, aren't the most useful number on their own. Cost per task and cost per workflow tell a more actionable story: what does a unit of business output actually cost, and how does that compare to whatever process it replaced. A raw total only tells you spend went up. It doesn't tell you whether that increase bought more output or just more waste.
None of this works if it's reconstructed after the fact from scattered logs. Token and cost accounting has to be attributed at the point the request passes through the gateway, where team, user, and tenant context already exist, rather than pieced together later from whatever logs happen to survive.
Virtual key hierarchies, budget enforcement, and telemetry-driven control
Telemetry on its own is a monitoring system. It tells you what happened. The real value of the routing layer is that it can act on what it sees, blocking, throttling, or rerouting requests based on live spend, not last month's.
Virtual key hierarchies are the structural piece that makes this possible. Budgets can then be set at any level that makes sense: per key, per team, per model, per provider, or per tag. When a budget threshold gets hit, the gateway blocks further requests from that key immediately, rather than letting spend run unchecked until an invoice shows up weeks later. Tag-based tracking covers the cross-cutting case too: a project that spans several teams can still be tracked as a single unit, as long as requests get tagged consistently at the gateway.
Platforms that route across multiple providers can enforce these limits directly, blocking overspending, restricting which models a key can reach, or firing alerts before a budget threshold is crossed, which turns the telemetry stream from a reporting feed into an active governance tool. Access control sits alongside budget control here too: a team handling sensitive customer data can be restricted to specific compliant endpoints at the gateway level, without touching a line of their application code. That access-control piece connects to a larger set of compliance requirements covered further down.
When engineers can see their own cost-per-task trend sitting next to their quality metrics, cost-aware habits tend to form on their own, because the feedback loop is immediate and personal. When the only signal finance gets is an aggregate bill at month's end, the response is usually a blunt, company-wide mandate, and blunt mandates tend to degrade quality along with cost.
Routing decisions and cost
The routing decision itself is a cost event. Telemetry that records only the final call to a provider, and not the reasoning that led there, misses the information needed to explain why costs moved the way they did, which makes cost trends almost impossible to diagnose or improve.
Different routing strategies produce genuinely different cost profiles, and a telemetry system has to tell them apart. Cached responses return at zero provider-token cost, and logging a cache hit as its own event type makes an accurate cost-per-task number possible.
This section names a real limitation. Gateway cost tracking can diverge from the figures on an actual provider invoice, because the gateway estimates cost by applying its own price catalog to the token counts the provider reports, rather than reconciling directly against the invoice line items. That catalog can be stale or incomplete. Monthly reconciliation against vendor invoices stays necessary even with good gateway telemetry in place, and the telemetry itself should flag this as an estimate.
Fallback chains that land on a cheaper, well-provisioned model during an outage provide a real cost floor when things go wrong. A degraded response beats a failed request, and logging that fallback event separately lets finance tell outage-driven cost spikes apart from genuine spend growth. Accurate routing telemetry is the condition that makes it possible to tell cost optimization apart from cost drift.
Security and compliance requirements that routing-layer telemetry must satisfy
The gateway is the right enforcement point for data compliance for the same structural reason it's the right point for cost attribution: it sees every request before any of them reach a provider. Putting redaction or audit logic inside individual applications instead lets policy drift team by team, and it leaves no single, unified audit trail behind.
PII redaction at the gateway follows a specific pattern: detect PII in the prompt, redact it before the request goes to the provider, restore the original values once the response comes back, and write an audit record containing only decision metadata and a redaction summary, never the original prompt content. If the original prompt text gets logged somewhere "for evidence," the compliance gap remains. It's just moved from the provider to the log store, where it's arguably more exposed.
Audit logs that actually satisfy compliance review need four properties. They need to be immutable, so entries can't be edited or deleted after the fact. They also need to be exportable to a SIEM or an external compliance system.
The EU AI Act, in Articles 19 and 26(6), requires both providers and deployers to retain logs for at least six months. Gateway-level audit logs satisfy that requirement by design, as long as the platform was built with it in mind from the start. Application-level logging, spread across a dozen services maintained by a dozen different teams, rarely satisfies that requirement consistently across all of them.
Healthcare deployments carry their own version of this. HIPAA's Security Rule technical safeguards map directly onto gateway capabilities: TLS 1.3 for data moving over the wire, AES-256 for logs at rest, virtual-key RBAC for access control, and immutable gateway logs standing in for audit controls. These are the same infrastructure doing the same job it does for cost attribution, applied to a different regulatory requirement.
How Concentrate AI delivers routing-layer telemetry as a managed capability
Everything described above, the attribution, the enforcement, the audit trail, requires infrastructure that someone has to build and keep running.
Concentrate AI connects engineering teams to more than 130 LLM models through a single, unified API, with no separate provider keys to juggle, no bespoke integration code per provider, and no self-hosted infrastructure to keep patched and running. Every request that passes through Concentrate AI's gateway carries attribution metadata, including team, key, model, provider, fallback route, token counts, and estimated cost, recorded in real time rather than pieced together from an invoice weeks later. Spend visibility breaks down by team, project, key, model, and provider, and budget enforcement blocks requests outright once a threshold is reached, instead of just sending an alert after the money is already spent.
The compliance capabilities described in the previous section aren't held back for a premium tier. Concentrate AI also doesn't layer a per-token platform fee on top of provider pricing, which matters directly for the economics of this whole approach: telemetry and attribution infrastructure shouldn't be what erodes the return on AI spend that the attribution itself is supposed to protect.
Self-hosting a gateway shifts the operational weight of telemetry pipelines, audit log infrastructure, and budget enforcement onto engineering teams who would generally rather be building product. And on the routing itself, the position is that automatic model routing without visibility into the decision behind it isn't a feature worth having. Teams should be able to see where their requests are being routed and why, not just trust that a black box picked reasonably.
What engineering and finance teams can act on
Telemetry at the routing layer changes what engineering and finance teams are able to do, not just what they're able to see.
For engineering teams, a cost regression, say a model swap that quietly raised per-task cost, is visible in the data within days rather than waiting for the monthly invoice, the same way a performance regression gets caught through ordinary monitoring rather than a customer complaint, and cache hit rates, visible in the same stream, show exactly where semantic caching is cutting down provider calls and where it isn't catching anything at all, which is as much a signal about where to invest next as it is a cost report.
For finance and compliance teams, real-time spend broken out by team, project, and provider replaces the old routine of reconstructing an invoice after the fact, and chargeback or showback becomes a straightforward exercise. Budget enforcement at the gateway means finance can set a hard limit that the infrastructure itself enforces, rather than hoping engineering teams police their own spend. Audit logs that are already exportable and immutable satisfy a compliance review without anyone needing to build a custom reporting pipeline just to answer an auditor's questions.
This move from reacting to a bill after it arrives to governing spend as it happens produces the organizational shift described here, visible in how spend decisions get made. That shift is what separates a team that finds out about a cost problem in next month's invoice from one that catches it the same week it starts.