Open Source LLMs for Production Coding Workflows
Governance and routing are the real production challenge for open-source coding models.
The real challenge for teams running open-source LLMs in coding pipelines has nothing to do with finding a model that writes good code. It comes down to governing, routing, and sustaining access to that model once more than one team depends on it. The pattern starts small and familiar: one team gets API access to an open-weights model, builds it into an application, and ships. A second team does the same thing a few weeks later. A third follows. Each ends up managing its own keys and its own workaround for rate limits, with no shared view across any of it.
Kagitha's enterprise LLM gateway paper puts a number on how bad this gets in practice. When finance tried to find out which teams were spending what, the answer came back as a spreadsheet of guesses. When security asked which data had reached which model, the answer was worse than a guess. Token spend stays invisible until the invoice lands. Data flows stay invisible until an audit forces someone to go looking. Picking the models was the easy part. Nobody had built a system to govern access to them.
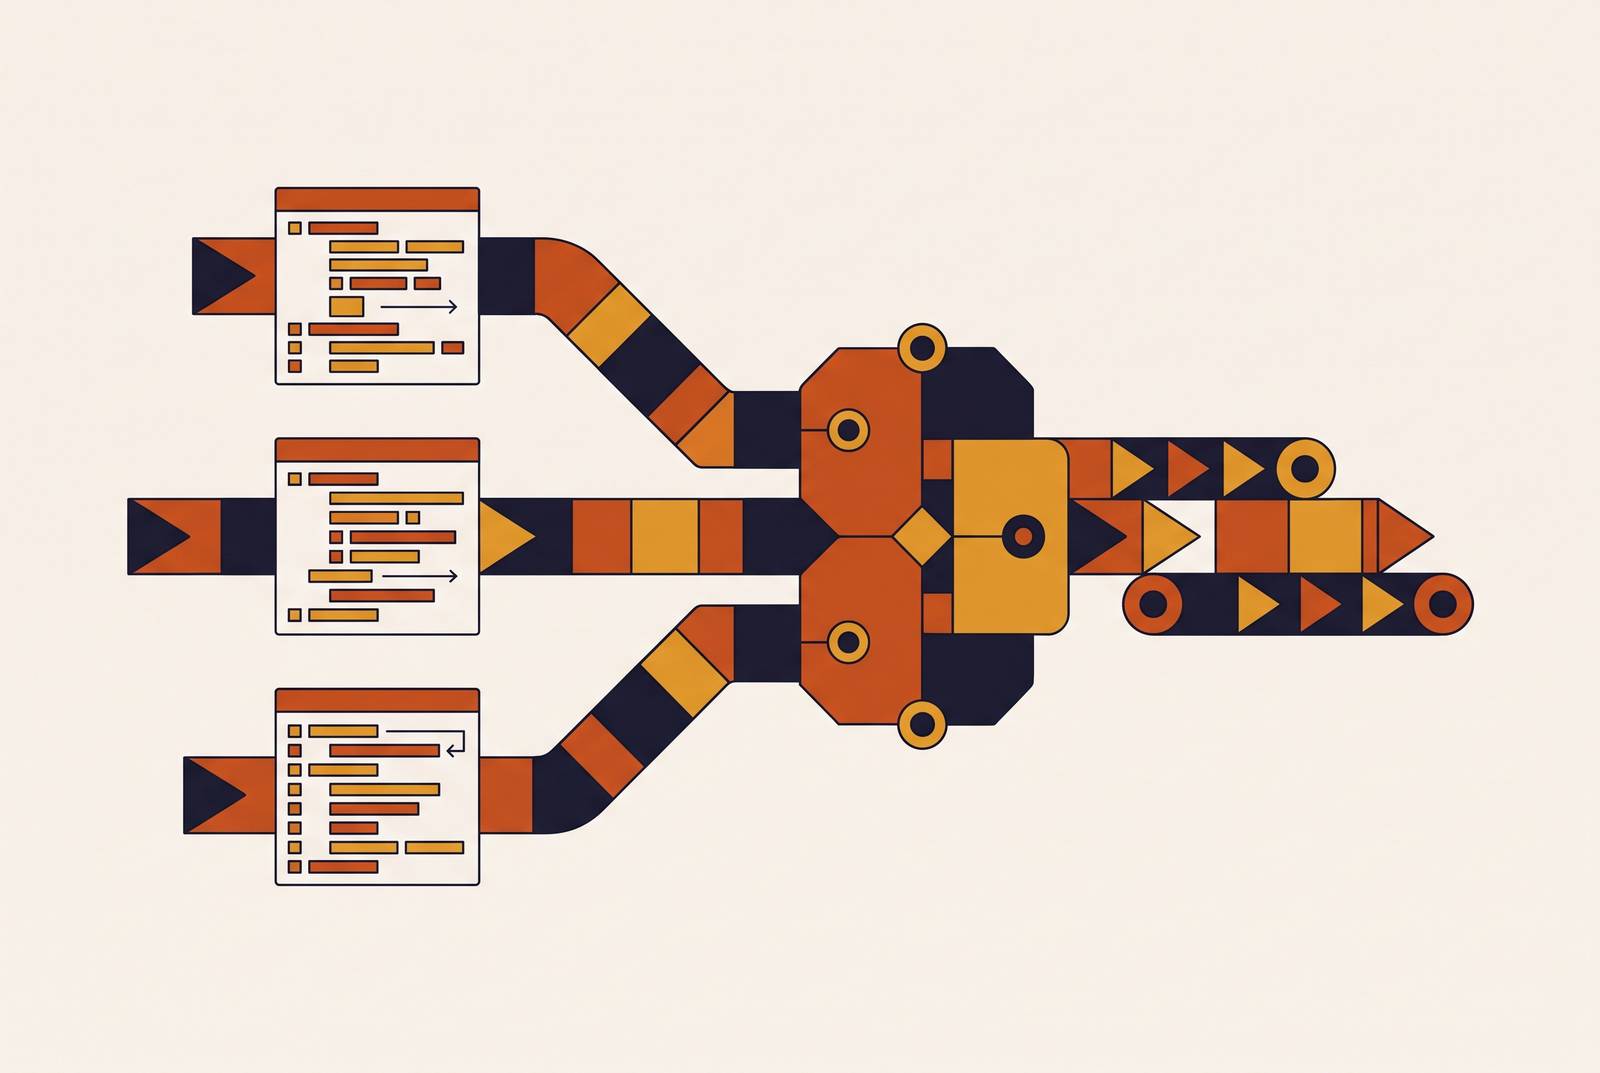
Agentic coding pipelines make this worse by multiplication. A single task in a coding agent can chain several model calls together, planning, generation, test execution, review, so any weakness in visibility, routing, or policy gets repeated once for every call in the chain. The gap that opens up is between what open-weights models actually offer, which is capable, self-hostable inference, and what production engineering actually requires, which is controlled, observable, governed access shared across teams. Closing that gap is the real work. Everything else in production coding infrastructure follows from it.
Closing the Gap Between Model Access and Production Control
An LLM gateway is not a nice-to-have layered on top of a working system. It is the control plane, so a company can actually sustain running multiple models across multiple teams in production.
The architecture is simple to describe even though what it replaces is not: application talks to the gateway, and the gateway talks to the AI provider or the self-hosted model. One layer owns the infrastructure concerns that used to be duplicated across every team's codebase, so no application has to write its own provider-specific logic. The LLM Gateway Design Guide lays out six concerns a gateway has to own to do this job: provider abstraction, routing, retries and fallback, caching, observability, and rate limits.
Picture a company running four different workloads at once: one model answering customer support questions, a different one driving a coding assistant, a self-hosted model handling anything sensitive, and a cheaper provider doing high-volume classification work. Without a gateway, every application has to understand each of those providers on its own terms, including their auth schemes, their rate limits, and their quirks. With a gateway, applications talk to one standardized internal endpoint, and the gateway handles the translation underneath.
Coding workflows need this architecture more than most, because agentic support matters just as much as model routing does. Tool calls, multi-step orchestration, and memory providers all need the same observability and governance as a plain chat completion. FloTorch's 2026 gateway buyer's guide makes a related point: a tool built purely for routing between models can start to buckle once a RAG pipeline, an agent orchestration layer, and tool calls all need to run through the same control plane at once.
A gateway does not pick the best open-source model for a given coding task on its own. That decision is a separate problem, and the gateway exists as the infrastructure that makes solving it well even possible. With governed, observable access in place, the next question becomes which models deserve that access, and for which jobs.
Choosing and tiering open-source coding models: where the benchmark picture stands
Open-source models no longer trail commercial frontier models on coding, not the way they used to. That changes the real question teams face, from whether to use open-source models at all to which open model fits which task.
DeepSeek V4-Pro-Max ranks 8th overall on SWE-Bench Verified, but it does not lead open-source coding performance on that benchmark. Kimi K3 holds the title of strongest open model for frontend coding as of July 2026, topping the Frontend Code Arena, while DeepSeek V4 Pro leads open models on raw SWE-Bench Verified. No single open-weights model wins everything, and that split is the point: different coding tasks reward different models, and teams that pick one model for all of them are leaving performance or cost on the table.
Cost and speed trade off against each other in ways that are not uniform across these models. DeepSeek V4 Flash costs substantially less per unit of input and output than V4 Pro, often at comparable or even lower latency. Which tier makes sense for a given call depends on how much judgment that call actually requires, not just where a model lands on a leaderboard.
That points to a practical answer: tiering. Route the planning calls and the judgment-heavy work, architecture decisions, complex refactors, to the strongest model you have. Route bulk execution and classification work, linting suggestions, docstring generation, test scaffolding, to smaller, cheaper models built for volume. Tiering only pays off if the routing layer can act on these rules dynamically. Without a gateway enforcing them, teams fall back on whatever model a developer happened to hard-code, and that default usually means overpaying for simple tasks that never needed a frontier model.
One objection is why not just pick the best model and run it everywhere, skipping the complexity of tiering? At the call volumes an agentic coding pipeline generates, running a frontier model on every classification or generation subtask produces a bill that does not match the value of the output it's producing. The fix is routing, which is the subject of the next section.
Routing strategy: how the gateway applies model tiering dynamically in a coding pipeline
Intelligent routing does not happen on its own. It requires an explicit policy, and teams that define that policy at the gateway layer, rather than scattering it through application code, are the ones that can change the rules without redeploying anything.
The router applies the tiering logic from the previous section on every incoming call: strongest model for planning and judgment-heavy work, smaller models for bulk execution. It evaluates these rules each time based on who's calling, what kind of task it is, and the current budget state. Kagitha's Azure architecture describes this as a policy engine checking each request against the tenant's policy bundle, covering which models are allowed, where the budget stands, and whether the caller is within its rate limits, all before the call is routed anywhere.
Fallback routing matters just as much for reliability as tiering does for cost. If a self-hosted model's endpoint starts degrading, or a provider serving an open-weights model starts throwing errors, the gateway can route the call to an alternative on its own. Without that layer in place, the application feels the outage directly, with no buffer between the failure and the end user.
Semantic caching works alongside routing rather than replacing it. FloTorch's buyer's guide notes that moving from exact-match caching to semantic caching can cut redundant model calls by 40 to 70 percent on real-world workloads. Coding pipelines generate exactly the kind of repetition semantic caching is built for: the same test generation pattern, the same docstring format, requested over and over with slightly different wording. Catching those repeats cuts cost without touching which model handles the call.
None of this should live as an informal convention. Routing policy needs version control and an audit trail, the same as application code does, because moving high-judgment calls to a cheaper model is a correctness risk, not a minor configuration tweak. A change like that can quietly degrade output quality long before anyone notices a drop in the metrics, which is exactly the kind of risk that governance and compliance processes exist to catch.
Token spend in coding pipelines: why agentic workflows break standard cost assumptions
Agentic coding workflows break the assumption that spend scales predictably with request volume. A single instruction from a developer, something as plain as "fix this bug," can set off a chain of planning, generation, test execution, and review calls, and the total cost of that chain stays hidden on an invoice until the chain completes.
Practitioners have landed on a useful correction here: judging cost per token pushes teams toward using AI less, which defeats the reason they adopted it in the first place. The metric that actually matters is cost per task, per workflow, or per unit of resolved work, measured against what the process cost and how long it took before AI entered the picture. A bug fix that costs more in tokens than a developer's time would have cost is a bad trade regardless of how cheap each individual token was.
Validating an agent workflow means tracking token consumption per task right alongside correctness. A workflow that lands on the right answer but burns several times the expected cost to get there has a defect in it, not a minor inefficiency to shrug off.
Catching that defect requires treating metering as a stream, not a batch job run once a day or once a week. Token counts need to flow into per-team, per-project, and per-model totals within seconds of each call, because that speed is what lets a team cut off a runaway loop before it burns through a month's budget. Kagitha's metering design puts it directly: every call emits token counts, latency, model, tenant, and team, and the metering pipeline turns that stream into budgets, alerts, and chargeback instead of a report someone reconstructs after the month closes.
This is not a theoretical risk. Zuplo's 2026 AI gateway guide describes a concrete failure mode: a bug in a retry loop can burn through a monthly budget in minutes. That argues for hard budget controls enforced at the gateway itself, set up hierarchically by team and project, rather than soft alerts that go to an engineer's inbox after the damage is done. Industry analysis found that only 34% of companies had mature cost management processes in place in 2025, so most organizations running agentic workflows today have no real defense against exactly this scenario. A gateway that shows spend in real time, broken down by team, project, key, model, and provider, removes the need to reconstruct what happened after the fact. Spend becomes visible as it happens instead of something finance assembles from logs a month later.
Data security and compliance requirements that coding pipelines make non-negotiable
Code sent to a model provider is not harmless text. It routinely carries credentials, API keys, customer identifiers, and proprietary business logic, which makes PII redaction and data governance requirements that have to be built in from the start, not features added once something goes wrong.
The compliance checklist for production AI is no longer vague. SOC 2 Type II, ISO 27001, HIPAA where it applies, and the NIST AI Risk Management Framework all address or emphasize non-repudiation, each to its own degree. Meeting them requires audit systems that record the authenticated principal behind each call, the virtual key used, the target model, token counts, latency, and any content guardrails that got triggered along the way.
PII redaction has to happen before a prompt ever reaches the model. Data masking swaps sensitive values, customer names, ID numbers, API keys, for realistic placeholders before the call goes out, so the model can still produce useful output without ever seeing the real private data behind it. Coding assistants make this risk concrete rather than abstract: developers paste code containing hardcoded secrets, database connection strings, or sample customer records into prompts constantly. Without redaction enforced at the gateway, those values travel straight to the model provider.
The same governance has to extend to embeddings used in retrieval. Sensitive values need redaction or tokenization before embedding. Every chunk needs metadata attached for owner, source, freshness, and sensitivity. Records that hit their retention limit need a deletion workflow that actually runs. The gateway is where this gets enforced, not something left to each application to implement on its own.
Role-based access control in a coding pipeline has to separate four distinct permissions that get conflated more often than they should: who can change an agent's workflow, who can edit its guardrails, who can view customer PII inside logs, and who can push changes to production. Blurring those four together is exactly the governance failure that autonomous coding agents expose once they're given enough autonomy to act without a human approving every step.
Supply chain risk deserves attention on its own, apart from prompt-level data leakage. In March 2026, LiteLLM's PyPI releases v1.82.7 and v1.82.8 were backdoored through a compromised CI/CD pipeline, specifically a poisoned Trivy security scanner that exfiltrated LiteLLM's PyPI publish token. The malicious releases were quarantined within hours, and they harvested credentials specifically from unpinned pip installs. Pinned Docker deployments were unaffected. In June 2026, a separate LiteLLM RCE chain, tracked as CVE-2026-42271, entered CISA's Known Exploited Vulnerabilities catalog. The gateway itself has to be treated as part of the supply chain under review, not just the applications sitting on top of it: it sees every prompt that passes through it and holds every provider key in the system, so its security posture, its update discipline, and how it handles credentials all fall inside the organization's compliance scope.
If you choose a managed gateway, the provider carries the burden of supply chain risk management instead of your internal engineering team carrying it alone. That distinction carries real weight against the alternative, which is running self-hosted infrastructure that has to be patched, monitored, and audited independently by the same team already responsible for everything else.
Reliability design for production coding pipelines: fallbacks, uptime, and self-hosted model risk
Reliability is harder to engineer for coding pipelines than for most other AI features, because a coding agent sits directly in a developer's workflow. When it goes down, work stops rather than degrading gracefully.
Fallback routing, covered earlier as a cost and performance tool, is also the primary defense against downtime. If a self-hosted model's endpoint degrades, or a provider serving an open-weights model starts returning errors, the gateway can shift traffic to an alternative automatically, so the failure never reaches the application directly. That matters more for coding pipelines than for a typical chat interface, because a coding agent mid-task, partway through a planning or generation step, has state to protect. An abrupt failure partway through a chained sequence of calls can leave a task half-finished in a way that's harder to recover from than a single failed request.
Self-hosted open-weights models carry a specific version of this risk. That's a reasonable trade for the cost savings and data control self-hosting offers, provided the gateway layer in front of it treats the self-hosted model as just one more routable target with its own fallback path, not the single point of failure the whole coding pipeline depends on.
The reliability pattern that holds all of this together is the same one that runs through routing, cost control, and compliance: the gateway sits in the critical path of developer tooling, and every property that matters, uptime, auditability, budget enforcement, data governance, gets enforced at that one layer instead of being rebuilt separately inside every application a team ships.