Chargeback Models for AI API Spend Across Business Units
Capture API calls at the gateway to split AI costs accurately across your teams.
LLM cost visibility doesn't come from the monthly invoice. It comes from capturing who made each API call, to which model, at what price, the moment the call happens, and from enforcing that capture at the one point every request has to pass through: the gateway. Providers like OpenAI and Bedrock bill in totals and model names, not business units, so tracking spend by team and project means building that structure yourself, before the invoice ever arrives.
Provider Invoices and Business-Unit Chargeback
Provider billing was built to answer a narrower question than the one finance is asking it to answer now. OpenAI and Amazon Bedrock report token counts, model identifiers, and totals at the account level, with no internal business taxonomy attached. The invoice can tell an organization how much it spent but not who spent it or why. That gap didn't matter much when one team ran one project through one account. It matters a great deal once account-level data is asked to answer request-level questions, since a business-unit lead, engineering, and procurement end up seeing three different numbers because the data was never structured to resolve to that level.
An invoice shows that the platform team's account spent money. It cannot show which downstream feature triggered that spend, because the IAM identity calling Bedrock is usually a shared service account or a gateway role, not the team or product actually consuming the output. AWS has started closing part of this gap: as of April 2026, Bedrock supports IAM principal-based cost allocation, writing the calling identity into Cost and Usage Report 2.0 and letting Cost Explorer filter by principal tag. That's a real improvement for organizations that route calls through distinct IAM roles per team. But it still identifies the account making the call, not the feature or workflow behind it, and any shared gateway serving multiple consumers through one role still leaves unresolved which consumer behind that role actually generated the request.
The practical result appears every month at close, when a business-unit lead reads one number in a finance report, an engineer reads a different number in application logs, and someone in procurement reads a third number off the raw invoice export, and none of the three numbers agree, because each is trying to extract request-level accountability from a billing system that was only ever structured to hold account-level totals. Account-level billing data from providers like OpenAI and Amazon Bedrock reports token categories, model identifiers, and cost totals, but carries no internal business taxonomy, so it cannot answer which team, product, or feature drove a given API call. Provider invoices report only account-level totals and provider identity, so they can't distinguish a consuming feature from the shared platform service account making the call on its behalf.
What request-level attribution requires: the minimum data model
Before any chargeback model can run, every LLM call needs a fixed set of fields captured at the moment it happens, not reconstructed from logs after the fact. The minimum set includes team_id, service, environment, provider, model, request_id, input_tokens, output_tokens, unit_price, computed_cost_usd, and timestamp, and a request missing any of these can't be reliably assigned to a cost center once the month closes. Environment values need a controlled vocabulary in lowercase snake_case, rejecting a free-form string like "marketing-west" the moment it's submitted rather than letting it slip into the data and surface as a mismatch at month-end.
OpenTelemetry's GenAI semantic conventions give this schema a vendor-neutral backbone: attributes like gen_ai.operation.name, gen_ai.provider.name, gen_ai.request.model, gen_ai.usage.input_tokens, and gen_ai.usage.output_tokens stay consistent whether a team swaps providers or switches tooling, so traces and metrics remain comparable across the stack. That consistency matters more as the number of providers in use grows, since a schema tied to one vendor's quirks breaks the moment a second provider enters the picture.
Three things ultimately have to be true before any allocation model works: usage has to be measured in clear units like requests, tokens, or gigabytes processed; a unit cost has to be tied to each of those units; and each unit of usage has to map to an owner, whether that's a department, a product, or a specific team. All three depend on the schema above existing before anyone tries to divide a bill. Skipping the schema leaves the allocation model with nothing solid to allocate.
Why the gateway layer is the reliable place to enforce attribution
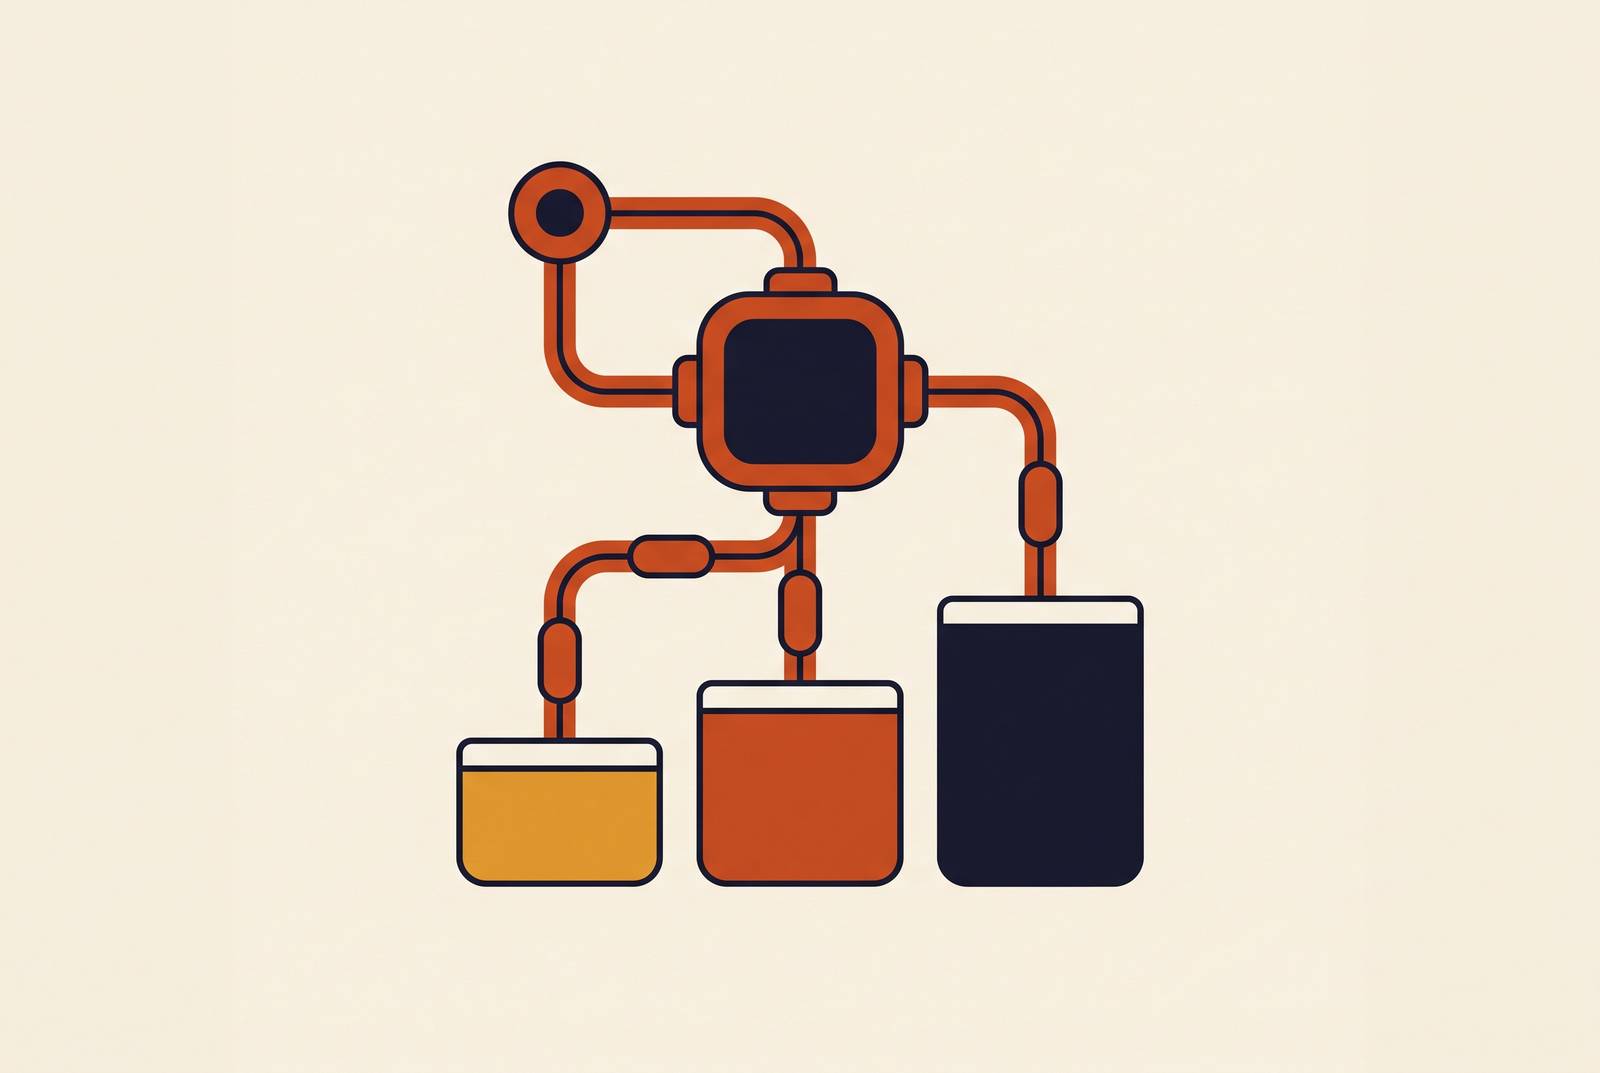
The schema above only works if it's enforced somewhere every request has to pass through, and application code isn't that place. A gateway sits in front of every provider call, which makes it the one place where a tagging rule applies to all traffic regardless of which team or service originated it, rather than depending on dozens of application teams to apply the same convention independently.
What a gateway enforces operationally breaks into a few distinct jobs. Access control issues a separate API key per team, so no application ever holds a raw provider key directly, and the key itself carries ownership identity before a single token gets billed. An observability layer logs prompts, responses, latency, token counts, and cost at the moment the request transits, rather than trying to reconstruct that picture from scattered logs afterward. A routing layer decides which model actually serves a request based on cost, latency, or compliance rules, and records which provider and model were actually used, a detail that matters directly once fallback routing changes which model served a given call and at what price. A caching layer distinguishes a cached response from a live inference call, since the two carry different cost structures and a chargeback report that treats them the same will overstate what a cache hit actually cost.
Enforcing the schema at this layer also means bad data can be caught at the door. A gateway can reject a request with an invalid team_id or quarantine it for review before it ever reaches the cost aggregation pipeline, instead of letting it pollute a report that finance pulls three weeks later. Because every request to a provider has to pass through the gateway layer to reach a model, enforcement there, rather than in application code or in a downstream observability pipeline, guarantees no call escapes attribution and that identity, cost, and token counts get captured the same way every time.
None of this comes free of risk. A gateway that routes around a provider outage can't route around itself, so a gateway outage is a real single point of failure to plan for in the deployment architecture, not a reason to avoid the pattern. Most mature deployments treat that risk the way they'd treat any other critical infrastructure dependency: with redundancy and monitoring, not avoidance.
Showback as a proving ground before chargeback moves money
Showback is the phase where the allocation model gets tested before real budgets depend on it, and skipping straight to chargeback is one of the most common reasons chargeback implementations collapse. The FinOps Foundation draws the line precisely: chargeback moves expenses onto a product or department's P&L, while showback displays the same charges but keeps them on a centralized budget, so the underlying data is identical and the financial consequence is not.
Treated well, showback is active work rather than a waiting period. It gives finance and engineering room to test whether ownership rules hold up, find the costs a team is likely to dispute, and clean up tagging errors or gaps in usage data before any of those numbers start moving actual budgets. A showback report with no named owner attached to each cost area leaves teams looking at a number with no one responsible for acting on it. A report that only shows a monthly total, without breaking it down by business unit, environment, model, or feature, gives finance no way to trace a spike back to its source. Waiting for perfectly clean tags before starting showback at all just delays the point where gaps get found, since showback is supposed to start with imperfect data and use early cycles to find exactly those gaps. And letting showback run indefinitely, long after ownership is clear and teams understand how the cost model works, turns a proving ground into a permanent holding pattern that never delivers the accountability chargeback is meant to provide.
The signal that a team is ready to move from showback to chargeback is that the people being charged have seen the numbers, understand how the allocation works, and don't dispute the methodology behind it.
The three chargeback models and the incentive structures they create
Choosing a chargeback model is less an accounting decision than a decision about which behaviors an organization wants to reward or discourage, and picking the wrong one can suppress adoption as thoroughly as having no chargeback model. Three models dominate among mature enterprises, and each one sends a different signal to the teams paying the bill.
Cost-plus charges a business unit the actual cost of its usage plus a markup meant to cover overhead, which creates direct financial accountability and supports recovering platform costs, though it only works if the overhead allocation behind the markup is designed with care. Fixed-fee charges every business unit a flat monthly amount regardless of how much it actually uses, which keeps billing simple but severs the link between consumption and cost, and once that link is gone, so is any incentive to use the system efficiently. The showback-to-chargeback hybrid is the model recommended for most enterprises: the central AI or IT function absorbs the fixed overhead, platform, security, governance, and literacy costs that every employee benefits from regardless of how much they personally use, while individual business units are charged only for the incremental use cases and workflow automation they commission on top of that baseline.
The costliest mistake is allocating fixed costs, like platform team salaries or licensing fees, to business units in proportion to how much they use the system. That approach creates a direct, perverse incentive: the moment one team ramps up usage to do its job well, a share of the fixed cost shifts onto that team, making its project look artificially expensive and punishing the exact behavior the platform exists to encourage. Fixed costs belong allocated by headcount, by seat count, or by a negotiated percentage, never by usage volume, because usage-based allocation of fixed costs turns growth into a liability instead of a signal of adoption.
Financial thresholds give this structure teeth without requiring a dispute over every line item. A common starting rule flags any business unit whose variance exceeds a fixed percentage or a fixed dollar amount, whichever number is larger, and anything crossing that line requires sign-off from the unit's owner before the books close. None of this works, regardless of which model is chosen, unless the teams being charged actually trust the number they're shown. Introducing chargeback before that trust exists produces disputes rather than accountability, and the organizational risk of a contested chargeback rollout runs higher than the risk of simply running showback a while longer first.
How fallback routing and outages create hidden chargeback distortions
Fallback routing exists to keep requests succeeding when a primary provider goes down, which makes it a reliability feature. It turns into a chargeback liability the moment the cost difference between the primary model and the fallback model goes uncaptured and unexplained at the business-unit level. A team that gets charged a sudden spike with no annotation explaining why has no way to tell whether that spike reflects its own usage decisions or an outage entirely outside its control.
The financial stakes here aren't trivial. Part of that gap comes from a cost that's easy to miss: prompt caches don't carry over when a request fails over to a different provider, so every active session pays full input price on its first request to the fallback model, right at the moment when request volume might already be elevated because of the outage itself. In a modeled three-hour outage, routing to a "best available" fallback cost materially more than routing to a price-matched one, a difference that was not a rounding error but a multiplier.
For chargeback to hold up under scrutiny, the attribution record has to capture which provider and model actually served a request. A call that gets rerouted to a fallback needs to carry the fallback's provider, model, and unit price in the record, not the primary's, since billing a business unit at the primary's rate for a call the fallback actually served misstates what happened. Teams shouldn't be billed at a fallback rate during an outage without that context attached. A defensible chargeback report flags or annotates outage-driven fallback charges separately, so a business unit can see clearly which part of its bill reflects normal usage and which part reflects a routing decision made on its behalf during conditions it didn't control and couldn't have prevented.